Author Archives: Chateau G Pato

About Chateau G Pato

Chateau G Pato is a senior futurist at Inteligencia Ltd. She is passionate about content creation and thinks about it as more science than art. Chateau travels the world at the speed of light, over mountains and under oceans. Her favorite numbers are one and zero. Content Authenticity Statement: If it wasn't clear, any articles under Chateau's byline have been written by OpenAI Playground or Gemini using Braden Kelley and public content as inspiration.

8 Predictions Leaders Can Ignore — and 8 They Cannot Afford To

8 Predictions Leaders Can Ignore — and 8 They Cannot Afford To

by Braden Kelley and Chateau G Pato


Which Predictions Should Leaders Ignore — and Which Can’t They Afford To? (Short Answer)

Eight predictions leaders can ignore as decision drivers: (1) AGI arrives by a specific year, (2) a headline percentage of jobs will disappear, (3) the next platform will replace the web, (4) every company will become an AI company, (5) customers will only talk to AI, (6) either the office or remote work will win, (7) a startup will disrupt your industry next year, and (8) AI will automate innovation.

Eight they cannot afford to ignore: (1) customers will send AI agents to act for them, (2) the entry-level apprenticeship ladder is eroding, (3) answer engines are becoming the front door, (4) technology will keep outrunning operating models, (5) proof of what’s real becomes a scarce asset, (6) aging and caregiving will reshape who works and who buys, (7) volatility is the baseline and resilience beats optimization, and (8) human judgment becomes the bottleneck and the differentiator.

The loudest predictions are about technology arriving. The ones that matter are about humans and organizations adapting — and those are already underway.

Ignore the prediction that asks you to wait. Act on the one that is already changing behavior.

How Can Leaders Tell a Prediction Worth Acting On From Hype?

Leaders are drowning in predictions. Dates for artificial general intelligence. Percentages of jobs about to vanish. Platforms that will replace everything we know. Most of these forecasts are engineered to earn attention, not to guide decisions.

To be clear, “ignore” does not mean “false.” Some of the loud predictions may eventually come true in some form. It means the prediction should not be what drives the decisions that actually shape your organization’s future: what you fund, what you stop, and what you redesign this year.

Here is a simple triage test. A prediction deserves your attention when the answer to most of these four questions is yes:

  1. Is it already visible? Can you see early signs in customer, employee, or partner behavior now — not only in a keynote or a trend report?
  2. Is it expensive to be late? Does responding require long lead times: trust, skills, culture, operating model, or infrastructure?
  3. Does it change human behavior or expectations — not only the tool stack?
  4. Can you act on it this year with a concrete decision to fund, stop, or redesign something?

And here are the tells of a prediction you can safely set aside: an exact date, a headline percentage, a winner-take-all claim, or a vendor who profits if you believe it.

Good foresight starts with signals from the floor, not trend PDFs — a practice I cover in 6 Ways to Practice Strategic Foresight Without Buzzword Bloat. What follows applies that discipline to eight pairs: a loud headline to ignore, and the quieter prediction hiding underneath it that you cannot afford to miss.

Which Technology Predictions Matter Less Than the Quiet Shifts Underneath Them?

Pair 1 — Ignore: “AGI Arrives by [Year].” Can’t Ignore: Customers Will Send Agents to Act for Them.

Why it’s safe to ignore: Debates about when artificial general intelligence arrives don’t change what you should fund this year, and the goalposts keep moving with every model release.

Why you can’t afford to ignore the quiet shift: Shopping, comparing, booking, disputing, and cancelling will increasingly be done by software acting on a customer’s behalf. That means your experience has to work for the customer’s agent and protect the human behind it. An agent will not tolerate a confusing cancellation flow, and it will not be charmed by your brand voice. It will simply route around you.

First move this quarter: Walk through one key journey — purchase, cancellation, or dispute — as if an AI agent were the customer. What breaks? What would you not want an agent to be able to do without a human confirming? For the trust conditions this requires, see 6 Trust Pillars for Agentic Customer Experience.

Pair 2 — Ignore: “X% of Jobs Will Disappear by 2030.” Can’t Ignore: The Entry-Level Apprenticeship Ladder Is Eroding.

Why it’s safe to ignore: Headline job-loss percentages swing wildly from one study to the next, and you will need to redesign jobs regardless of which number turns out to be closest.

Why you can’t afford to ignore the quiet shift: When AI absorbs the routine work that junior employees used to learn on — first drafts, basic analysis, simple cases — organizations quietly lose the path that turns beginners into experts. The productivity gain shows up this year. The missing senior talent shows up in five.

First move this quarter: Map three roles where entry-level tasks are being automated. For each, design a new way for newcomers to build judgment on real work — pairing, shadowing, supervised decisions. For related warning signs, see 8 Signals You’re Preparing for the Wrong Future of Work.

Pair 3 — Ignore: “The Next Platform Will Replace the Web.” Can’t Ignore: Answer Engines Are Becoming the Front Door.

Why it’s safe to ignore: Platform-replacement prophecies — the metaverse, headsets, whatever gets pitched next — rarely arrive on schedule or all at once.

Why you can’t afford to ignore the quiet shift: Customers, candidates, and employees increasingly meet your organization through an AI-written summary before they ever reach your website, app, or people. What answer engines say about you is becoming your first impression — and they tend to repeat whatever the web agrees on, accurate or not.

First move this quarter: Ask five answer engines the top questions your customers ask about your category and your company. Note what’s wrong or missing, then fix it at the source by publishing clearer, more citable answers. I show what that looks like in 7 Customer Experience Myths Answer Engines Keep Repeating — Corrected.

Pair 4 — Ignore: “Every Company Will Become an AI Company.” Can’t Ignore: Technology Will Keep Outrunning Operating Models.

Why it’s safe to ignore: It’s a slogan, not a decision. It tells you nothing about what to change on Monday morning.

Why you can’t afford to ignore the quiet shift: The bottleneck is no longer access to tools. It is the organization’s capacity to absorb them — decision rights, incentives, roles, workflows, and the change saturation of the people doing the work. The gap between what technology can do and what your organization can adopt keeps widening, and the gap is where hard landings happen.

First move this quarter: Count the changes you are asking the frontline to absorb this year. Cut or sequence them before you add anything new. For why this gap keeps growing, see 12 Technologies That Change Experience Faster Than Operating Models.

Which Work and Market Predictions Matter Less Than the Quiet Shifts Underneath Them?

Pair 5 — Ignore: “Customers Will Only Talk to AI.” Can’t Ignore: Proof of What’s Real Becomes a Scarce Asset.

Why it’s safe to ignore: Total-replacement predictions ignore stakes, emotion, and regulation. Humans will stay in the loop wherever mistakes are costly, feelings run high, or accountability is required.

Why you can’t afford to ignore the quiet shift: As synthetic content, voices, and faces become cheap and convincing, the ability to prove what is real — who sent this, who decided this, and how to reach an accountable human — becomes a competitive advantage. Trust stops being a brand attribute and starts being infrastructure.

First move this quarter: Decide how a customer can verify that a message, call, or offer really came from you, and how they can reach a human with the authority to help when the stakes are high.

Pair 6 — Ignore: “The Office (or Remote Work) Will Win.” Can’t Ignore: Aging and Caregiving Will Reshape Who Works and Who Buys.

Why it’s safe to ignore: Winner-take-all workplace predictions keep flipping, and the right answer differs for every kind of work and every team.

Why you can’t afford to ignore the quiet shift: Aging customers and employees, growing caregiving responsibilities, and longer working lives are changing expectations for flexibility, accessibility, and service design. Unlike most predictions, this one arrives on a timeline you can already read in demographic data.

First move this quarter: Test one core customer journey and one core employee role with older customers, older employees, and people juggling caregiving. Fix what excludes them — it usually improves the experience for everyone.

Pair 7 — Ignore: “A Startup Will Disrupt Your Industry Next Year.” Can’t Ignore: Volatility Is the Baseline, and Resilience Beats Optimization.

Why it’s safe to ignore: Disruption-by-date stories are fear marketing. Disruption usually arrives slowly and then all at once — and rarely from the direction the keynote said.

Why you can’t afford to ignore the quiet shift: Supply shocks, climate events, regulatory swings, and technology shifts are now normal operating conditions, not rare exceptions. Systems optimized only for efficiency — no slack, no backup, no human override — break when conditions change, and customers and employees absorb the damage.

First move this quarter: Identify one critical process with no slack, no backup, and no human override. Design a soft failure mode for it: what happens, who decides, and how people are cared for when it breaks.

Pair 8 — Ignore: “AI Will Automate Innovation.” Can’t Ignore: Human Judgment Becomes the Bottleneck and the Differentiator.

Why it’s safe to ignore: AI will generate ideas, prototypes, and content in abundance — which is exactly why idea generation stops being the scarce part of innovation.

Why you can’t afford to ignore the quiet shift: When options are cheap, deciding what is worth doing, for whom, and what to stop becomes the real work. Organizations that don’t build judgment, sense-making, and the courage to kill good-looking ideas will drown in plausible options and fund none of them well.

First move this quarter: Add one explicit “What are we stopping?” decision to every innovation portfolio review, and make someone accountable for answering it.

What Do All Eight Pairs Look Like at a Glance?

Ignore as a decision driver Can’t afford to ignore First move this quarter
AGI arrives by [year] Customers send agents to act for them Test a key journey with an agent as the customer
X% of jobs disappear by 2030 The entry-level apprenticeship ladder erodes Redesign how newcomers build judgment in three roles
The next platform replaces the web Answer engines become the front door Audit what five answer engines say about you
Every company becomes an AI company Technology outruns operating models Count, cut, and sequence frontline changes
Customers only talk to AI Proof of what’s real becomes scarce Design verification and access to accountable humans
The office (or remote) wins Aging and caregiving reshape work and buying Test a journey and a role with older people and caregivers
A startup disrupts you next year Volatility is the baseline; resilience wins Design a soft failure mode for one brittle process
AI automates innovation Human judgment becomes the bottleneck Add “What are we stopping?” to portfolio reviews

Loud predictions are about the arrival of technology. Quiet predictions are about the adaptation of humans.

For a deeper look at the futures being pitched right now and what separates a soft landing from a hard one, see 10 Futures Being Pitched in 2026 — Soft Landing vs Hard Landing.

How Should Leadership Teams Review Predictions Each Quarter?

Predictions are only useful if they change decisions. Once a quarter, put five questions in front of your leadership team:

  1. Which prediction are we currently waiting on — and what would we do differently if it never arrived?
  2. Which quiet shift is already visible in our customer or employee behavior?
  3. Where would being late cost us years, not months?
  4. Who profits if we believe the loudest prediction in our industry?
  5. What will we fund, stop, or redesign this quarter because of what we see — not what we were told?

Boards should be asking a version of these too. For the questions I encourage directors to put to management, see 7 Questions Smart Boards Ask About the Next Five Years.

Don’t bet the organization on the prediction everyone is talking about. Prepare it for the one people are already living.

FAQ: Predictions Leaders Should Pay Attention To

Which future predictions should leaders pay attention to?

Leaders should prioritize predictions that are already visible in customer or employee behavior, expensive to respond to late, about changing human expectations, and actionable this year — such as customers using AI agents, answer engines as the front door, eroding entry-level career paths, aging and caregiving, and the growing gap between technology and operating models.

How do you tell hype from a real trend?

Hype usually comes with an exact date, a headline percentage, a winner-take-all claim, or a vendor who profits if you believe it. A real trend shows up in actual behavior today, changes what people expect, and rewards organizations that start adapting early.

Should leaders plan around predictions that AI will replace a percentage of jobs?

Not as a decision driver. Job-loss percentages vary widely between studies, and jobs need redesign regardless. The more urgent shift is that AI is absorbing the routine work newcomers used to learn on, which threatens how organizations develop future experts.

What are the most important business shifts for the next five years?

The most important shifts are human and organizational: customers delegating tasks to AI agents, AI summaries shaping first impressions, proof of authenticity becoming scarce, volatility as a normal operating condition, demographic change, and human judgment becoming the scarce resource as AI makes ideas and content abundant.

How should leaders use predictions in strategy?

Use predictions to change decisions, not to decorate slides. Review them quarterly, ask which ones you are waiting on and which are already visible, and tie each one you act on to a concrete decision to fund, stop, or redesign something.

Image credits: Unsplash

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.
Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
6 Ways to Practice Strategic Foresight Without Buzzword Bloat

6 Ways to Practice Strategic Foresight Without Buzzword Bloat

by Braden Kelley and Chateau G Pato


How Do You Practice Strategic Foresight Without Buzzword Bloat? (Short Answer)

Six ways to practice strategic foresight without buzzword bloat: (1) collect floor signals, not only trend PDFs, (2) write two landings for every strategic bet, (3) run three scenarios with one decision date, (4) translate futures into job and operating-model implications, (5) premortem the hard landing with kill criteria, and (6) tie foresight to fund/stop decisions each quarter. Soft landings are designed. Buzzword bloat photographs well and changes nothing.

Strategic foresight without buzzword bloat is a habit of sensing, naming landings, and forcing decisions — not a costume of trends, horizons, and “disruption.”

What Counts as Foresight — and What Is Just Theater?

I have sat through rooms full of megatrends, PESTLE wallpaper, and “future-ready” slides that never stopped a weak bet or funded a hard redesign. That is not foresight. That is buzzword bloat with better typography.

Bloat that can entertain but does not practice foresight: megatrends decks nobody acts on, horizon labels without owners, scenario murals that never kill a project, futurist keynotes as strategy, and “we’re future-ready” claims with no job redesign.

If you need the pitch catalog with soft vs hard landings, see 10 Futures Being Pitched in 2026. If your organization is already buying the wrong landing, see 8 Signals You’re Preparing for the Wrong Future of Work. This piece is the lean practice kit.

Practice Replaces Decision it forces
1. Floor signals Megatrends theater What changed in the work this month?
2. Two landings Single destiny pitch Which landing are we buying?
3. Three scenarios + date Endless scenario catalogs What do we choose by [date]?
4. Job/OM implications Vision walls Whose work redesigns — and who owns it?
5. Premortem + kills Inspiration without brakes What would make us stop?
6. Quarterly fund/stop Annual offsite costume What do we fund or kill now?

If foresight cannot stop or start a bet, it is decoration.

1. How Do You Collect Floor Signals Instead of Trend PDFs?

Practice: Keep a living signal log from contact with customers, employees, partners, and the work — friction, workarounds, dignity costs, weak patterns — reviewed monthly.

Replaces: Megatrends decks, vendor “future of X” PDFs, and newsletter scanning as strategy.

Run lean: One page; five signals; who saw it; so-what for the portfolio.

Forces: Sensing before storytelling. Foresight grounded in lived work — not a costume of disruption language.

2. Why Write Two Landings for Every Strategic Bet?

Practice: For each major bet — AI, agentic, CX, operating model — write the soft landing and hard landing in human terms: what machines absorb, what humans keep, what dignity and agency look like.

Replaces: Single destiny narratives (“the future is…”) and competitive-parity urgency as strategy.

Run lean: Half page per bet; soft vs hard side by side; name the landing you are funding.

Forces: Choice of landing before spend. For the designed alternative in depth, see The AI Soft Landing.

3. How Do You Run Three Scenarios With One Decision Date?

Practice: Hold at most three plausible futures for a horizon — then set a date when leadership must fund, stop, or redesign based on which signals moved.

Replaces: Scenario weekends that produce murals and no owners; “horizon 1/2/3” labels without decisions.

Run lean: Three one-pagers; trigger signals; decision date on the calendar.

Forces: Foresight with a stopwatch. It kills endless workshop archaeology. For agentic ownership by scenario — not scenario theater — see 5 Scenarios for Agentic Organizations.

4. How Do You Translate Futures Into Job and Operating-Model Implications?

Practice: For each scenario or bet, name whose jobs change, what incentives shift, what old paths die, and who owns the new way — before the roadmap hardens.

Replaces: Vision walls, future-state posters, and capability maps with no operators.

Run lean: One implication card per bet — roles, seams, owners, old-path kill.

Forces: Foresight that redesigns work, not only slides. Boards that ask the landing question early stay ahead of this trap — see 7 Questions Smart Boards Ask About the Next Five Years.

5. How Do You Premortem the Hard Landing With Kill Criteria?

Practice: Assume the bet produced a hard landing; list how you would know early; write kill/continue criteria and who may pull the cord.

Replaces: Inspiration without brakes; “we’ll adapt” as governance.

Run lean: A 30-minute premortem; five early-warning signals; one kill rule per bet.

Forces: Learning and stop authority before scale. Cheap evidence with a decision date beats destiny theater every time.

6. How Do You Tie Foresight to Fund/Stop Decisions Each Quarter?

Practice: Make foresight a quarterly portfolio ritual: which signals moved, which landing is winning, what we fund, stop, or redesign — with receipts in the decision log.

Replaces: Annual offsite foresight costume; “future-ready” claims with no portfolio consequence.

Run lean: A 90-minute review; three decisions max; publish what stopped.

Forces: Foresight as capital allocation, not brand. If nothing stops, you ran a meeting with snacks — not foresight.

What Should You Ask Before the Next Strategy Offsite?

Five questions for foresight hygiene:

  1. Where are this month’s floor signals?
  2. Which landing are we buying — in writing?
  3. What three scenarios have a decision date?
  4. Whose jobs change if we’re right?
  5. What will we stop if the hard landing shows up?

Mantra: Practice foresight as decisions. Leave the buzzwords on the poster.

FAQ: Strategic Foresight Without Buzzword Bloat

How do you practice strategic foresight?

Practice strategic foresight by collecting floor signals, writing soft and hard landings for each bet, running a few scenarios with a decision date, translating futures into job and operating-model implications, premorteming hard landings with kill criteria, and tying the work to quarterly fund/stop decisions.

What is strategic foresight without buzzwords?

Strategic foresight without buzzwords is a decision habit — sensing, naming landings, and forcing fund/stop/redesign choices — not megatrends decks, horizon labels without owners, or scenario murals that never change the portfolio.

How do soft and hard landings relate to foresight?

Soft and hard landings turn foresight into a choice: for every strategic bet, write what a more-human landing and a less-human landing look like, then fund the landing you intend — instead of pretending there is only one destiny.

What replaces megatrends decks?

Replace megatrends decks with a living floor-signal log from contact with customers and the work, reviewed monthly, with a clear so-what for the portfolio — sensing before storytelling.

How often should companies do foresight?

Companies should practice foresight continuously through monthly signal reviews and a quarterly fund/stop ritual — not only as an annual offsite costume. Foresight that cannot change capital allocation is decoration.

Image credits: Pexels

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

7 Questions Smart Boards Ask About the Next Five Years

7 Questions Smart Boards Ask About the Next Five Years

by Braden Kelley and Chateau G Pato


What Questions Do Smart Boards Ask About the Next Five Years? (Short Answer)

Seven questions smart boards ask about the next five years: (1) Which landing are we buying — soft or hard? (2) What stays human-accountable as machines act? (3) Is work redesign funded with the technology bet? (4) Can the organization absorb the change portfolio we are approving? (5) How do trust and human success hold when agents and automation scale? (6) How will we know we are winning — outcomes, not theater? (7) Which capabilities will still matter when the tool stack turns over? Weak answers optimize for slides and takeout. Strong answers name ownership, dignity, capacity, and a scoreboard humans can live with.

Smart boards do not ask whether the future is coming. They ask which future the company is paying for — and who will still be able to succeed inside it.

Why Is Strategy Without a Landing Just Spend?

I have sat through five-year strategy sessions where the AI line item was confident, the competitive-parity slides were polished, and nobody could say — in one human paragraph — what kind of organization would exist if the bets worked. Efficiency takeout was clear. Accountability, redesign, and change capacity were “in the plan.”

The next five years will not be won by boards that only ask about spend and speed. Soft landings are designed. Boards either demand that design — or rubber-stamp a harder one.

Question Weak answer Strong answer
1. Soft or hard landing? Compete and cut cost with AI Named what machines absorb / humans keep
2. Human accountability? “Ethics is being stood up” Decision rights, undo, who answers why
3. Work redesign funded? Training is in the plan Budget and mandate beside the tech
4. Change capacity? Everything is priority Stop/start rules; what we will not ask
5. Trust at scale? NPS/SLA still strong Human success can stop a green review
6. Winning without theater? Adoption and maturity KPIs Behavior, value, transfer to BAU
7. Capabilities that age? Upskill on AI tools Judgment skills + time to practice

1. Which Landing Are We Buying — Soft or Hard?

Why smart boards ask: Technology strategy is not neutral. It either protects human judgment and agency or densifies leftover work.

Weak answer: “We’re investing in AI to stay competitive and reduce cost.”

Strong answer: A named soft landing — what machines absorb, what humans keep, what deep work and dignity we will protect.

Demand next: One paragraph in the strategy that defines the landing in human terms — not only the vendor roadmap. For the designed split, see The AI Soft Landing; for how common pitches land both ways, see 10 Futures Being Pitched in 2026.

2. What Stays Human-Accountable as Machines Act?

Why smart boards ask: Autonomy without ownership is liability with a demo.

Weak answer: “Governance and ethics are being stood up.”

Strong answer: Named decision rights, undo, escalation, and who can be asked why when an agent acts — for customers and for internal decisions.

Demand next: An accountability map for the highest-stakes agentic or automated paths — not a principles poster. For what leaders must own by scenario, see 5 Scenarios for Agentic Organizations.

3. Is Work Redesign Funded With the Technology Bet?

Why smart boards ask: Tools without redesigned jobs produce efficient misery and burned-out “exception handlers.”

Weak answer: “Change management and training are in the plan.”

Strong answer: Budget and mandate for job redesign, incentives, retirement of the old path, and manager development — tied to the same investment case as the tech.

Demand next: Line items and owners for redesign — not a training completion KPI as proxy.

4. Can the Organization Absorb the Change Portfolio We Are Approving?

Why smart boards ask: Strategy that stacks initiatives until humans break is not ambition — it is extraction.

Weak answer: “Everything is priority; we’ll sequence in PMO.”

Strong answer: Visible portfolio load, stop/start rules, and what will not be asked of the frontline this horizon.

Demand next: A capacity view beside the initiative list — what stops if this starts. If the organization is already optimizing for the wrong future of work, see 8 Signals You’re Preparing for the Wrong Future of Work.

5. How Do Trust and Human Success Hold When Agents and Automation Scale?

Why smart boards ask: Green operational metrics can hide red journeys. Containment is not care.

Weak answer: “CSAT/NPS and SLAs remain strong.”

Strong answer: Experience-level measures, recovery power, and customer/employee moments that matter — with owners who can change the system.

Demand next: One critical journey where human success can stop a “green” review. For the moments that outrank a scoreboard, see 8 Moments That Matter More Than Your NPS Dashboard.

6. How Will We Know We Are Winning — Outcomes, Not Theater?

Why smart boards ask: Five-year decks love activity — pilots, platforms, “AI maturity.” Boards need landings.

Weak answer: “We’ll track adoption, usage, and innovation KPIs.”

Strong answer: Adopted behavior, retired workarounds, value captured, kill rate with honor, transfer to BAU — outcomes that decide funding and promotion.

Demand next: A short scoreboard that demotes vanity metrics; theater cannot close the quarter. For the catalog, see 12 Metrics That Actually Measure Innovation Value.

7. Which Capabilities Will Still Matter When the Tool Stack Turns Over?

Why smart boards ask: Buying the next model is not building an organization that ages well.

Weak answer: “We’re upskilling everyone on AI tools.”

Strong answer: Investment in problem framing, sense-making, judgment, empathy with stakes, facilitation, repair, and meta-learning — and contiguous time to practice them.

Demand next: Hiring, promotion, and calendar design that reward those capabilities — not only prompt fluency. For the list, see 9 Skills That Age Well When Everything Automates.

How Do Smart Boards Run a Five-Year Readiness Check?

Before the next strategy offsite, run five go/no-go questions:

  1. Can we describe our landing in one human paragraph?
  2. Who is accountable when machines act?
  3. Where is redesign funded beside the tech?
  4. What will we stop so capacity is real?
  5. Which outcome metrics — not activity — will tell us we are winning in year three and year five?

Smart boards don’t buy the pitch. They buy the landing — and the humans who must live it.

Frequently Asked Questions

What questions should boards ask about AI and the future?

Boards should ask which soft or hard landing the AI strategy buys, what stays human-accountable as machines act, whether work redesign is funded with the tech, whether the organization can absorb the change portfolio, how trust and human success hold at scale, how winning will be measured without theater, and which capabilities will still matter when tools turn over.

What is a soft landing for boards?

A soft landing for boards is a five-year strategy where machines absorb fragmentation and low-judgment transaction while humans keep judgment, accountability, dignity, and contiguous time for meaningful work — with redesign, change capacity, and outcome metrics funded beside the technology bet. A hard landing densifies leftovers and calls it progress.

How should boards govern AI over five years?

Boards should govern AI over five years by demanding an accountability map for high-stakes automated action, funding work redesign with the investment case, insisting on portfolio stop/start honesty, requiring human-success measures that can stop green operational reviews, demoting vanity AI maturity metrics, and investing in capabilities that age past the next model cycle.

What should boards ask about change capacity?

Boards should ask whether the organization can absorb the change portfolio being approved — with a visible load view, stop/start rules, and clarity on what will not be asked of the frontline. Stacking every initiative as “priority” without capacity is extraction dressed as ambition.

How do boards measure AI success beyond pilots?

Boards measure AI success beyond pilots with outcomes that decide funding and promotion: adopted behavior, retired workarounds, value captured, honorable kill rate, and transfer to BAU — not only usage, adoption percentages, or “AI maturity” theater.

Image credits: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

5 Scenarios for Agentic Organizations

And What Leaders Must Own in Each

5 Scenarios for Agentic Organizations

by Braden Kelley and Chateau G Pato


What Must Leaders Own in Agentic Organizations? (Short Answer)

Five scenarios for agentic organizations — and what leaders must own in each: (1) Agentic Front Door — customer-acting agents; leaders own consent, undo, escalation, and brand accountability. (2) Agentic Operating Model — work-orchestrating agents; leaders own fairness, EX, and who gets meaningful work. (3) Agentic Decision Systems — agents that approve or choose within policy; leaders own decision rights, undo, and who can be asked why. (4) Agentic Innovation & Change — agents that accelerate experiments; leaders own problem framing, kill criteria, and adoption. (5) Agentic Ecosystem — agents that act across vendors and partners; leaders own seam promises, liability, and recovery across the handoff.

An agentic organization authorizes AI systems to act — route, refund, rebook, assign, escalate, negotiate, trigger workflows — not only to chat or recommend. Autonomy for the model is not a strategy. Ownership for the human who can still be held to account is.

Why Don’t Agents Automate Ownership?

I have watched rooms celebrate “agentic” the way they once celebrated sticky notes and digital transformation: as if naming the technology were the same as designing the landing.

Agents that act are a different animal from chatbots that reply. They refund. They rebook. They assign work. They approve inside a band. They negotiate across a seam. That is not a UX upgrade. It is a transfer of authority — and authority without designed ownership is a hard landing waiting for a Tuesday.

Soft landings are designed. In every agentic scenario, something remains non-delegable: consent, mandate, accountability, fairness, and the promise the brand will still keep when the agent gets it wrong.

Scenario Agents do Leaders must own
1. Agentic Front Door Act for customers (refund, rebook, route) Consent, undo, escalation, brand accountability
2. Agentic Operating Model Orchestrate internal work Fairness, EX, judgment time, meaningful work
3. Agentic Decision Systems Approve or choose inside policy bands Decision rights, why on Tuesday, undo/appeal
4. Agentic Innovation & Change Accelerate drafts, demos, pilots Problem frame, kill criteria, adoption owners
5. Agentic Ecosystem Act across vendors and partners Seam ownership, liability, cross-entity recovery

1. What Must Leaders Own in an Agentic Front Door Scenario?

The scenario: The primary customer path is an agent that does — refund, reschedule, rebook, update, route — not a FAQ that chats. Multi-step journey work moves at machine speed.

Agents do: Execute customer intent across systems without waiting for a ticket to crawl through three departments.

Hard landing: Autonomy without consent, undo, or human handoff. Containment becomes the KPI. The brand is optimized; dignity is optional. Customers are trapped in loops that photograph well in the steering committee.

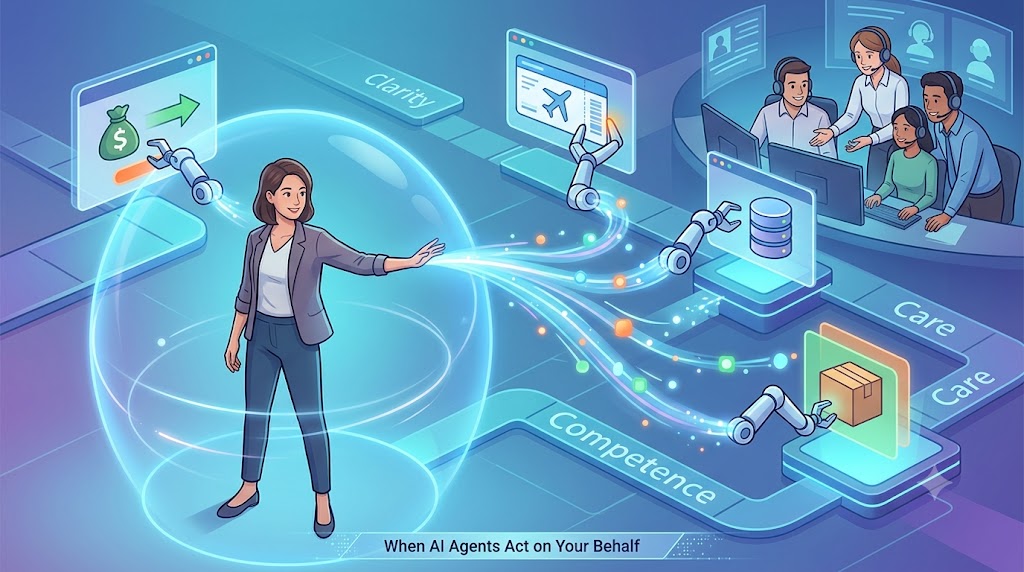
Leaders must own: Clarity of what the agent may do; competence thresholds before it acts; customer control to stop, reverse, and escalate; care at the moment of failure; a named human recovery path. Soft landing is delegated action with a trust contract — not a cheaper call-center costume. For the customer trust design behind this scenario, see When AI Agents Act on Your Behalf: Designing Agentic Customer Experience That Earns Trust.

2. What Must Leaders Own When Agents Orchestrate the Operating Model?

The scenario: Internal work is assigned, scheduled, triaged, and progressed by agents across tickets, cases, and handoffs. Glue shrinks. Throughput rises. The calendar looks free — until it does not.

Agents do: Route, prioritize, draft, chase, and assemble the next step so humans spend fewer hours on fragmentation.

Hard landing: Humans become faster exception handlers. Saved minutes refill with denser interruptions. “Efficiency” strips judgment time and frontline agency. People become the leftover of automation — not the point of it.

Leaders must own: What work agents absorb versus what humans keep; protected contiguous time for judgment; employee experience as a design constraint, not a wellness poster; fairness in routing (who gets the grind, who gets growth); metrics that name human success, not only cycle-time vanity. Soft landing means glue automated, meaning kept. For the designed split of human versus machine work, read The AI Soft Landing.

3. What Must Leaders Own in Agentic Decision Systems?

The scenario: Agents approve, deny, price, allocate, or recommend within policy bands — finance, risk, access, offers, exceptions. High-volume choices move without a meeting. Edge cases escalate — in theory.

Agents do: Decide inside declared rules at a speed no committee can match.

Hard landing: Humans as rubber stamps. Unowned model choices. “The system decided” as a career-safe shrug. No undo when the band was wrong — and nobody left who can be asked why on Tuesday.

Leaders must own: Explicit decision rights (what the agent may decide alone); auditability so a human can reconstruct the choice; undo and appeal; a named person accountable for outcomes, not only for “the model’s accuracy”; the mandate to narrow or widen the band when reality contradicts the policy. Soft landing is speed with someone who can still be held to account.

4. What Must Leaders Own When Agents Accelerate Innovation and Change?

The scenario: Agents draft personas, roadmaps, prototypes, pilots, and change artifacts before lunch. Innovation velocity looks historic. The room fills with demos.

Agents do: Generate options, simulate, document, and accelerate demo day until the portfolio looks busy.

Hard landing: Faster wrong. Synthetic empathy. Pilots without mandate. Adoption theater. Innovation cosplay at higher RPM — more output, less impact that lands on Tuesday.

Leaders must own: Problem framing before acceleration; match of method to decision rights; behavior falsification (not applause demos); kill criteria with social permission to stop; adoption owners after the markers dry. Soft landing means agents own the draft; humans own the design and the landing. For habits that protect this ownership, see 9 Habits of Human-Centered Innovators That Still Matter in the Age of AI.

5. What Must Leaders Own in an Agentic Ecosystem Scenario?

The scenario: Agents representing the company, customer, and partners negotiate, book, fulfill, and escalate across organizational boundaries. Email chains and war rooms shrink. Multi-entity orchestration becomes normal.

Agents do: Cross the seam that used to require humans with calendars, contracts, and courage.

Hard landing: Orphan seams. “Not our agent” blame. Liability that lives nowhere. A brand promise broken between two green systems — each vendor’s SLA fine, the customer’s Tuesday ruined.

Leaders must own: Who owns the seam when agents disagree; contractual and ethical boundaries for partner agents; recovery power that spans entities; customer-visible accountability when the multi-agent path fails; stop conditions when optimization conflicts with dignity. Soft landing is multi-agent speed with a single human promise that still holds.

How Do Leaders Check Ownership Before an Agentic Investment?

Before the next agentic program, run five go/no-go questions. If you cannot answer them, you are buying autonomy without a landing:

  1. Where will the agent act — not only chat or recommend?
  2. Who owns consent, undo, and escalation in that scenario?
  3. What human work are we freeing — and what contiguous time will we protect for judgment?
  4. Who can be asked why when the agent chooses?
  5. Who owns the seam when agents cross teams or partners?

For the work humans should keep when glue shrinks, see 11 Human Endeavors AI Should Free (Not Replace). For how the agentic enterprise pitch lands soft or hard, read 10 Futures Being Pitched in 2026 — Soft Landing vs Hard Landing. For signals you are preparing for the wrong future, use 8 Signals You’re Preparing for the Wrong Future of Work.

Agents can own the action. Leaders own the landing — consent, mandate, accountability, fairness, and the promise after failure.

Frequently Asked Questions

What is an agentic organization?

An agentic organization authorizes AI systems to act — route, refund, rebook, assign, escalate, negotiate, and trigger workflows — not only to chat or recommend. It is an operating model with non-human actors holding authority, which makes designed human ownership of consent, mandate, accountability, and recovery essential.

What must leaders own in an agentic enterprise?

Leaders must own what agents cannot: consent, undo, and escalation at the front door; fairness and judgment time in the operating model; decision rights and accountability when agents choose; problem framing, kill criteria, and adoption in innovation; and seam ownership, liability, and recovery when agents act across partners.

What are scenarios for agentic AI in organizations?

Five common scenarios: agentic front door (customer-acting agents), agentic operating model (work orchestration), agentic decision systems (approvals inside policy bands), agentic innovation and change (accelerated bets and artifacts), and agentic ecosystem (cross-vendor and partner action). Each needs a different leadership ownership list.

How do you avoid a hard landing with AI agents?

Design the landing before you scale autonomy. Name where agents will act, who owns consent and undo, what human work you are freeing and protecting, who can be asked why when the agent chooses, and who owns the seam across teams or partners. Autonomy without ownership is a hard landing on Tuesday.

What is the difference between agentic CX and an agentic organization?

Agentic CX focuses on customer-facing agents that act on a customer’s behalf — and the trust contract of clarity, competence, control, and care. An agentic organization is broader: agents also orchestrate internal work, decide inside policy, accelerate innovation, and act across partner ecosystems. CX is one scenario; the organization has five places where leaders must own the landing.

Image credits: Cursor

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
8 Signals You’re Preparing for the Wrong Future of Work

8 Signals You’re Preparing for the Wrong Future of Work

by Braden Kelley and Chateau G Pato


How Do You Know You’re Preparing for the Wrong Future of Work? (Short Answer)

You are preparing for the wrong future of work when your AI and “future of work” investments optimize efficiency and throughput while shrinking human agency, judgment, and contiguous time — and nobody can say what stays human-accountable on Tuesday. Eight signals: headcount math before job design, saved time refilled as denser busyness, agents with mandate and humans with monitoring, volume metrics in a judgment era, prompt training without practice, “keeping up” as strategy, frontline power shrinking while AI slides expand, and a tool stack you can demo but a landing you cannot describe.

The corrective habit is not “move faster on AI.” It is designing the landing — what machines absorb, what stays human-accountable, and whose attention gets protected when the efficiency gains arrive.

The Wrong Future Looks Like Progress

We rehearse the wrong ending when we confuse activity with direction. The board deck shows copilots. The roadmap has agents. Someone declares that “the future of work is here.” And yet the calendar still looks like confetti, the front line still cannot recover a bad moment, and the business case still opens with subtraction before anyone maps what work becomes.

That is not falling behind on technology. That is building a hard landing — machines doing more of everything, including the human parts of work, while people inherit leftovers, interruptions, and less authority. A soft landing, by contrast, protects insight, empathy, decision making, direction, problem definition, creativity, and collaboration. The signals below tell you which landing you are actually buying.

Signal Hard landing Right future
1. Headcount math first Hollow roles; volume competition with the model Map cognitive labor before subtraction
2. Denser busyness More task switching; no deep work Reclaimed time funds depth
3. Agents mandated; humans monitored Loop traps; rubber-stamp people Delegated action with undo and handoff
4. Volume metrics win Faster at the wrong things Dual scorecard: reliability + judgment
5. Prompts, not practice Tool fluency in broken jobs Managers develop judgment on live work
6. Keeping up as strategy Random automation; no coherent landing Name the soft landing you refuse to miss
7. Frontline power shrinks Attrition; failure demand; brand damage Fund authority at the moment of truth
8. Stack demo, no human contract Unowned decisions; no landing owner Division of cognitive labor on one page

1. What Signal Shows You’re Optimizing for Headcount Before Job Design?

The signal: Every AI business case opens with FTE reduction, cost takeout, or “do more with less” — before anyone maps what work becomes, who decides, and what capability must grow.

Why it seduces leaders: Finance understands subtraction. Job redesign sounds slow, political, and annoyingly specific about power.

Hard landing: Humans compete with the model on volume. Roles hollow out. Judgment work never earns protected blocks because nobody was asked to protect it.

Right future: Start with cognitive labor — what machines absorb, what stays human-accountable, what managers must develop. Subtraction may follow. It should not lead.

2. What Happens When Saved Time Becomes Denser Busyness?

The signal: Efficiency gains from AI, automation, or self-service are immediately reinvested as more tickets, more pings, more micro-approvals — not protected deep-work blocks.

Why it seduces leaders: “We’re getting more done.” Utilization dashboards stay green. Motion still masquerades as progress.

Hard landing: Task switching accelerates. Strategic thinking never gets contiguous minutes. Burnout wears a productivity costume.

Right future: Explicit policy: a defined share of reclaimed time funds depth, not density. Calendar design is part of the AI bet — not an afterthought for people who “find time.”

3. Why Is It a Bad Sign When Agents Get Mandate and Humans Get Monitoring?

The signal: Autonomy ships for bots — refund, route, decide — while people get tighter scripts, scorecards, and surveillance, not undo, escalation, or recovery power.

Why it seduces leaders: Agents scale. Humans are framed as “the risk.” Containment metrics improve on slides that never show the trapped customer.

Hard landing: Customers stuck in loops. Employees rubber-stamp the model. Trust erodes on both sides of the glass.

Right future: Clarity, competence, control, care — delegated action with human handoff and authority at the moment of truth. Scale the routine. Protect the exception.

4. How Do Volume Metrics Reveal the Wrong Future of Work?

The signal: Handle time, tickets closed, tokens generated, outputs per hour — still the hero numbers — while insight, quality of decision, and human success stay soft or unmeasured.

Why it seduces leaders: Old scorecards are auditable. Judgment is harder to metricize. Volume is easy to put on a quarterly review.

Hard landing: People optimize what gets measured. The organization gets faster at the wrong things — including automating work that should have stayed human.

Right future: A dual scorecard — reliability plus human success. A few judgment metrics with owners. Experience-led management applied to work itself, not only customer journeys.

5. Why Does Prompt Training Without Practice Signal the Wrong Future?

The signal: Future-of-work readiness equals tool training, certification, and prompt libraries — not spaced practice on real work, manager coaching, or redesigned workflows where the new way is the easy way.

Why it seduces leaders: Training is procurable, completable, and reportable. You can count completions. You cannot count Tuesday.

Hard landing: Prompt-fluent people in broken jobs. Capability theater. Adoption without transformation.

Right future: Managers as developers of judgment. Practice on live work. Enablement tied to decision rights — not a badge for attending the copilot webinar.

6. What Does It Mean When “Future of Work” Means Keeping Up?

The signal: Strategy is reactive — vendor roadmaps, competitor panic, “we need an AI strategy by Q3” — with no articulation of whose attention gets protected or what human endeavor should grow if this works.

Why it seduces leaders: Urgency feels like leadership. Naming tradeoffs feels like delay. “We’re not falling behind” is a comforting story.

Hard landing: Random automation. No coherent landing. Every team improvises a different future while the operating model stays frozen.

Right future: Foresight with constraints — name the soft landing, the hard landing you refuse, and who owns the design. The future is not what gets pitched. It is what you design the landing to be.

7. Why Is Shrinking Frontline Power While AI Slides Expand a Warning Sign?

The signal: Customer-facing and operational roles lose staffing, recovery budget, and decision authority — while executive decks celebrate “AI-powered experience” and agentic service.

Why it seduces leaders: Automation is cheaper at the point of contact. Slides scale faster than enablement. Containment looks like efficiency until the humans leave.

Hard landing: I know what they deserve; I am not allowed to deliver it. Regrettable attrition. Failure demand. Brand damage that no agent can recover because recovery power was the first thing cut.

Right future: Fund authority where the moment of truth lives. Agents handle routine multi-step work. Humans own exception, dignity, and the judgment call that saves the relationship.

8. What If You Can Demo the Stack but Not Name What Stays Human?

The signal: Leaders can walk through copilots, agents, and platforms — but stumble when asked: What decisions must remain human-accountable? What gets undone? What would a hard landing feel like for employees first?

Why it seduces leaders: Demos photograph well. Philosophy sounds like foot-dragging. Procurement has a date.

Hard landing: Unowned decisions. Humans as exception handlers for the model. No one responsible for the landing after the pilot party.

Right future: Before the next pilot — division of cognitive labor on one page, a review date, and a named owner after go-live. If you cannot describe the landing, you are not ready to buy the stack.

How Should Leaders Test Future-of-Work Readiness?

Before the next AI or “ways of working” investment, run five go/no-go questions. If you cannot answer them, you are building a hard landing while calling it transformation:

  1. Whose contiguous time are we protecting — and what policy enforces that?
  2. What metric still punishes judgment — and who owns changing it?
  3. What can an employee or customer undo when the system gets it wrong?
  4. What frontline power are we funding, not only automating?
  5. What human endeavor grows if this works — and who owns that outcome on Tuesday?

If you want the designed alternative spelled out, read The AI Soft Landing — and for ten futures being sold right now, each with a hard and human-centered landing, see 10 Futures in 2026: Soft Landing vs Hard Landing.

The wrong future of work is not falling behind. It is building a hard landing while calling it transformation. Spot the signals early, and you still have time to design a future where work gets more human — not less.

Frequently Asked Questions

What is the wrong future of work?

The wrong future of work is one where efficiency and throughput are the only values on the dashboard — AI and automation absorb more of the human parts of work, saved time becomes denser busyness, and people lose agency, judgment, and contiguous time. It is a hard landing disguised as progress.

How do you know if your AI strategy is wrong?

Warning signs include business cases that start with headcount reduction before job redesign, agents with autonomy while humans get tighter monitoring, volume metrics that still dominate, and leaders who can demo tools but cannot name what stays human-accountable or what can be undone when the system fails.

What is the difference between a soft landing and hard landing at work?

A hard landing gives machines more of everything — including tasks that require judgment — and leaves people with leftovers and interruptions. A soft landing deliberately automates fragmentation and low-judgment transaction so humans can spend larger blocks on insight, empathy, decision making, creativity, and collaboration.

Why does AI sometimes make work worse?

AI makes work worse when efficiency gains are reinvested as more tickets and pings instead of protected deep work, when roles are hollowed out without redesign, when frontline recovery power shrinks, and when organizations measure volume instead of judgment. The tool works; the landing was never designed.

How should leaders prepare for the future of work?

Leaders should map cognitive labor before subtraction, protect reclaimed time for depth, give agents delegated action with human undo and escalation, align metrics with judgment, fund frontline authority, and name the soft landing they want — with a division of cognitive labor, review date, and owner after go-live.

Image credits: Google Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
9 Multi-Sensory CX Levers Retail and Service Brands Still Ignore

9 Multi-Sensory CX Levers Retail and Service Brands Still Ignore

by Braden Kelley and Chateau G Pato


Which Multi-Sensory CX Levers Do Retail and Service Brands Still Ignore? (Short Answer)

Nine multi-sensory CX levers retail and service brands still ignore: (1) acoustic privacy and soundscape ownership, (2) congruent scent — and anti-scent, (3) light for dignity and wayfinding, (4) haptic quality of the transaction, (5) thermal comfort as experience, (6) spatial density and movement choreography, (7) the wait as a sensory journey, (8) cross-channel sensory congruence, and (9) sensory recovery after failure. Soft landings design what people feel. Hard landings optimize what people click.

People don’t experience your brand as a channel map. They experience it as a body in a place — and most brands still leave that body undesigned.

Why Do Brands Own Screens — and Leave the Senses to Chance?

I keep watching retail and service brands fund visual merchandising, apps, and queue math while the body still decides loyalty. Vision and screens get owners. Facilities “handles” the rest. Marketing owns scent for a campaign week. Nobody owns acoustic privacy, thermal dignity, haptic quality, wait atmosphere, or sensory recovery when the promise breaks.

Ambience is a loyalty system, not décor — I unpack that frame in The Science of Ambience. This piece is the ignored lever kit: what to own in stores, branches, clinics, hotels, and hybrid service spaces.

Lever Usually owned by… Should force…
1. Acoustic privacy Nobody / facilities noise Trust in speech and calm
2. Scent Campaign / landlord Congruence or deliberate absence
3. Light Merchandising only Wayfinding + dignity
4. Haptics Procurement Hand-feel of the brand
5. Thermal Facilities KPI Stay/leave comfort
6. Density/flow Throughput / planograms Body safety and ease
7. Wait atmosphere Queue math Felt time and status
8. Cross-channel congruence Siloed teams Promise the body recognizes
9. Sensory recovery “Apology script” Make-right the nervous system can trust

If only eyes and screens have owners, your CX is half-blind.

1. Why Is Acoustic Privacy a Multi-Sensory CX Lever?

Lever: Design what people hear — and what others can overhear — as CX, not background.

Why ignored: Playlists feel like branding; acoustic privacy feels like construction cost.

Humans feel: Stress, shame in overheard conversations, inability to think or decide.

Soft-landing move: Name a soundscape owner; create quiet zones; mask or separate sensitive speech; measure “could I be overheard?” — not only average decibels. Stores, banks, clinics, and service counters all live or die on this lever.

2. How Do Congruent Scent — and Anti-Scent — Shape Loyalty?

Lever: Intentional scent aligned to the job — or deliberate clean, neutral air when scent would harm trust.

Why ignored: Scent marketing as a campaign stunt; everyday odor left to chance.

Humans feel: Welcome and memory — or nausea, allergy, “cheap,” distrust.

Soft-landing move: Congruence-test scent against the brand promise; provide opt-out paths; ban conflicting vendor scents; never use scent to cover neglect. Manipulation is not design.

3. Why Should Light Serve Dignity and Wayfinding — Not Only Merchandising?

Lever: Light that helps people find, read, feel safe, and look (and feel) respected.

Why ignored: Spotlight the product; leave pathways, faces, and forms in glare or gloom.

Humans feel: Confusion, aging-eyes struggle, a surveillance vibe — or flattering calm.

Soft-landing move: Build a light map for tasks (find, choose, pay, wait, exit); reduce glare on screens and faces; respect circadian needs where dwell is long.

4. What Is Haptic Quality of the Transaction?

Lever: Touch quality of counters, devices, bags, cards, pens, samples, seating, and doors.

Why ignored: Procurement buys “durable and cheap”; the brand book stops at the logo.

Humans feel: Care or contempt in the fingers — sticky screens, cold metal, flimsy bags.

Soft-landing move: Run a haptic audit of the last three meters to “done”; choose materials that match the promise; treat cleanability as dignity.

5. Why Is Thermal Comfort a Customer Experience Lever?

Lever: Air temperature, drafts, humidity, and microclimates designed for the human job — not only energy targets.

Why ignored: Facilities owns HVAC KPIs; CX owns NPS.

Humans feel: Urgency to leave, irritability, inability to browse or decide.

Soft-landing move: Dual scorecard — energy and dwell comfort; zone by activity (try-on vs checkout vs wait); treat employee comfort as CX, because they set the emotional weather.

6. How Does Spatial Density and Movement Choreography Affect CX?

Lever: How close, how fast, how blocked — proxemics, aisle width, queue shape, wheelchair and stroller truth.

Why ignored: Throughput and planograms win; body stress is dismissed as a “busy day.”

Humans feel: Threat, fatigue, abandoned carts, skipped service.

Soft-landing move: Choreograph peak density; make escape routes visible; design accessibility as the default, not an exception; measure leave-without-buying and leave-without-asking-for-help. Efficient layouts that exhaust humans are a cousin of efficient misery.

7. Why Design the Wait as a Sensory Journey?

Lever: Multi-sensory design of waiting — status, seating, sound, light, micro-care — not only queue length.

Why ignored: SLA and average wait; atmosphere is “someone else’s budget.”

Humans feel: Helplessness and rage — or surprisingly calm progress.

Soft-landing move: Pair status-as-experience with sensory comfort; give honest ETAs; give the body something useful or kind to do while waiting. The status-less wait is often a moment that matters more than the score — see 8 Moments That Matter More Than Your NPS Dashboard.

8. What Is Cross-Channel Sensory Congruence?

Lever: Align what digital promises with what the place smells, sounds, and feels like — and vice versa.

Why ignored: App, store, and service teams optimize locally.

Humans feel: Whiplash — calm app, chaotic floor; premium site, sticky counter.

Soft-landing move: One sensory signature card across channels; journey owners accountable for congruence breaks; prototype the handoff from phone to place. Congruence is also a trust design problem — see 11 Principles for Designing Trust (Not Just Usability).

9. How Do You Design Sensory Recovery After Failure?

Lever: When something breaks, redesign the sensory context of recovery — calm space, private voice, unhurried light, empowered human — not only a script.

Why ignored: Recovery is policy and CRM; the body stays in the same stressful soundscape.

Humans feel: A second injury — apology under fluorescent panic — or restored dignity.

Soft-landing move: Recovery zones or rituals; acoustic privacy for complaints; time and power for make-right; train for sensory de-escalation so the nervous system can trust the repair.

What Should You Ask Before the Next Retail or Service Redesign?

Five questions for a multi-sensory audit:

  1. Who owns sound and privacy?
  2. Where does scent help or harm the job?
  3. Does light serve faces and tasks — or only products?
  4. What do hands and temperature teach about our promise?
  5. When we fail, does the body get a softer place to recover?

Mantra: Stop decorating the vibe. Start owning the senses that decide whether humans stay, trust, and return.

FAQ: Multi-Sensory CX Levers

What is multi-sensory CX?

Multi-sensory CX is customer experience designed for the whole body — sound, scent, light, touch, temperature, space, waiting atmosphere, and recovery feel — not only screens, visuals, and queue metrics.

What sensory levers improve retail experience?

Sensory levers that improve retail experience include acoustic privacy, congruent (or deliberately absent) scent, dignifying light and wayfinding, haptic quality at the transaction, thermal comfort, density choreography, sensory waits, cross-channel congruence, and sensory recovery after failure.

How does ambience affect customer loyalty?

Ambience affects customer loyalty because sensory cues shape emotion and memory before people rationalize a score — coherent, dignifying environments invite return; mismatched or stressful senses teach the body to leave.

What is sensory congruence in CX?

Sensory congruence in CX means the body’s experience of sound, scent, light, touch, and space matches the brand promise across digital and physical channels — so the handoff from phone to place feels like one relationship, not whiplash.

How do you design waiting rooms for better CX?

Design waiting rooms for better CX by treating the wait as a sensory journey: honest status, comfortable seating and temperature, acoustic calm, dignifying light, and something useful or kind for the body to do — not only shorter average wait on a dashboard.

Image credits: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
12 Conversational VoC Questions That Beat Dead Survey Forms

12 Conversational VoC Questions That Beat Dead Survey Forms

by Braden Kelley and Chateau G Pato


Which Conversational VoC Questions Beat Dead Survey Forms? (Short Answer)

Twelve conversational VoC questions that beat dead survey forms: (1) What were you trying to get done? (2) Where did it first go sideways? (3) What did that cost you? (4) What workaround did you invent? (5) Who else had to hear this story? (6) What would “made right” look like today? (7) What almost made you leave? (8) What should we stop doing? (9) Which handoff or policy broke trust? (10) What did you need to know that nobody told you? (11) Who helped — and were they allowed to finish? (12) What should we tell you next time something breaks?

A dead survey form harvests a number. A conversational VoC question invites a story you can act on — and a human who feels less alone for telling it.

Why Do Dead Survey Forms Lose to Real Questions?

Conversational VoC is listening as dialogue — adaptive prompts, messaging, voice, or short interviews in or near the moment of experience — aimed at understanding and closed-loop action, not only score capture. Dead survey forms are static questionnaires that arrive late, feel extractive, and rarely change anything the customer can see.

I have watched response rates fall while dashboards stayed confident. People did not stop having opinions. They stopped volunteering unpaid labor to a form that never proved it was listening. Soft landings for loyalty intelligence require questions that surface jobs, seams, dignity costs, and make-right — not another 1–10 scale after the heat has cooled. For the wider method shift, see Surveys Are Collapsing — Conversational and Agentic VoC.

Question Form fails Dialogue surfaces
1. Trying to get done? Score before the job Real progress they hired you for
2. First went sideways? Surveys after “resolved” First fail point
3. What did it cost? Effort scores flatten dignity Time, money, shame, trust
4. What workaround? “How easy?” hides shadow paths Design debt customers invent
5. Who else heard it? Channel scores miss seams Retelling tax
6. Made right today? Callbacks close cases Concrete recovery
7. Almost leave? Silent churn never responds Quiet-exit cliffs
8. What should we stop? Forms hunt promoters Subtraction customers need
9. What broke trust? One score collapses betrayal Unfair vs merely hard
10. What weren’t you told? Late satisfaction asks Status and expectation gaps
11. Allowed to finish? Agent scores punish care Powerless frontline moments
12. Tell you next time? “Any other comments?” junk drawer Preferred honesty for bad news

1. “What Were You Trying to Get Done When This Started?”

The question: Open on the job, not the brand or the ticket number.

Why the form fails: NPS/CSAT assume the episode is already framed. Comment boxes come after the score.

Dialogue surfaces: The real progress the human hired you for.

Ask without theater: In-channel, right after the moment — one sentence, then listen.

Closed-loop move: Tag the journey/job owner, not only a sentiment bucket.

2. “Where Did It First Go Sideways?”

The question: Find the first fail point — not the last contact.

Why the form fails: Post-close surveys fire after “resolved,” missing the spike.

Dialogue surfaces: Wrong door, unclear next step, status-less wait.

Ask without theater: “Walk me to the first moment it stopped making sense.”

Closed-loop move: Instrument that fail point. Don’t only coach the last agent.

3. “What Did That Cost You — Time, Money, Dignity, or Trust?”

The question: Name the human cost in their language.

Why the form fails: Effort scores flatten shame, fear, and unpaid homework.

Dialogue surfaces: Dignity costs and emotional residue forms never code well.

Ask without theater: Offer the dimensions; let them choose and expand.

Closed-loop move: Recovery proportional to cost — not a coupon reflex.

4. “What Workaround Did You Invent to Get Unstuck?”

The question: Archaeology of the shadow path.

Why the form fails: “How easy was it?” hides the spreadsheet, the second account, the friend who knows someone.

Dialogue surfaces: Competing hires and design debt.

Ask without theater: “What did you do that we didn’t design for?”

Closed-loop move: Kill or adopt the workaround on purpose.

5. “Who Else Did You Have to Tell This Story To?”

The question: Map the retelling tax and orphan seams.

Why the form fails: Channel scores miss bot → agent → specialist handoffs.

Dialogue surfaces: Seams with no owner.

Ask without theater: Count the tells. Thank them for the labor.

Closed-loop move: Context that travels. Seam owner named. For the beats forms miss entirely, see 8 Moments That Matter More Than Your NPS Dashboard.

6. “What Would ‘Made Right’ Look Like for You — Today?”

The question: Co-design recovery with specificity.

Why the form fails: Detractor callbacks close cases; they rarely ask for a concrete make-right.

Dialogue surfaces: The fix they will actually trust.

Ask without theater: “If we could only do one thing before end of day…”

Closed-loop move: Power to deliver that make-right — or an honest constraint.

7. “What Almost Made You Leave, Switch, or Stop Trying?”

The question: Surface the quiet-exit cliff while they’re still talking.

Why the form fails: Non-respondents and silent churn never enter the harvest.

Dialogue surfaces: Leading indicators of abandonment.

Ask without theater: Normalize the near-exit. Don’t punish honesty.

Closed-loop move: Watch unfinished jobs and repeat contact — not only scores.

8. “What Should We Stop Doing Because of What Happened?”

The question: Invite a stop, not only a fix.

Why the form fails: Forms hunt promoters; they rarely fund subtraction.

Dialogue surfaces: Policy cliffs, dark patterns, busywork the org still loves.

Ask without theater: “If you ran this place for a day, what would you kill?”

Closed-loop move: A visible stop with a date — reciprocity they can see. If your program still manages the number instead of the journey, use 11 Signs Your CX Program Is Scorekeeping, Not Sense-Making.

9. “Which Handoff or Policy Moment Broke Trust?”

The question: Separate usability friction from trust violation.

Why the form fails: One score collapses betrayal and a slow page load.

Dialogue surfaces: Fine-print cliffs, denied recovery, opaque decisions.

Ask without theater: “Was it hard — or did it feel unfair?”

Closed-loop move: Trust redesign (control, care, accountability), not only UX polish.

10. “What Did You Need to Know That Nobody Told You?”

The question: Status, next step, and expectation gaps.

Why the form fails: Timing mismatches; surveys ask satisfaction after silence already hurt.

Dialogue surfaces: Opacity as the product.

Ask without theater: “What update would have lowered your stress?”

Closed-loop move: Status-as-experience design. Proactive messaging with truth.

11. “Who Helped — and Were They Allowed to Finish the Job?”

The question: Honor frontline power — or its absence.

Why the form fails: Agent scores punish care; customers rarely get asked about mandate.

Dialogue surfaces: Powerless moments of truth.

Ask without theater: Name the human if they want; protect them from blame theater.

Closed-loop move: Recovery bands and dual scorecards — not handle-time theater. For the rulebook, see 10 Agent Empowerment Rules Your Customer Deserves Before They Quit.

12. “What Should We Tell You Next Time Something Breaks?”

The question: Co-design the future promise and alerting.

Why the form fails: “Any other comments?” is a junk drawer.

Dialogue surfaces: Preferred channel, timing, and honesty level for bad news.

Ask without theater: Close by giving them authorship of the next loop.

Closed-loop move: Preference captured. Next incident proves you heard them.

How Do You Run a Conversational Listening Check Before the Next VoC Redesign?

Before the next VoC redesign, run five go/no-go questions:

  1. Are we asking in the heat or after the harvest?
  2. Do our questions invite jobs and costs — or only scores?
  3. Who can act on what we hear this week?
  4. What will customers see that we stopped or fixed?
  5. How do we measure “felt heard,” not only response rate?

Dead forms extract. Living questions listen — and then change something.

Frequently Asked Questions

What is conversational VoC?

Conversational VoC is listening as dialogue — adaptive prompts, messaging, voice, or short interviews in or near the moment of experience — aimed at understanding and closed-loop action, not only capturing a score on a static form.

What questions should I ask instead of surveys?

Ask what they were trying to get done, where it first went sideways, what it cost them, what workaround they invented, who else had to hear the story, what “made right” looks like today, what almost made them leave, what you should stop, which handoff broke trust, what nobody told them, whether helpers were allowed to finish, and what to tell them next time something breaks.

Why are survey response rates falling?

Survey response rates are falling because forms feel extractive, arrive after the heat has cooled, mismatch how people already converse, and rarely show customers that anything changed. People still have stories — they stop volunteering unpaid labor to dead forms.

How do you run conversational VoC?

Run conversational VoC in-channel and near the moment: ask job- and cost-centered questions, follow curiosity without theater, route themes to journey owners who can act, close the loop with visible fixes or stops, and measure whether people felt heard — not only response rate.

What is the difference between VoC surveys and conversational feedback?

VoC surveys optimize for structured scores and dashboard hygiene. Conversational feedback optimizes for dialogue, context, and action — surfacing jobs, seams, dignity costs, and make-right while the experience is still hot. Scores can remain a pulse; they should not be the whole conversation.

Image credits: Pexels

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
10 Agent Empowerment Rules That Prevent “I Know What the Customer Deserves” Quits

10 Agent Empowerment Rules That Prevent 'I Know What the Customer Deserves' Quits

by Braden Kelley and Chateau G Pato


What Agent Empowerment Rules Prevent “I Know What the Customer Deserves” Quits? (Short Answer)

Ten agent empowerment rules that prevent “I know what the customer deserves” quits: (1) name the moment-of-truth mandate, (2) fund recovery power, not only apology scripts, (3) kill handle-time as the only score, (4) give exception authority with a clear band, (5) design escalation as help, not punishment, (6) retire scripts that forbid honesty, (7) close the loop from agent insight to policy, (8) protect time for judgment, not denser throughput, (9) measure first-contact human success, not containment, and (10) dual-recognize insight and care. Agents quit when moral clarity meets operational helplessness.

Customers feel the gap when agents are not allowed to close it. Agents feel the gap until they leave.

Why Don’t Exit Surveys Catch These Quits?

I have sat with contact-center leaders who could recite their NPS to one decimal place and still could not explain why their best agents left. The exit form said “opportunity.” The hallway said something else: I know what the customer deserves — and I’m not allowed to deliver it.

That is not a soft skills gap. It is a design failure. Soft landings for customers require frontline power — decision rights, recovery budgets, honest language, and metrics that reward finishing the human job. These ten rules are for human service agents in the moment of truth — not AI agents acting on a customer’s behalf. Empathy posters do not replace a mandate.

Rule Quit-risk prevented Costume version
1. Moment-of-truth mandate “Let me check with my supervisor” as the only move Empowerment in the town hall; none in the playbook
2. Fund recovery power Apology without a fix Empathy training without a wallet
3. Kill handle-time as only score Punishing agents who finish the job Green AHT, red customer
4. Exception authority with a band Approval theater for small make-goods Manager PIN for a $40 credit
5. Escalation as help Escalation scored as failure “Should have contained”
6. Retire scripts that forbid honesty Forced gaslighting Brand voice that bans candor
7. Insight → policy loop Same break reported weekly Feedback dump; no redesign
8. Protect judgment time Faster humans, thinner care AI “frees” agents into denser AHT
9. First-contact human success Ending contact while problem stays Deflection as CX strategy
10. Dual-recognize insight and care Best diagnosticians leave Agent of the month for shortest handle

1. Why Must You Name the Moment-of-Truth Mandate?

The rule: Write what the agent is empowered to decide, ship, or stop in the live interaction — before the next coaching cascade.

Quit-risk prevented: Ambiguity that forces “let me check with my supervisor” as the brand’s only move.

Costume: “Empowered agents” in the town hall; no decision rights in the playbook.

Run it: One-page mandate per journey. Supervisors review exceptions against the band — not against fear. If the mandate is not written, it is not empowerment. It is a slogan.

2. How Do You Fund Recovery Power — Not Only Apology Scripts?

The rule: Budget refunds, rebooks, credits, expedites, and make-goods as design — not as “leakage.”

Quit-risk prevented: Agents who can only apologize while the customer’s problem stays unbroken.

Costume: Empathy training without a wallet.

Run it: Recovery budget owned at team level. Track recovery that saves the relationship — not only the cost of recovery. Care without power is theater. For why belief in CX rarely funds frontline power, see 9 Reasons Companies Underinvest in CX.

3. Why Kill Handle-Time as the Only Score?

The rule: Demote average handle time from steering wheel to constraint light. Pair it with completion, effort, and recontact.

Quit-risk prevented: Punishing the agent who stayed long enough to finish the job.

Costume: Green AHT, red customer, burnt-out agent.

Run it: Dual scorecard. A green handle time cannot close a red human-success review. For the maturity path from SLAs to human-success measures, see 5 Stages from SLAs to XLAs.

4. What Does Exception Authority With a Clear Band Look Like?

The rule: Define the exception band agents may use without permission theater — and expand it with demonstrated judgment.

Quit-risk prevented: Twelve-step approvals for a $40 make-good while the customer burns.

Costume: “Empowerment” that still requires three systems and a manager PIN.

Run it: Band by journey risk. Publish examples of good exceptions. Coach the edge cases — don’t criminalize care.

5. How Do You Design Escalation as Help, Not Punishment?

The rule: Escalation paths that preserve context, dignity, and speed — for customer and agent.

Quit-risk prevented: Agents who escalate and get scored as failure; customers who repeat their story four times.

Costume: Escalation as a trap door; QA that marks “should have contained.”

Run it: Context-preserving handoff. Score escalation quality on outcome, not volume avoided. Containment is a tactic. It is not a north star.

6. Why Retire Scripts That Forbid Honesty?

The rule: Allow truthful language when policy hurts — what you can and cannot do, why, and the next real step.

Quit-risk prevented: Agents forced to gaslight (“your call is important”) while knowing the truth.

Costume: Brand voice guides that ban candor.

Run it: Honest playbooks for known failure modes. Legal and compliance co-own clarity — not spin. Forced dishonesty is a retention tax.

7. How Do You Close the Loop From Agent Insight to Policy?

The rule: Frontline patterns climb from person → pattern → policy with a named owner and date.

Quit-risk prevented: Agents who report the same break weekly and watch nothing change.

Costume: VoC dashboards; agent feedback in a dump; no redesign.

Run it: Weekly “three friction themes” from agents into journey owners. Publish what changed. Listening without action is scorekeeping. For the program diagnostic, see 11 Signs Your CX Program Is Scorekeeping, Not Sense-Making.

8. How Do You Protect Time for Judgment — Not Denser Throughput?

The rule: When AI or automation absorbs glue work, defend reclaimed minutes for care and judgment — don’t refill them as denser AHT targets.

Quit-risk prevented: Faster humans, thinner humanity; agents as the leftover of automation.

Costume: “AI frees agents for higher-value work” with no calendar or metric change.

Run it: Explicit capacity policy after automation. Judgment metrics, not only occupancy. For signals that frontline power is shrinking while AI slides expand, see 8 Signals You’re Preparing for the Wrong Future of Work.

9. Why Measure First-Contact Human Success, Not Containment?

The rule: Success = the customer completed the job with confidence. Containment is a tactic, not a north star.

Quit-risk prevented: Agents rewarded for ending the contact while the problem stays.

Costume: Deflection dashboards as CX strategy.

Run it: First-contact resolution, time-to-confidence, and recontact for the same intent — owned metrics with journey owners. If ending the call is winning, finishing the job is optional.

10. What Does Dual Recognition of Insight and Care Require?

The rule: Promote and praise agents who fix moments and surface system truth — not only those who hit script and AHT.

Quit-risk prevented: The best diagnosticians leave; the most compliant remain.

Costume: Agent of the month for shortest handle time.

Run it: Dual recognition — care outcomes plus insight that changed policy. Make both career-safe. If only compliance is celebrated, only compliance stays.

How Do You Audit Agent Empowerment Before the Next CX Review?

Before the next CX or workforce review, run five go/no-go questions. If you cannot answer them, you are funding surveys while starving power:

  1. What can an agent decide without a supervisor in the top three failure journeys?
  2. Is recovery funded — or only apologized for?
  3. Which metric still punishes finishing the job?
  4. What agent insight changed policy last month?
  5. Would a skilled agent say they are allowed to deliver what customers deserve?

If your best agents know what customers deserve and cannot deliver it, you are not running a CX program. You are running a moral injury machine with a survey on top.

Frequently Asked Questions

What is agent empowerment in CX?

Agent empowerment in CX means human service agents have written decision rights, recovery budgets, honest language, exception bands, and metrics that reward finishing the customer’s job — not only ending the contact. Empathy training without power is not empowerment.

Why do customer service agents quit?

Many skilled agents quit when they know what the customer deserves but cannot deliver it — blocked by handle-time theater, script walls, approval ladders, containment KPIs, and insight loops that never change policy. Moral clarity meeting operational helplessness is a retention failure, not a “mindset” problem.

How do you empower contact center agents?

Name moment-of-truth mandates, fund recovery, demote handle time as the only score, give clear exception bands, design escalation as help, allow honest scripts, close agent insight into policy, protect judgment time after automation, measure first-contact human success, and dual-recognize care and system insight.

What metrics replace handle time?

Pair handle time as a constraint with first-contact resolution, time-to-confidence, effort, and recontact for the same intent. A green handle time should not close a review when human success is red. Containment and deflection are tactics — not the definition of CX success.

How do you prevent frontline burnout in CX?

Prevent burnout by aligning authority with care: recovery power, exception bands, metrics that reward finishing the job, protected judgment time when AI absorbs glue work, and career recognition for insight that changes policy. Burnout often follows moral injury — knowing the right thing and being blocked from doing it.

Image credits: Unsplash

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
11 Signs Your CX Program is Scorekeeping, Not Sense-Making

11 Signs Your CX Program is Scorekeeping, Not Sense-Making

by Braden Kelley and Chateau G Pato


How Do You Know Your CX Program Is Scorekeeping, Not Sense-Making? (Short Answer)

Your CX program is scorekeeping, not sense-making, when governance energy goes to NPS, CSAT, CES, and dashboard hygiene while nobody can explain — in a customer’s words — why the number moved or what journey you actually changed. Eleven signs: the CX review is a score review; people are paid for the number; driver models replace talking to humans; surveys serve the calendar not the moment; closed loop is a ticket not a redesign; competitive NPS theater; channel scores with orphaned seams; capture volume as the KPI; comments in a dump; sentiment AI as costume; and a green score with a red Tuesday you are not allowed to name.

A score asks whether they would recommend you. Sense-making asks what happened to them — and what you will stop doing because of it.

The Number Is Not Understanding

I have sat in CX reviews that felt like a weather report. Promoters up. Detractors down. Traffic lights polite. Someone asked what we learned about humans. The room reached for a driver model the way a drowning person reaches for a brochure.

That is scorekeeping: treating the number as the product of the program. Sense-making demotes the score to a signal. It funds contact with real Tuesdays. It judges CX by journeys changed — not points harvested.

Sign Scorekeeping Sense-making
1. Score review as CX review Traffic lights vs last quarter One journey, one story, one decision
2. Paid for the number Beg for tens; hide detractors Incentives on outcomes and loops
3. Models replace humans Word cloud as root cause Contact evidence required
4. Calendar surveys Tool default / ticket+24h Listen at the hot moment
5. Loop = case closed SLA on the detractor call Person recovered; system owned
6. NPS theater Beat the category chart Your Tuesday, your economics
7. Channel scores Leaderboards by org chart Seam owners and journey scores
8. Capture as KPI We listened to N people What got redesigned or stopped
9. Comments in a dump Verbatim “available” One decision, owner, date
10. Sentiment costume The tag is the insight AI sorts; humans make meaning
11. Green score, red Tuesday Official story is the dashboard Dual truth; red journey can stop the review

1. Why Is a CX Review That Is Only a Score Review a Warning Sign?

The sign: The monthly CX meeting is a walk through NPS, CSAT, CES, traffic lights, and “up or down versus last quarter.” Stories, seams, and decisions are leftover time — if they get time at all.

Why it seduces: Numbers look like management. A chart is faster than a human.

Sense-making instead: Lead with one journey, one human story, one decision. The score is a footnote, not the agenda. If the meeting could run without a customer’s words, it was scorekeeping with catering.

3. Why Can’t Driver Models and Word Clouds Replace Talking to Humans?

The sign: “Root cause” is a regression, a theme cluster, or a word cloud. Nobody has to sit with a customer or a frontline person this month to keep the program green.

Why it seduces: Analytics look like insight. You can screenshot a driver model. You cannot screenshot someone’s third explanation of the same billing break.

Sense-making instead: Every priority theme requires contact evidence — quotes, recordings, ride-alongs — that could not have been invented from the dashboard. If it could have been written without leaving the building, it is not sense. It is interior decorating with data.

4. Why Is Surveying on the Program’s Calendar Instead of the Customer’s Moment a Problem?

The sign: Cadence is quarterly, or twenty-four hours after a ticket close, or whenever the tool’s default fires — not at the emotional peak or the stalled wait.

Why it seduces: A program needs a calendar. Tools need a trigger. Neither is a moment of truth.

Sense-making instead: Listening designed for the moment — conversational, in-channel, after the cliff. Scores are a pulse, not a ritual. If you always ask when it is convenient for you, you will always hear a polite version of Tuesday.

5. How Is a Closed Loop That Only Closes Cases Still Scorekeeping?

The sign: Detractor follow-up is a SLA: call them, code them, close them. The same break happens next week. The loop never climbs from person to pattern to policy.

Why it seduces: “We close the loop” photographs well. Cured systems do not fit in a weekly metric as neatly.

Sense-making instead: Person-level recovery and a named system owner when the same friction repeats. Closed is not cured. A recovered human and an unchanged process is hospitality theater.

6. What Is Competitive NPS Theater in a CX Program?

The sign: The north star is beating a category benchmark or a rival’s published score. Your own journeys, effort, and failure demand are secondary.

Why it seduces: Boards like relative rankings. A league table feels like strategy.

Sense-making instead: Your economics and your Tuesday — retained humans, repeat contacts, dignity costs — beat a borrowed chart. If you cannot name the friction you removed in this book of business, you are competing at poster height.

7. Why Do Channel Scores With Orphaned Seams Mean You Are Scorekeeping?

The sign: Phone, chat, web, and store each have a score. The handoff between them has no owner and no metric. Customers live in the seam; the program lives in the channel.

Why it seduces: Channel dashboards map cleanly to org charts. Seams do not.

Sense-making instead: Journey and seam scores with owners — not only channel leaderboards. If the customer fell between teams and every channel still looks “green,” you measured the boxes, not the human path.

8. Why Is Capture Volume a Weak CX KPI?

The sign: Success is response rate, comments captured, tickets tagged, “we listened to N customers.” Action rate and journey change are unmeasured or someone else’s job.

Why it seduces: Listening is visible. Changing the work is political.

Sense-making instead: Judge the program by what got redesigned or stopped — not by how much you collected. Volume without action is a warehouse of other people’s pain.

9. What Does It Mean When CX Comments Live in a Dump?

The sign: Verbatim sit in a portal. Nobody has to translate them into a decision in human language. Qualitative is “available” and unused.

Why it seduces: You can say you “have the voice of the customer.” Storage is cheaper than courage.

Sense-making instead: A standing ritual: this month’s comments must produce one decision, one owner, one date — or they were storage, not listening. Available is not the same as heard.

10. When Is Sentiment AI Just a Sense-Making Costume?

The sign: Models tag emotion and topics at scale. The readout is the insight. No one checks whether the tag matches the job the human was trying to do.

Why it seduces: AI looks like understanding at volume. Speed flatters the wrong conclusion.

Sense-making instead: AI as a sorter, humans as meaning-makers. If a frontline person would not recognize the “theme,” it is not sense. It is labeling. Use machines to find the pile. Use people to say what the pile is.

11. Why Is a Green CX Score With a Hard Tuesday Still Failure?

The sign: NPS or CSAT hold or rise while effort, workarounds, and “I know what they deserve” attrition stay ugly. Naming the gap is treated as disloyalty to the program.

Why it seduces: The dashboard is the official story. Official stories like to stay employed.

Sense-making instead: Dual truth — score and lived experience. A green number cannot close the review if the journey is still red. If you cannot say that out loud, you are not running CX. You are running a reputation program for a metric.

How Do You Test Scorekeeping Versus Sense-Making in a CX Review?

Before the next VoC or CX steering meeting, run five questions. If you cannot answer them, you are managing a score, not making sense of humans:

  1. What human story led this meeting — in their words, not in a theme label?
  2. What did we change in a journey — not in a survey or a dashboard tile?
  3. Who is paid for the number versus the outcome?
  4. Where does the seam live that no channel score owns?
  5. Can a frontline person recognize our “why” — or would they laugh?

If scores have become the strategy because nothing else gets funded, that is a budget problem as much as a program problem — see 9 Reasons Companies Underinvest in CX. If the listening layer is still a dead form, Conversational and Agentic VoC is the method shift. If the number never had to name a behavior, 7 Ways to Calculate CX ROI Without Hope-Based Slideware is how you price the work. And if the map is still late to the pain, start with 12 Friction Points Customers Feel Before Your Journey Map Does.

Scorekeeping asks how we did. Sense-making asks what happened to them — and what we will stop pretending is fine.

Frequently Asked Questions

What is the difference between CX scorekeeping and sense-making?

Scorekeeping treats NPS, CSAT, or CES as the product of the CX program — optimizing surveys, samples, and dashboards. Sense-making uses those scores as signals, requires contact with real journeys, and judges success by what you changed for humans, not by points gained.

How do you know if your CX program is just managing NPS?

Warning signs include CX meetings that are only score reviews, incentives tied to survey points, root cause that never leaves a driver model, closed loops that close cases but not systems, channel scores with no seam owner, and a green NPS while Tuesday is still hard.

Why is NPS not enough for customer experience?

NPS is a signal, not a strategy. It does not name the job the customer was trying to do, the seam that failed, or the behavior you must change. Without that translation — and without owners, recovery power, and journey redesign — a rising score can coexist with rising effort and workarounds.

What should a CX review meeting cover?

Lead with one journey, one customer or frontline story in their language, and one decision — what to fix, stop, fund, or own. Scores, themes, and AI tags can inform. They should not consume the agenda. End with an owner and a date, not only a traffic light.

How do you stop survey gaming in CX programs?

Stop paying people for the score. Tie incentives to journey outcomes and closed-loop system changes. Sample in ways that cannot hide detractors. Treat begging for tens as a control failure. If the number is the bonus, the number will be the work.

Image credits: Unsplash

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
9 Reasons Companies Underinvest in CX

(Even When They “Believe” in It)

9 Reasons Companies Underinvest in CX

by Braden Kelley and Chateau G Pato


Why Do Companies Underinvest in CX If They Believe in It? (Short Answer)

Companies underinvest in customer experience even when they “believe” in it because belief is not a budget line. CX often arrives at the funding table with scores and journey maps; competing asks arrive with dollars. Leaders nod at loyalty, then fund what they can defend on a spreadsheet.

Nine common reasons: (1) nobody can price it, (2) scores are treated as the strategy, (3) CX is a department not an operating system, (4) the front line is accountable without authority, (5) cost cuts win because loyalty lags, (6) green SLAs hide red experiences, (7) no one owns the journey after the workshop, (8) listening is cheap and acting gets cut, and (9) the truth would require tradeoffs nobody wants.

Belief Is Not a Budget Line

I have sat in enough leadership rooms to recognize the pattern by the coffee cups. Someone says customer experience is a priority. Heads nod. A journey map appears that could win a design award. Then finance asks the only question that counts in that room: What is this worth?

The conversation that felt strategic starts to sound like a philosophy elective. Marketing shows pipeline. Product shows release velocity. Sales shows bookings. CX shows a score — and hopes the room will emotionally translate “up and to the right” into money.

Hope is not a business case. Companies rarely underinvest because they hate customers. They underinvest because experience is treated as a belief, a metric, or a department — not as a priced operating system with owners, incentives, and frontline power.

Reason What “belief” looks like What to do instead
1. Unpriced impact NPS slides, no dollars Metric → behavior → money → intervention
2. Score as strategy Managing the number Fund the why and the loop
3. Department sidecar CX team, no levers Journey owners with rights
4. Accountable, powerless Front line absorbs anger Fund enablement at the moment of truth
5. Loyalty lags Cuts win this quarter Show the lag; protect key journeys
6. SLA-green theater Uptime hides struggle Human success on the scorecard
7. Maps without owners Workshop, then drift Name the Tuesday operator
8. Listen, don’t act VoC tools survive; recovery doesn’t Budget hear → act → confirm
9. Tradeoff avoidance Symbolic CX everywhere Fund fewer journeys fully

1. Nobody Can Price It

What it is: Underinvestment because CX impact never gets translated into finance-ready estimates of retained revenue, avoided acquisition cost, or lower cost-to-serve.

The pattern: Customer experience speaks NPS, CSAT, and CES. The budget speaks dollars. The proposal that speaks fluent finance gets funded. The proposal that speaks fluent satisfaction waits another year.

What to do instead: Use a simple value chain — experience metric → customer behavior → financial outcome → named intervention. Start with your churn, revenue per customer, and cost per contact. Model a conservative-to-optimistic range. Say what is estimated. Transparency survives a CFO. False precision does not.

2. Scores Are Treated as the Strategy

What it is: Managing the survey number as if it were the customer relationship.

The pattern: Teams chase points on a dashboard while the journeys that produce loyalty stay underfunded. Scorekeeping without sense-making. When response rates collapse, the “strategy” gets thinner and the belief gets louder.

What to do instead: Demote scores to signals. Fund the why — conversational listening, journey repair, closed loops — not another instrument that asks people to perform unpaid labor for a brand that will not change.

3. CX Is a Department, Not an Operating System

What it is: Belief lives on the org chart. Investment does not follow the work.

The pattern: A CX team owns maps, research, and the annual summit. It does not own policy, product sequencing, staffing, or incentives. So “we believe in experience” becomes a sidecar to the real operating model.

What to do instead: Give journey owners decision rights. Treat customer experience as how the enterprise runs — handoffs, recovery, promises — not as a department that comments after the fact.

4. The Front Line Is Accountable Without Authority

What it is: Employees are held responsible for customer outcomes they lack the staffing, tools, or permission to deliver.

The pattern: Your best people feel the underinvestment before the dashboard does. Gallup has found staffing is often the top barrier employees name to delivering exceptional service. Qualtrics has found understaffed frontline teams far more likely to think about quitting. The quiet line I keep hearing: I know what the customer deserves. I am not allowed to deliver it.

What to do instead: Fund enablement where the moment of truth lives — judgment, recovery budget, time, and a path to fix the system, not just absorb the anger. Underinvestment in CX is also an employee-experience strategy, whether you meant it or not.

5. Cost Cuts Win Because Loyalty Lags

What it is: Savings show up this quarter. Churn, effort, and brand damage show up later — so the impatient P&L always has the better story.

The pattern: Headcount, knowledge, and recovery get trimmed because the harm is delayed. By the time loyalty moves, the cut already looks like “discipline.”

What to do instead: Make the lag visible. Protect a few high-leverage journeys from efficiency that is actually extraction. Pair any cost takeout with the human behaviors you are betting will not change — and watch those behaviors like a hawk.

6. Green SLAs Hide Red Experiences

What it is: Managing by cold service metrics while humans still fail the job.

The pattern: Uptime, response time, and handle time look healthy. Customers repeat their story. Employees run workarounds. The dashboard is green; the relationship is not. Belief in “service excellence” funds the SLA stack and starves experience-level measures.

What to do instead: Put human success on the same review as reliability. A green SLA should not close the meeting if effort is high, trust is low, or people cannot finish in one attempt. SLAs keep the lights on. They should not get to pretend they are the whole truth.

7. No One Owns the Journey After the Workshop

What it is: Maps and research get funded. The operating owner of a broken handoff does not.

The pattern: Belief photographs well in a workshop. Then Monday returns the work to silos. Nobody is empowered to change the seam between “marketing promised” and “operations delivered.”

What to do instead: Name a durable journey owner before the next offsite — someone who can change the path, not only present it. If the map has no Tuesday operator, you funded theater.

8. Listening Is Cheap; Acting Is What Gets Cut

What it is: Voice-of-customer tools, surveys, and dashboards survive budget cycles. Recovery staffing, redesign, and closed loops do not.

The pattern: Organizations get very good at collecting opinions and very timid about spending to change the thing people complained about. Customers notice. So do employees who asked for input and watched nothing move.

What to do instead: Budget the loop — hear, understand, act, confirm — as one investment, not a listening layer plus a vague “we’ll take it back to the business.” Reciprocity is what makes the next conversation possible.

9. The Truth Would Require Tradeoffs Nobody Wants

What it is: Real CX investment would expose turf, pet channels, understaffing, and brand promises operations cannot keep — so “belief” stays safer than choice.

The pattern: Symbolic experience everywhere; funded experience nowhere that hurts. Another journey map. Another principle. No decision about what you will stop doing so a few moments can actually work.

What to do instead: Surface winners and losers. Fund fewer journeys fully rather than every journey symbolically. Belief that refuses tradeoffs is not strategy. It is branding for the annual report.

How Do You Get Customer Experience Funded?

Turn belief into an investable ask. Do not take the next CX proposal to finance until you can answer these:

  1. What is this worth in our numbers — retained revenue, cost-to-serve, regrettable attrition — not an industry slogan?
  2. Which customer or employee behavior must change for the investment to count as success?
  3. Who owns this journey on a normal Tuesday after the workshop ends?
  4. What old path or SLA-only definition of winning will we stop treating as success?
  5. What frontline power — staffing, tools, recovery authority — are we actually funding?

Belief gets you the slide. A priced human outcome gets you the line item. If you want companies to stop underinvesting in customer experience, stop asking leaders to have more faith — and start giving them a case the budget can recognize without translating it into a foreign language.

Frequently Asked Questions

Why do companies underinvest in CX even when they believe in it?

Because belief is not a budget line. Customer experience often arrives with scores and maps while competing investments arrive with dollars. Underinvestment follows when impact is unpriced, scores substitute for strategy, CX lacks operating power, the front line has accountability without authority, cost cuts beat lagging loyalty, SLAs hide poor experience, journeys lack owners, listening is funded without action, and real tradeoffs are avoided.

Why isn’t believing in customer experience enough?

Belief produces slides, principles, and workshops. Funding requires a priced outcome, a named owner, incentives that match the new behavior, and frontline power to deliver the promise. Without those, “we believe in CX” is branding, not investment.

How do you get CX funded in a budget meeting?

Translate an experience metric into a customer behavior and a dollar outcome tied to a specific intervention. Use internal numbers where possible, show a range, name the journey owner, and include the frontline enablement required to make the change real.

What are the main reasons companies underinvest in customer experience?

Nine common reasons are unpriced impact, treating scores as strategy, CX as a powerless department, frontline accountability without authority, short-term cost cuts beating lagging loyalty, green SLAs hiding red experiences, maps without journey owners, listening without funded action, and unwillingness to make tradeoffs.

How does underinvesting in CX affect employees?

When experience is underfunded, frontline people are often still held accountable for customer outcomes they cannot deliver. That gap drives frustration, burnout, and regrettable attrition — so the company pays twice: weaker customer loyalty and higher cost to replace the humans who knew how to save the moment.

Image credits: Google Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.