Author Archives: Braden Kelley

About Braden Kelley

Braden Kelley is a Human-Centered Experience, Innovation and Transformation practice lead at HCL Technologies, a popular innovation speaker, and creator of the FutureHacking™ and Human-Centered Change™ methodologies. He is the author of Stoking Your Innovation Bonfire from John Wiley & Sons and Charting Change (Second Edition) from Palgrave Macmillan. Braden is a US Navy veteran and earned his MBA from top-rated London Business School. Follow him on Linkedin, Twitter, Facebook, or Instagram.

How to Build a Local Value Score Without Starting a Partisan Firefight

How to Build a Local Value Score Without Starting a Partisan Firefight

by Braden Kelley and Art Inteligencia

In the first piece in this series, we lit the spark: absolute spending debates rarely move the needle, while peer-relative value, what similar communities achieve per dollar, can. This article opens the instrument. Not the full DIY toolkit yet. The method. The experience architecture. The discipline that turns civic anger into civic learning.

From spark to instrument

Innovation without an instrument is just a mood. Human-centered change without a shared unit of sense-making becomes another round of tribal theater. If you felt the first article land – What If You Could Prove the Government is Ripping Us Off? – the next question is practical:

How do we score a place fairly enough that good-faith people on the left, right, and exhausted middle can argue about the same dashboard?

That is an experience-design problem before it is a political problem. People cannot improve what they cannot sense. So we need an interface for civic value that ordinary neighbors can understand in under two minutes, and that a finance director can challenge without inventing motives.

Call the instrument a Relative Value Score (RVS): a transparent, peer-normalized view of outcomes per cost-adjusted dollar, with a clear path to “why the gap.” The revolutionary move is not inventing a grade that flatters your side. It is building a comparison citizens trust enough to use in budget season.

What a Relative Value Score actually measures

A Relative Value Score is not “how big is the budget?” Bigger places spend more. Harder case mixes cost more. Expensive labor markets pay more. Treating raw spend as proof of compassion, or of waste, is how we keep fighting about identity instead of delivery.

Conceptually:

RVS ≈ how close you are to the best peer in your cohort on value delivered per dollar—across a small set of outcome domains, cost-adjusted, with published weights and sources.

Think of it like comparing restaurants of the same type and price band on food quality per dollar, not comparing a food truck to a banquet hall and declaring a winner by total receipts. Futurology loves flashy national indexes. Experience design prefers local instruments that feel fair in the neighborhood where life is actually lived.

Three design rules keep the score human-centered:

  • Outcomes over optics. Prefer measurable delivery (response times, learning growth, pavement condition, permit latency, unit cost of capital) over press-release volume.
  • Cost-adjusted dollars. Adjust for regional price and wage differences so “expensive place” is not automatically “bad place.”
  • Relative, not absolute holiness. Normalize within the peer cohort. The best peer becomes the teacher. Everyone else gets a gap to close—or explain.

Improper payments, fraud risk, and opaque grantee chains still matter. They belong on a related but separate track (more below). Mixing “inefficient” with “corrupt” in one opaque number is how movements lose the room on the first contested claim.

Peers first: the fairness engine

Most “benchmarking” fails before the math starts—because the peer set is a vibes playlist. Comparing a dense coastal city to a rural county, or a high-poverty district to an affluent one using unadjusted test levels, is not accountability. It is ammunition.

Peer cohorts are the fairness engine. Build them first. Argue about them in public. Version them. That is change leadership: put the contested assumptions where people can see them.

Practical cohort dimensions by layer:

  • Cities: population band, density, metro/rural context, regional price/wage index.
  • Counties: population, urban share, mandate set (courts, jails, public health, roads, elections).
  • States: population scale, economic mix, federal transfer share—used carefully; states are multi-product machines.
  • School districts: enrollment, % students in special education / English learners / free-or-reduced lunch (or equivalent need measures), urbanicity, regional educator wages. Prefer learning growth / value-add over raw proficiency levels whenever possible.
  • Water and special districts: service population, infrastructure age/type, treatment complexity, geography—unit cost of delivered service beats “total budget” every time.

A good peer set is small enough to be intelligible and large enough that one outlier cannot redefine “normal.” Publish who is in the cohort and why. Invite the entity to propose alternate peers with evidence. Right-to-reply is not weakness. It is how trust compounds.

Domains, weights, and the “why the gap” story

Do not boil the ocean. Innovation teams ship thin slices. For a first local scorecard, pick 8–12 metrics max across a few domains—not 200 indicators nobody reads.

Example domain shapes (customize by entity type):

  • Service delivery: outcomes or service quality per dollar or per FTE (clearance, response, throughput, condition).
  • Administrative load: central office / admin share versus program or instructional spend.
  • Labor intensity: compensation density (payroll, overtime, benefits where available) versus outputs.
  • Contracting & capital: competitive bid share, concentration, unit cost and schedule slippage on comparable projects.
  • Transparency: timely CAFRs/budgets, machine-readable checkbooks, FOIA latency—inputs to trust, not vanity.

Weights should be public, few, and revisable. Publish a default weighting, and let citizens toggle sensitivity modes (“weight learning growth higher,” “weight admin share higher”) so critics can fork the story without assassinating the messenger. That is open innovation applied to civic sense-making.

The score is the headline. The product is the “why the gap” decomposition: which 2–3 drivers explain most of the distance from the best peer, each with sources and confidence. Without that story, a score is just a ranking for dunking. With it, a score becomes a change agenda.

Two tracks: performance vs. integrity

Human-centered accountability refuses false equivalence. A district can be expensive relative to peers and still honest. An agency can look “lean” on paper and still run integrity red flags. Smash those into one “corruption score” and you have built a weapon, not an instrument.

Keep two panels on the same dashboard:

  • Performance track (RVS): peer-relative outcomes per cost-adjusted dollar. This is the main civic interface.
  • Integrity overlay: audit findings, delayed reporting, sole-source patterns, related-party flags, outcome-light grantee chains—shown with higher evidentiary bars, source documents, and room to reply. Treat AI here as a highlighter for human review, never as a judge pronouncing guilt.

This separation is how a multipartisan movement survives contact with reality. Precision is the revolutionary ethic. Smear is the cheap substitute.

A weekend walkthrough for one jurisdiction

You do not need the full toolkit to practice the method. You need a first mile. Here is a human-sized walkthrough you can start this weekend—before the downloadable suite and guidebooks ship.

  • 1. Name the entity in one sentence. “Our K–12 district,” “our city general fund,” “our water district”—passion plus a border beats rage at “the system.”
  • 2. Pull Tier-A documents. Latest adopted budget, CAFR or annual financial report, salary schedule or checkbook export, and any published outcomes dashboards. Note what is missing.
  • 3. Draft a peer shortlist. Five to fifteen similars using the cohort dimensions above. Write one paragraph defending the set.
  • 4. Choose eight metrics you can source. Prefer unit costs and outcomes over vibes. If a metric cannot be sourced, park it—do not invent it.
  • 5. Build a crude gap view. For each metric, who is best in your peer set? Where are you? What is the story in two drivers?
  • 6. Separate integrity notes. If you see red flags, log them with links and confidence—not as the score itself.
  • 7. Write three budget-season questions. Short enough for a three-minute public comment. Specific enough that staff must answer on the record.

That walkthrough is reconnaissance, not a finished product. Finished products need versioned methods, entity right-to-reply, and consistent cohort rules. That is exactly what the forthcoming DIY tools and role-based guidebooks are for—so local teams are not reinventing discipline in the dark.

What comes next—and how to stay in formation

Method without movement is a PDF nobody uses. Movement without method is a mob with a megaphone. We are building both: open instruments for peer-relative value, and a network of roles—data gatherers, benchmarking intelligence creators, website hosts, promoters, meeting advocates, media partners—who can stand up local scoreboards when the kits are ready.

In the next pieces in this series, we will walk a single jurisdiction end-to-end as a chapter-lead story, then open the downloadable suite: data gathering, careful AI-assisted processing under human guardrails, and public benchmarking sites neighbors can actually use.

Between method and toolkit, stay on the bus.

If this article sharpened your sense of how fair comparison should work, subscribe to Human-Centered Change & Innovation Weekly. That list is how you get first notice when the guidebooks and DIY tools move from spark to usable firepower—practical next steps for the jurisdiction and role you choose.

Prefer the full signup page? Open the newsletter signup page.

Forward this to the person who already knows the peer set in their head—and to the person who keeps saying the comparison “isn’t fair” without ever defining fair. Fairness is designable. That is the work.

Absolute spend is a slogan. Peer-relative value is an instrument. Instruments are how human-centered futures get built.

Frequently Asked Questions

What is a Relative Value Score (RVS)?

A Relative Value Score is a peer-normalized measure of outcomes per cost-adjusted dollar for a city, county, state, school district, or special district. It shows how close an entity is to the best performer among similar peers across a small set of transparent metrics—not whether its total budget is large or small in absolute terms.

How do you choose fair peers for comparison?

Fair peers share similar constraints: size and density for cities; mandate mix for counties; enrollment and student-need mix plus regional wages for school districts; service population and infrastructure profile for water and special districts. Publish the cohort rules, keep the set large enough to be meaningful, and allow entities to propose alternate peers with evidence. Unadjusted “leaderboards” that ignore poverty or cost of living are not fair benchmarks.

Should fraud and performance be one score?

No. Keep a performance track (peer-relative value) separate from an integrity overlay (audits, delayed reporting, sole-source patterns, opaque grantee chains) that requires stronger evidence and human review. Combining them into one “corruption score” destroys credibility and unfairly smears underperforming but honest agencies.

Image Credits: Pexels

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Cursor to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week and to be alerted when the guidebooks and DIY tools to implement this discipline locally are available.

What Does a Customer Experience Audit Cost?

What Does a Customer Experience Audit Cost?

by Braden Kelley and Art Inteligencia

This is usually the last question someone asks before they’re ready to move forward, which means it deserves a direct answer rather than the consultant’s reflex of “it depends.” It does depend — but on a small, specific set of factors, and I’d rather walk you through exactly what they are than make you guess.

The honest answer: it scales with scope, not with company size

The biggest misconception I run into is that audit cost tracks with company revenue or headcount. It doesn’t, directly. It tracks with the shape of the journey being audited: how many distinct touchpoints are in scope, how many channels the experience spans (in-person, phone, web, app, in some combination), and how many stakeholder groups need to be interviewed to understand the journey from more than one angle. A single-channel, single-audience journey for a mid-size company can cost less than a sprawling omnichannel journey for a smaller one, if the omnichannel journey is genuinely more complex to walk.

The five activities that drive cost

  1. Audience research and persona validation. Every audit starts by identifying your distinct audience segments and validating their journeys against current reality — surfacing the needs, expectations, and pain points that internal assumptions have obscured. One clearly-defined audience is a much faster starting point than four segments that each need their own research and validation pass, and this is usually the first scope decision worth making deliberately.
  2. Journey mapping and touchpoint analysis. From there, we create or update persona-based journey maps — identifying key touchpoints, pain points, emotional highs and lows, and improvement opportunities across every relevant channel. A journey with four or five touchpoints in a single channel maps far faster than one spanning fifteen touchpoints across phone, web, app, and in-person combined.
  3. Existing data evaluation. Your current KPIs, NPS scores, CSAT data, and sentiment analysis get analyzed for the patterns, gaps, and untapped insights that current reporting isn’t surfacing. How much historical data you already have — and how much of it is usable versus scattered across disconnected systems — changes how much work this step takes before it produces anything actionable.
  4. Walking the journey. This is where key touchpoints get evaluated firsthand — retail locations, digital channels, service calls, sales cycles, in B2B and B2C contexts alike — and it’s typically where an audit finds its most surprising and valuable insights. It’s also usually the most time-intensive of the five activities, because it’s genuine fieldwork rather than analysis of what already exists, and cost scales directly with how many touchpoints and channels get walked in person versus reviewed through documentation alone.
  5. Competitive benchmarking. Benchmarking your experience performance against select competitors and best-in-class examples shows not just where you stand, but how far you are from where you need to be. This one is genuinely optional depending on your goals — skipping it keeps the engagement focused purely on your own gaps, while including it adds real value when you specifically need to know how you compare to the alternatives your customers are weighing.

Timeline compresses or expands the cost of all five at once: doing them in two weeks instead of six doesn’t reduce the work, it concentrates it, usually by putting more people on it in parallel. If you have flexibility on timeline, it’s often the easiest lever to pull to manage overall cost.

The number that actually matters more than the price

Cost in isolation is the wrong comparison. The comparison that matters is cost against what the friction is currently costing you in retained revenue, referral loss, and cost to serve — because that’s the number an audit is designed to protect. If you haven’t run that comparison yet, the CX ROI Calculator will give you a real figure in a few minutes, and it’s the right first step before a cost conversation, not after it. A number that’s larger than the audit’s cost is the fastest way to know the conversation is worth having at all.

Getting an actual number

Because cost depends on the scope decisions above, and those decisions are specific to your journey and your goals, the accurate way to get a real figure is a short scoping conversation rather than a published price list that would be wrong for most people who read it. If you’re at the point of wanting that conversation, the audit page has the details on how an engagement runs, and I’m glad to talk through scope and a realistic estimate directly.

Customer Experience Audit Learn More

Image Credits: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Claude to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

What If You Could Prove the Government is Ripping Us Off?

What If You Could Prove the Government is Ripping Us Off?

by Braden Kelley and Art Inteligencia

We are living through a crisis of civic experience. People can feel that they’re being ripped off by their elected and administrative officials, but yet they lack a fair way to prove it. The future will not be built by louder arguments alone. It will be built by better comparisons: value delivered per dollar, relative to peers who look like us. That is the spark for a human-centered citizen movement. First, let’s look at the scale of the problem already documented in the public record.

The bill without a receipt

Most of us do not experience government as a spreadsheet. We experience it as a journey: the permit that takes months, the school board meeting that buries tradeoffs in jargon, the water bill that climbs while the story never quite lands. That journey is the real product. And if experience design has taught us anything, it is this: when the interface of truth is broken, people do not get smarter by trying harder, they get cynical.

Cynicism is not a character flaw. It is a rational response to incomplete design.

We are asked to fund systems whose performance is rarely presented in the only language that makes human comparison fair: what does a place like mine get for money like mine?

Imagine, just for a moment, learning that a school district with a nearly identical enrollment mix educates children with far less administrative drag and better learning growth per instructional dollar. Or that a peer city issues permits, paves roads, or clears cases at a cost structure that cannot be waved away with “we’re special.” That is not a conspiracy theory. That is a design question. Design questions can be answered, if we stop accepting fog as a management strategy.

Before we build the instruments of peer comparison, we have to stop understating what already leaks, bloats, and under-delivers in plain sight. Innovation begins with facing reality, not romanticizing it.

The scale hiding in plain sight

If this were only a few bad actors and a few delayed audits, a nice annual report and a press release would be enough. The public record says otherwise. What we are looking at is a systems problem: structural error and theft measured in hundreds of billions; spending that sprints past simple population-and-inflation baselines; and institutions whose staffing mix drifts toward administration while the work citizens think they are buying becomes relatively thinner.

Let’s start at the federal level, not because your city council or school board is less important, but because the national numbers are large enough that denial starts looking like a lifestyle choice.

The U.S. Government Accountability Office (GAO) estimated that direct annual financial losses to the federal government from fraud fall between roughly $233 billion and $521 billion a year, based on fiscal years 2018–2022 risk environments (GAO-24-105833 highlights; full report: PDF). That is not a rounding error. That is a second economy of loss living inside the first.

Then there are improper payments – the broader leak that includes overpayments, underpayments, documentation failures, and more. Agencies reported about $236 billion in improper payments in fiscal year 2023 (GAO FY2023 overview) and still about $162 billion in fiscal year 2024 after some pandemic programs wound down (GAO FY2024 press release; GAO-25-107753 PDF). Cumulative improper-payment estimates since fiscal year 2003 approach about $2.8 trillion (see GAO-25-107753). Earlier in the same stretch: roughly $281 billion in FY2021 (GAO) and $247 billion in FY2022 (GAO).

Let’s be clear, as any honest change leader must be: improper payments are not all intentional fraud. But they are the proof that our control experience is broken. If you cannot reliably send the right money to the right place, you do not have a “communications” problem. You have a design problem.
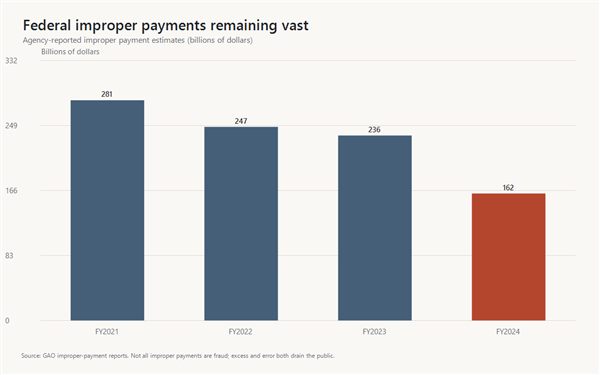
Bar chart of federal improper payment estimates for FY2021 through FY2024, declining from roughly $281 billion to $162 billion but remaining very large.

Federal agency-reported improper payment estimates remain measured in hundreds of billions even after the pandemic peak. Sources:
GAO FY2021 (~$281B);
GAO FY2022 (~$247B);
GAO FY2023 (~$236B);
GAO FY2024 (~$162B).
Scale of loss is one window. Scale of spend is another. Total federal net outlays rose from roughly $3.5 trillion in fiscal year 2014 to roughly $6.7 trillion in fiscal year 2024 – nearly a doubling in a decade in nominal dollars, with the pandemic rewriting the shape of the curve. Those figures come from the U.S. Office of Management and Budget historical outlay series published via the Federal Reserve Bank of St. Louis as FRED series FYONET, with the broader tables at OMB Historical Tables.

More spending can mean more service, more obligations, an older population, emergencies. Futurology without humility is just sci-fi cosplay. But here is the innovation insight most public debates miss: absolute “we spent more” tells citizens almost nothing about unit cost, quality, or leakage. When the size of the system grows, the need for peer-relative instruments grows with it. Otherwise we are asking people to navigate a denser fog with the same broken map.
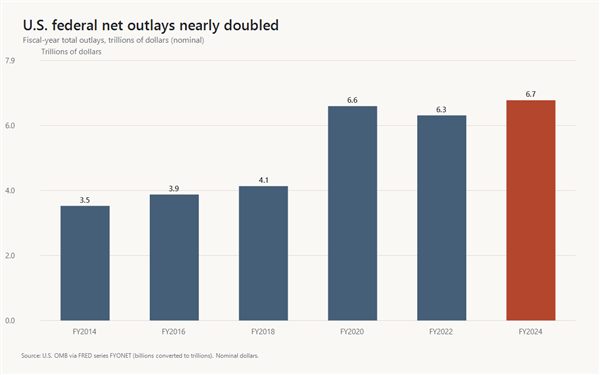
Bar chart showing U.S. federal net outlays rising from about $3.5 trillion in FY2014 to about $6.7 trillion in FY2024.

U.S. federal net outlays, selected fiscal years (nominal dollars). Source:
OMB Federal Net Outlays (FYONET) via FRED.
See also OMB Historical Tables.
Now bring it closer to home – for many of us, literally. Washington State’s Near General Fund–Outlook (NGF-O) operating budget grew from about $31.2 billion in the 2011–13 biennium to about $80.2 billion for 2025–27, roughly a 157% increase in nominal dollars, as laid out by the Washington Policy Center using the state’s NGF-O series. The 2023–25 NGF-O package, after the 2024 supplemental, was about $71.9 billion (Legislative Budget Notes PDF). The same analysis notes that if spending since the mid-2010s had tracked only population and inflation, today’s scale would be tens of billions lower. Growth is real. “We only kept up with costs” is a different claim. Official statewide spending trails also live at fiscal.wa.gov.

This is not a Washington-only story. It is a pattern story: when the bar chart climbs and the experience of value does not climb with it, citizens notice – even if they cannot yet prove the gap against peers.
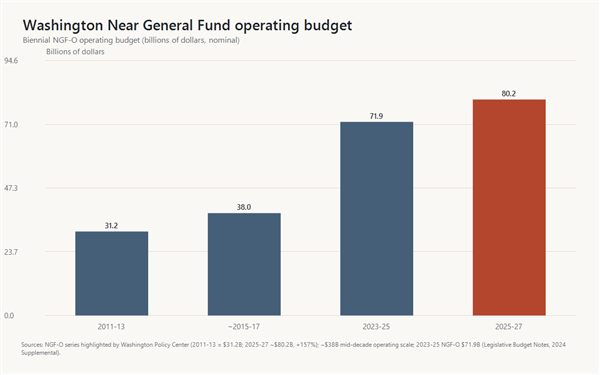
Bar chart of Washington state Near General Fund–Outlook biennial operating budgets rising from $31.2 billion in 2011–13 to about $80.2 billion in 2025–27.

Washington NGF-O biennial operating budget scale (nominal). Sources:
Washington Policy Center NGF-O growth summary
(2011–13 ≈ $31.2B; 2025–27 ≈ $80.2B; ~157%);
2023–25 NGF-O ≈ $71.9B (Legislative Budget Notes PDF);
mid-decade ~$38B scale as described in the same WPC overview of the decade-long climb.
Then there is administrative gravity, especially in higher education, where parents still believe they are buying teaching first. The Delta Cost Project at the American Institutes for Research documented something experience designers would call a quiet interface change: as managerial and professional administrative ranks grew, the average number of faculty and staff per administrator fell by roughly 40 percent at many four-year institutions between 1990 and 2012, landing near 2.5 or fewer faculty and staff per administrator (Desrochers & Kirshstein, Labor Intensive or Labor Expensive?, 2014 (PDF); AIR press summary). Professional non-faculty roles often grew faster than full-time instructional capacity, even as campuses leaned harder on part-time instructors. The underlying institutional data ecosystem lives in IPEDS and the Delta Cost Project database.

Is every new position waste? Of course not. Human organizations need coordination. The revolutionary question is not “abolish administration.” It is: do we have a transparent, peer-relative view of what administration costs relative to learning and outcomes — or are we just hoping for the best?
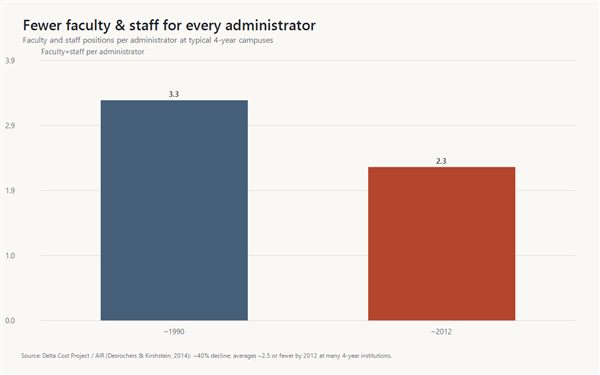
Bar chart showing faculty and staff positions per administrator declining from roughly 3.3 around 1990 to about 2.3 around 2012.

Illustrative faculty-and-staff-per-administrator levels reflecting Delta Cost Project / AIR findings of roughly a 40% decline from 1990 to 2012 at many four-year campuses, averaging about 2.5 or fewer faculty and staff per administrator.
Source: Desrochers & Kirshstein (2014) PDF.
And then there is the softer, stickier problem: corruption perceptions and nonprofit “grift” that thrives in long outcome chains. In occupational-fraud cases studied by the Association of Certified Fraud Examiners (ACFE), government organizations and for-profit firms land around a median loss of about $150,000 per case, while nonprofits still show up in about one in ten cases, with smaller median losses (about $76,000) that can still wreck a thin-margin mission (Occupational Fraud 2024: A Report to the Nations (PDF)).

Here is the human-centered insight: when public dollars pass through contractors and tax-exempt intermediaries, the distance between the taxpayer’s intention and the citizen’s experience often grows. High overhead, related parties, vague deliverables, and glossy stories without unit costs are not always illegal – but they can be a failure of value design. Law can punish fraud. Only better metrics can expose underperformance that still has good branding.

Trust tracks this story. Transparency International’s Corruption Perceptions Index has scored the United States in the mid-60s out of 100 in recent years, with multi-year deterioration flagged by Transparency International U.S. (see their CPI 2025 statement (PDF)). When perceptions fall, governance gets more expensive — because every negotiation becomes theater, and every reform takes more energy to land.

So stack it up without theatrics: hundreds of billions a year in federal fraud-loss risk and improper-payment leakage; state operating budgets that can more than double across a decade and a half; staffing mixes that load coordination relative to the work many people believe they are buying; pass-through chains that hide unit economics. That is enough reason to innovate how citizens see value. It is not a license to smear every public employee. Revolutionary change worth having is precise, not performative.

Sources for the scale claims above

Why shouting about “too much spending” never ends the argument

American public argument too often collapses into two dead ends. One side treats every dollar as proof of compassion. The other treats every dollar as proof of waste. Both can be partially right, and still leave neighbors holding a slogan instead of a shared fact.

Absolute spend is a weak instrument for learning. Larger places spend more. Harder case mixes cost more. Expensive labor markets pay more without automatically proving mismanagement. When numbers ignore context, people fight about identity instead of performance. That is not governance. That is sportswashing for budgets.

Experience design offers a simpler truth: people cannot improve what they cannot sense. If the “interface” of civic truth is either opaque PDFs or cable-news moral theater, the lived journey of taxpayers becomes cynicism – then disengagement – then the quiet permission structure where bloat, under-delivery, and yes, fraud, get more time than they deserve.

The future of healthier institutions will not be won by volume alone. It will be won by better comparisons ordinary people can use without a PhD in public finance. That is human-centered change in one sentence: redesign the sense-making layer, and better action becomes possible.

A better unit of civic truth: value relative to peers

Futurology has a bad habit: it over-promises technology and under-specifies culture. Here is the cultural upgrade that matters first.

Score places the way adults already rank experiences in the rest of life, relative to alternatives that should be similar.

Peer-relative value asks a sharper question than “how much did we spend?” It asks: among entities of roughly the same size and constraints, who delivers more real outcomes per dollar – and who is the best performer we should be learning from?

That shift changes the emotional temperature of accountability. It is harder to dismiss a neighbor when the comparison is another city that looks like yours, another county with a similar mandate set, another school district with a similar student population, another water district with similar infrastructure age. The conversation stops being “are you for or against government?” and starts being “why are we so different from our best peers?”

Relative performance does not erase values. It clarifies delivery. Compassion with weak unit economics is still compassion, and also an unfinished design problem. Efficiency without outcomes is just thrift cosplay. Citizens deserve both: what was intended, and what was delivered, at a cost that survives peer daylight.

This is innovation in the classic sense: not novelty for its own sake, but a better way of creating and measuring value — at the civic layer, where most of life is still lived.

Where fraud, grift, and bloat actually hide

Serious fraud is not always cinematic. More often it is procedural: sole-source patterns that never face real competition; nonprofit pass-throughs that struggle to show outcomes while still collecting public purpose; administrative layers that expand faster than service quality; capital projects whose unit costs and schedule slips never get benchmarked against places that built something comparable; delay as a shield because documents arrive too late to matter.

This is where passion becomes useful, and where discipline becomes non-negotiable. Performance gaps and integrity red flags are not the same thing. Treating every underperforming budget line as a crime story destroys trust the first time a good-faith agency is smeared. Treating every audit as “politics” is how poor design gets tenure.

A mature citizen practice separates the tracks, think of them as three instrument panels on the same dashboard:

  • Performance: outcomes and service quality relative to cost among peers.
  • Structure: administration share, contracting concentration, salary density versus output.
  • Integrity: delayed reporting, audit findings, related-party patterns, outcome-light grantee chains—presented with sources, confidence, and room to reply.

That separation is not gentleness toward corruption. It is how legitimate pressure remains standing when the pushback arrives. Revolutions that last are the ones that can still tell the truth under scrutiny.

The future of accountability is local (and buildable)

National drama can make local work feel small. It is not. Your life is administered by boards, districts, counties, cities, and agencies that set real prices for real services within a few miles of your door. Those are also the levels where a committed group of citizens can still change the information environment in a single budget cycle.

What is newly possible, and this is the innovation hinge, is not “AI as magic.” Magic is for marketing decks. Real innovation is AI as scale applied to the boring, necessary labor of extraction, classification, plain-language briefing, and pattern spotting — always subordinated to transparent methods and primary records. The opportunity is a suite of do-it-yourself tools that a passionate local team can download, stand up, and own: gather public data, process it with clear human oversight, and publish peer benchmarks for the jurisdiction they care about.

Think of it as open experience architecture for citizenship: not a single national score imposed from above, but many local instruments speaking the same comparative language. Cities. Counties. States. School districts. Water boards and special districts. Same idea. Local ownership. Peer daylight.

Movements fail when they ask everyone to wait for a capital-city hero. They gain power when they give capable people a way to begin where they already have skin in the game—and when the path from “I care” to “I can host a public scoreboard” is designed, documented, and downloadable. That is human-centered change: remove friction between intention and action.

From spark to local firepower: what you can actually do

Enthusiasm without a next step is just another scroll. So here is the honest promise of this movement: we are building the instruments — and you choose the jurisdiction, the intensity, and the role that fits your life.

Start with a target you can describe in one sentence. Your school district. Your city budget. Your county contracting. Your state’s administrative stack. Your water or sewer or flood-control district, the special-purpose governments that spend real money while almost nobody is watching. Passion plus a defined entity beats vague anger about “the system” every time.

Then choose a depth of start that matches your week, not your fantasy of free time:

  • Weekend scout: Pull the latest budget, CAFR, or checkbook export. List the top five cost centers. Note what is missing — outcomes, headcount by function, sole-source awards. That alone is civic reconnaissance.
  • Meeting witness: Show up once a month with three peer-comparison questions written in advance. Serious questions change how staff prepare—and how journalists listen.
  • Budget-season cadence: Build a small team and a calendar tied to when appropriations still can move. That is when numbers still have opponents who can feel them.
  • Local scoreboard: When the toolkit ships, stand up a public site — data intake, AI-assisted processing under human guardrails, and peer-relative benchmarks neighbors can share without translating bureaucracy dialect.

You do not need to do everything. You need a first mile. The guidebooks we will publish will walk those miles: how to FOIA without burning out, how to structure a peer cohort fairly, how to avoid turning a performance gap into a defamation trap, how to brief a board in three minutes, how to partner with a local reporter as an ally rather than an ambush.

Lighting a fire does not mean burning institutions down. It means raising the temperature of truth until fog can no longer survive as a management strategy—and giving thousands of local teams the same matchbook.

Pick a role that fits how you show up

From the outside, movements look monolithic. From the inside, they are division of labor — just like every innovation team that ever shipped anything that mattered. You do not have to become a full-stack auditor, web host, and public speaker on the same Tuesday night. Find the work that matches your temperament. Then find one person whose temperament complements yours.

Data gatherers and custodians. You enjoy documents more than microphones. You pull budgets, salary schedules, bid awards, board packets, 990s tied to public grants. You file public-records requests, keep the source folder honest, and leave a trail so nothing depends on a single hero’s laptop. Without clean intake, every downstream score is theater.

Benchmarking intelligence creators. You want the “so what.” You define peer sets carefully, normalize costs, choose outcome metrics that survive scrutiny, and write method notes so a critic can challenge the math without inventing motives. You turn spreadsheets into stories: unit cost of pavement, administrative share of a district, permit latency per FTE, learning growth per instructional dollar — always versus true peers. When the AI processing stack is ready, this role runs it with human judgment still on the wheel.

Website hosts and local product owners. You are willing to stand something up for your community: a place where neighbors can see the score, the sources, the trends, and an invitation to correct errors. You care about reliability and clarity – not turning a civic tool into a partisan meme machine. The downloadable suite is for you: templates, deployment path, content structure—so passion is not blocked by “I don’t know how to ship a site.”

Promoters, translators, and evangelists. You are the bridge. You do not have to invent the model. You make sure it reaches PTAs, rotary clubs, neighborhood groups, faith communities, taxpayer groups, student journalists, and people who will never open a CAFR unprompted. You translate peer-relative value into plain language, share uncomfortable comparisons without contempt, and keep the movement multipartisan enough that the score—not the team jersey—remains the headline.

Meeting advocates and budget-season operators. You take the brief to the microphone. Three questions. One peer chart. A written record. You show up when the appropriation can still move. The action packs we will release are for this role: scripts, FOIA companions, and “why the gap” one-pagers for boards and councils.

Local media partners and explanation designers. You help facts travel. A retired editor, a podcast host, a newsletter writer, a visual explainer—anyone who can turn a transparent ranking into public attention that demands reply rather than rumor. Credible pressure almost always needs a second institution’s megaphone.

Tutors of the top decile. When a peer is crushing your entity on value, someone should study them without ego—procurement habits, staffing ratios, open-data practices, facility utilization, grantee outcomes. Celebrating excellence is not a side quest. It is how reform becomes copyable instead of merely shaming. That is continuous improvement in civic form.

If you have ever left a public meeting thinking, “Someone should document this properly,” there is a role with your name on it. If you can explain a hard idea at a kitchen table, there is a role. If you can keep a folder organized, there is a role. The only non-role is permanent spectator—assuming someone else will finish the counting.

From newsletter spark to the bonfire of tools

The first act of a movement is not a software download. It is a shared refusal: we will no longer treat uncompared spending as a finished explanation of life. We will learn to ask for peer-relative value. We will demand receipts ordinary people can follow. We will treat the best performers as teachers, not enemies.

The second act is capability. That is the work now underway: do-it-yourself tooling for data gathering, careful AI-assisted processing, and public benchmarking intelligence — plus a series of role-based guidebooks so data gatherers, intelligence creators, website hosts, promoters, and budget-season operators are not inventing discipline from scratch in the dark.

Between spark and bonfire, there is a simple way to stay in formation: join the people who want the heads-up when the kits go live, when the next methods article drops, and when the first local teams start publishing peer scores others can fork and improve.

If this article lit something in you, subscribe to Human-Centered Change & Innovation Weekly. Use that signup as your seat on the bus for this movement. When the downloadable tools and guidebooks are ready — beyond the idea, into usable firepower — that is how you will know first, with practical next steps you can take in the jurisdiction you choose.

Prefer the full signup page? Open the newsletter signup page.

Tell a friend who sits through the same meetings and mutters the same unfinished sentence. Forward this to the person who always says, “If someone would just pull the numbers…” Forward it to the person who already pulls numbers but has nowhere trusted to publish them. Movements scale by invitation more than by manifesto.

For now, sit with the question every zip code deserves:

What if your community pays more and gets less than its true peers — and the only reason it continues is that nobody has finished the counting?

If that question lands, you are already part of the movement. Choose a jurisdiction. Choose a role. Get on the list. We will build the matchbooks — toolkits, methods, and guidebooks — so when you are ready to strike, the fire has somewhere local, human, and bright to go.

Frequently Asked Questions

What is “peer-relative value,” and why is it better than arguing about total spending?

Peer-relative value compares what similar governments achieve per dollar — schools with similar student needs, cities of similar size and density, utilities with similar infrastructure ages — rather than treating raw budget size as proof of success or failure. It makes accountability fairer because it adjusts for context, and sharper because it points to real best performers citizens can learn from. In experience-design terms: it gives people a better interface for understanding value.

Does this approach accuse every high-spending community of fraud?

No. Serious, human-centered accountability separates performance gaps (weaker outcomes or higher unit costs than peers) from integrity red flags (audit issues, opaque grantee chains, noncompetitive contracting patterns) that require stronger evidence. Relative benchmarking creates pressure for better results; it is not a substitute for investigation, law, or due process—and it should never be used as a license to smear people who serve in good faith.

How can I get involved before the tools are fully available?

Choose one jurisdiction you care about, start basic public-record reconnaissance, and pick a role that fits how you show up — data gathering, benchmarking intelligence, website hosting, promotion, meeting advocacy, or media partnership. Subscribe to Human-Centered Change & Innovation Weekly at bradenkelley.com/contact-me/newsletter-signup/ so you are first in line when downloadable toolkits and role-based guidebooks are ready to help stand up local peer-benchmarking sites.

Image Credits: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Cursor to clean up the article.
Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

AI Will Create a More Human Future, Not a Less Human One

An AI Soft Landing Scenario

AI Soft Landing Scenario
by Braden Kelley and Art Inteligencia


What If the Future Gets More Human?

We spend a remarkable amount of time rehearsing the wrong ending.

In one popular story, artificial intelligence hollows out work, flattens craft, and leaves people performing the emotional leftovers of automation. That is a hard landing: humans demoted by systems that do more of everything, including the parts of work that used to make us feel useful.

There is another future available to us, what I call an AI soft landing. In that future, organizations and societies deliberately design AI to absorb fragmentation, acceleration, and low-judgment transaction. What returns to humans is not emptiness. What returns is depth: larger blocks of time for insight, empathy, decision making, direction setting, problem definition, creativity, and collaboration. The future becomes more human, not less, because human attention is finally reserved for human work.

This is not a naive techno-optimism. Soft landings are designed. Hard landings arrive when efficiency is the only value on the dashboard.

The Hidden Enemy Was Never “Work.” It Was Fragmentation.

Most knowledge work did not become less meaningful because people stopped caring. It became less meaningful because attention was diced into tickets, pings, updates, status rituals, and micro-approvals. We mistook motion for progress and responsiveness for value.

Task switching is expensive. Every context shift asks the brain to unload one problem and reload another. Multiply that by a day of chats, forms, triage, and administrative glue work, and you get a workforce that is always “on” and rarely deep. Strategic thinking does not fail only for lack of talent. It fails for lack of contiguous time.

AI’s first gift, if we use it well, is not genius on demand. It is fewer interrupted minutes. When drafting, scheduling, summarizing, searching, classifying, routing, and first-pass analysis get accelerated or handled, the calendar can stop looking like confetti. Bigger time blocks reappear. And bigger blocks are the raw material of original insight.

AI Future of Work

What Humans Should Own in a Soft Landing

A soft landing is not humans “using AI better.” It is a clear division of cognitive labor, one that protects the uniquely human contribution instead of competing with the machine on volume.

In a more human future, people spend more of their capacity on:

  • Insight development — connecting weak signals into meaning, not merely producing more output
  • Empathy — understanding stakes, dignity, and lived context that no dashboard fully captures
  • Decision making — choosing under uncertainty with values, tradeoffs, and accountability
  • Direction setting — naming where we are going and why it is worth the journey
  • Problem definition — asking better questions before rushing to automated answers
  • Creativity — combining perspectives in ways that are novel, useful, and humanly resonant
  • Collaboration — building trust, resolving conflict, and making progress together

Notice what is missing from that list: being the fastest typist in the room. Soft landing excellence is not measured in tokens per minute. It is measured in clarity per hour — and in whether people leave interactions more capable, more trusted, and more oriented than before.

From Transactional Lives to Strategic Ones

When small tasks expand to fill the day, even senior roles become transactional. Leaders spend their best hours approving instead of directing, reacting instead of sensing, facilitating meetings about work rather than doing the work of judgment.

AI can reverse that inversion, but only if organizations stop using every efficiency gain to stuff more micro-tasks into the same damaged attention budget. Saving ten minutes and immediately filling them with ten more interruptions is not transformation. It is denser exhaustion.

The soft landing asks a different operating question: What human capability do we want more of, now that machines can carry more of the glue?

If the answer is “more throughput at any cost,” you will automate people into thinner slices of busyness. If the answer is “more strategic quality, better problem framing, deeper customer and employee understanding,” AI becomes a scaffold for human depth. Less task switching. More deliberate thinking. Fewer performative updates. More real collaboration around decisions that matter.

AI Human Endeavors

How Leaders Design a Soft Landing (Instead of Hoping for One)

Human-centered change makes soft landings practical. A few design moves matter more than tool catalogs:

  1. Automate the glue, not the judgment. Route AI toward fragmentation: search, draft, summarize, schedule, classify, prepare. Keep humans responsible for choices with ethical, relational, or strategic consequence.
  2. Protect deep-work blocks as policy, not privilege. If AI creates capacity, calendar culture must not immediately reclaim it for more meetings.
  3. Redefine roles around human endeavors. Job descriptions should emphasize insight, empathy, problem definition, and direction — not inbox velocity as a proxy for value.
  4. Measure success in human outcomes. Track decision quality, customer trust, employee agency, and innovation usefulness — not only cost per interaction.
  5. Teach the craft of better questions. In an AI-rich world, problem definition becomes a core leadership skill. Bad prompts and bad frames still produce confident nonsense.
  6. Build collaboration for synthesis, not status. Use reclaimed time for cross-functional sense-making, not another dashboard review theater.

This is experience design for the future of work: design the system so people can be fully human on purpose.

The Choice Ahead

Futurology is not prediction cosplay. It is responsibility with a longer horizon.

We can use AI to compress people into ever-faster transaction machines. Or we can use it to return something modern work has been quietly stealing: the ability to think, feel, decide, and create with integrity.

The soft landing is the second path, a future where machines handle more of the small so humans can do more of the meaningful. Where strategy is less of a slide ritual and more of a practiced habit. Where customer and employee experience improve not only because algorithms personalize, but because people finally have the attention required for empathy and judgment.

A more human future will not arrive by accident. It will be designed by leaders who refuse to confuse automation with progress, and who insist that the best use of artificial intelligence is the expansion of human capacity where it still matters most.

Frequently Asked Questions

What is an AI soft landing?

An AI soft landing is a future in which artificial intelligence absorbs fragmented, transactional tasks so humans can spend more time on deeper endeavors — insight, empathy, decision making, direction setting, problem definition, creativity, and collaboration — making work more human rather than less.

How does AI reduce task switching at work?

AI can handle or accelerate small tasks such as drafting, summarizing, searching, scheduling, classifying, and routing. When organizations protect the time this frees, instead of immediately filling it with more interruptions, people gain larger blocks for strategic thinking and higher-quality collaboration.

What should leaders do to make the future more human with AI?

Leaders should automate glue work rather than human judgment, protect deep-work capacity as policy, redesign roles around human endeavors, measure human outcomes as well as efficiency, invest in better problem definition, and use reclaimed time for real collaboration and decision quality — not denser busyness.

Image Credits: Cursor

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Cursor to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
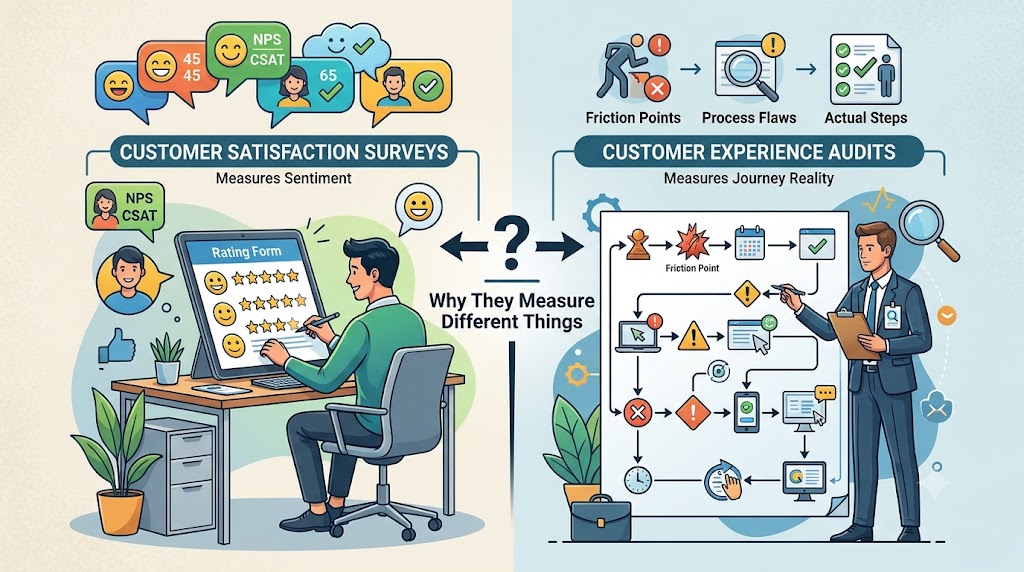
Customer Experience Audit vs. Customer Satisfaction Survey

Why They Measure Different Things

Customer Experience Audit vs. Customer Satisfaction Survey

by Braden Kelley and Art Inteligencia

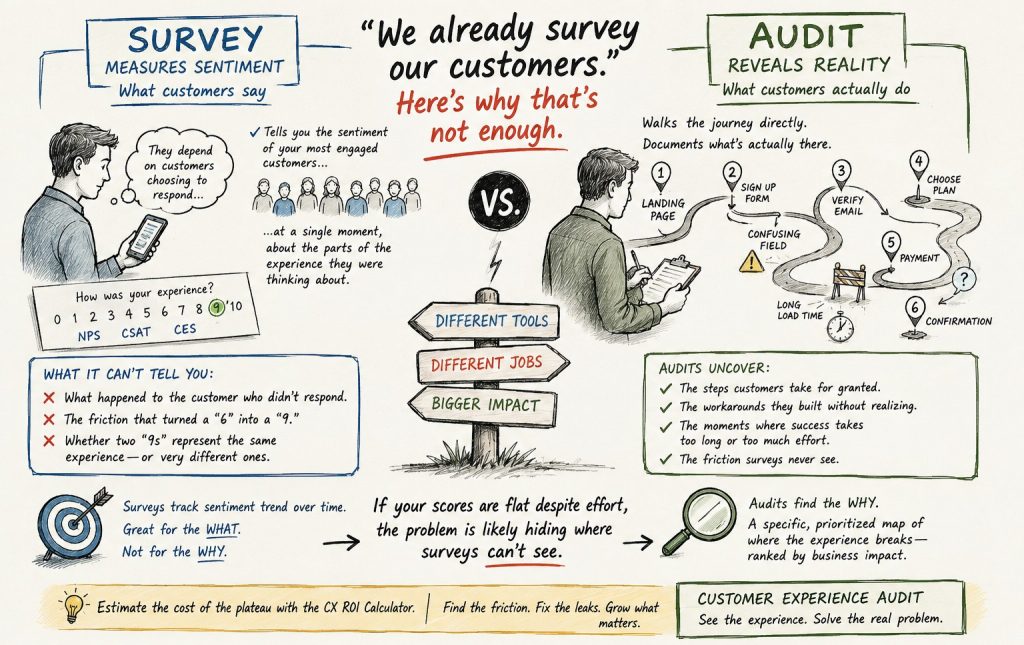
“We already survey our customers” is the single most common objection I hear when I raise the idea of an experience audit, and it’s a reasonable one on the surface — why pay for a second measurement of the same thing? The honest answer is that a survey and an audit aren’t measuring the same thing at all. They’re not even measuring in the same direction.

A survey measures what customers are willing to tell you

NPS, CSAT, and CES all share a structural feature: they depend entirely on a customer choosing to respond, and then choosing to be candid in that response. That’s not a flaw in the instrument — it’s simply what the instrument is. It tells you the sentiment of your most engaged customers (response rates skew toward people who feel strongly, in either direction) at a single moment, about the parts of the experience they happened to be thinking about when the survey arrived.

What it structurally cannot tell you: what happened to the customer who didn’t respond. What the friction actually looked like, step by step, that produced a “6” instead of a “9.” Whether a “9” from one customer and a “9” from another represent the same underlying experience, or two very different ones that both happened to land on the same number.

An audit measures what’s actually happening in the journey

An audit doesn’t ask customers to self-report — it walks the journey directly, the way a real customer experiences it, and documents what’s actually there. That distinction matters most exactly where surveys go quiet: the steps a customer takes for granted and never thinks to mention, the workaround they built without realizing it was a workaround, the moment where the process technically succeeded but took four times longer than it should have.

You can walk journeys for clients whose NPS had been flat, technically acceptable, for years — and find friction serious enough to explain real revenue loss, sitting in a step that had simply never come up in a survey response because no customer thought to complain about something they’d quietly adapted to.

Where each one actually earns its place

None of this makes the survey obsolete — it makes it a different tool for a different job. A survey is the right instrument for tracking sentiment trend over time, cheaply and continuously, across your whole customer base. It’s the wrong instrument for finding out why the trend is what it is, or for finding the friction nobody thought to mention.

An audit is the right instrument for that “why” — for producing a specific, prioritized map of where the experience actually breaks, ranked by business impact. It’s not something you run monthly; it’s something you run when the survey data has told you that something’s wrong without telling you what.

The tell that you need one, not the other

If your satisfaction scores have been flat — not declining, just plateaued — despite genuine effort to improve them, that’s usually the clearest signal that the problem lives somewhere the survey can’t see, and that more survey data won’t produce a different answer than the data you already have. That’s the specific situation an audit is built for.

If you want a rough sense of what that plateau might be costing before committing to a diagnosis, the CX ROI Calculator is a fast way to put a number on it. When you’re ready to find out exactly where the friction is living, that’s what a Customer Experience Audit is for.

Customer Experience Audit versus Customer Satisfaction Survey Infographic

Want to learn more about the value of having an independent Customer Experience Audit done? Or are you ready to invest in one?

Image Credit: Gemini, ChatGPT

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Claude to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
Building the Business Case for a Customer Experience Audit

What the C-Suite Actually Asks

Building the Business Case for a Customer Experience Audit

by Braden Kelley and Art Inteligencia

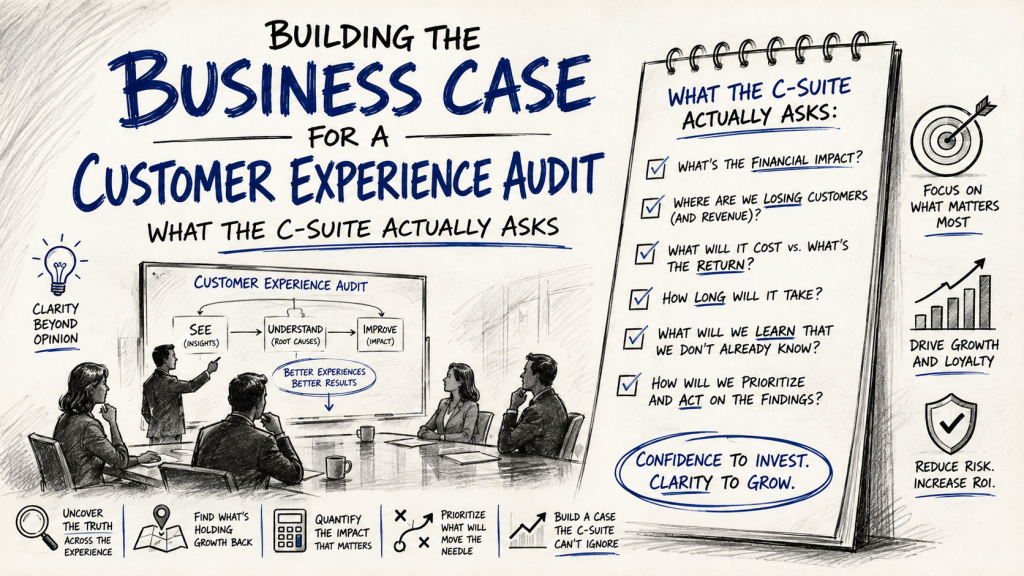
Every Customer Experience (CX) leader I’ve worked with believes, correctly, that their organization needs a customer experience audit. Very few of them get the budget approved on the first try. The gap almost never comes down to whether the need is real — it comes down to whether the person championing it walked into the room prepared for the four questions a C-suite reliably asks, in roughly this order.

“What does this cost us if we do nothing?”

This is the opening question, and it’s the one the CX ROI Calculator exists to answer. Walk in with your own churn rate, revenue per customer, and a modeled range — conservative to optimistic — rather than an industry statistic borrowed from a research report. A number that’s obviously yours survives scrutiny. A number that’s obviously generic invites the room to argue with the source instead of the substance.

“Why an audit, and not just another survey?”

This is where most business cases quietly fall apart, because the honest answer requires admitting a limitation of what you’re already doing. Your NPS and CSAT programs measure what customers are willing to tell you. An audit measures what’s actually happening in the journey, including the parts customers work around instead of reporting. If your organization has been running satisfaction surveys for years and CX metrics still haven’t moved the way they should, that’s not evidence the audit is unnecessary — it’s usually the single best evidence that it is. Surveys have had their chance to find the problem. They haven’t. A different method is the correct next step, not a redundant one.

“What will we actually be able to do differently afterward?”

An executive approving a budget is not funding a diagnosis for its own sake — they’re funding the decisions the diagnosis will enable. The strongest version of this answer is specific: an audit produces a prioritized list of friction points ranked by business impact, not a general health score. Walk in already able to name the kind of decision it unlocks — “we’ll know whether to fix onboarding or billing first” is a far stronger sentence than “we’ll understand our customers better.”

“How disruptive is this, and how long until we see something?”

This is the question that kills otherwise-approved initiatives at the last step, usually because nobody addressed it until it was asked live in the room. Have the realistic timeline ready before you’re asked for it, not after: when the audit starts, what it requires from internal teams, and when the first findings arrive. Vagueness here reads as risk, even when the actual answer would have been reassuring.

Sequencing the case correctly

The order matters as much as the content. Lead with the cost of inaction (the number), and the room is primed to hear the diagnosis as the obvious next step rather than an added expense. Lead with the audit itself, and you’re immediately negotiating from a weaker position — explaining a cost before anyone in the room has agreed there’s a problem worth solving.

If you haven’t run your own numbers yet, start with the calculator — it’s the fastest way to walk into that first conversation with your own defensible figure instead of someone else’s. When you’re ready to talk about what an audit specifically finds and how it runs, the audit page has the detail, and I’m glad to answer the disruption and timeline questions directly if you’d rather hear them from me before you’re asked them by your own leadership.

Building the Business Case for a Customer Experience Audit

Image Credit: Gemini, ChatGPT

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Claude to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
The Customer Experience Costs Your ROI Calculator Can’t See

The Customer Experience Costs Your ROI Calculator Can't See

by Braden Kelley and Art Inteligencia

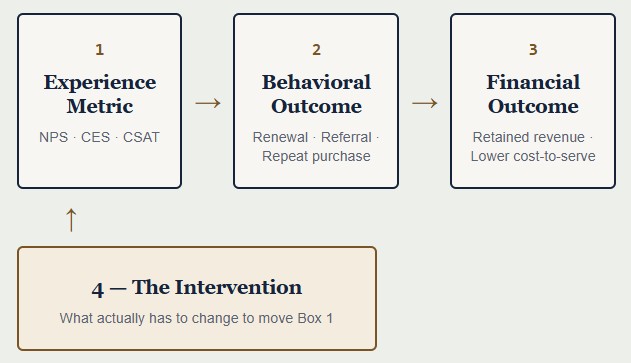
If you’ve run your numbers through the CX ROI Calculator, you already have a real, defensible number — built on your churn rate, your revenue per customer, and the same research-backed value chain I’ve written about before. That number is useful. It’s also almost certainly an undercount, and it’s worth understanding exactly why before you present it as the whole picture.

The model only sees what you’re already measuring

The four-step value chain — metric moves, behavior changes, revenue follows — is a genuinely good way to translate NPS or CSAT into dollars. But notice what it depends on: an experience metric you’re already tracking. That’s the model’s strength and its blind spot in the same breath. It can only quantify the friction that shows up in a score someone bothered to give you.

Four Step Value Chain

Most friction doesn’t show up in a score. It shows up nowhere, until it shows up in the renewal number six months later.

Three costs that live outside the metrics

The silent downgrade. A customer who’s frustrated rarely cancels immediately. More often, they quietly reduce usage, delay an upgrade they were considering, or let a seat go unfilled at renewal instead of adding the three they’d planned to add. None of that trips a churn alert — churn alerts fire on cancellation, not on quiet contraction. By the time it’s visible in a churn dashboard, you’re measuring the outcome of a decision the customer made months earlier, for reasons nobody on your team ever heard about.

The workaround. When something in the experience is broken, customers don’t reliably tell you — they build a workaround and keep using your product anyway. I’ve sat in on customer interviews where someone described, almost proudly, a twelve-step manual process they’d built to avoid a feature that didn’t work the way they needed. That customer will show up in your NPS survey as a “7” — not a detractor, not a promoter, just quietly tolerating a cost you don’t know exists. A workaround is a real cost to serve, it just never gets coded as a support ticket or a complaint.

The frontline save. Your support and success teams are, right now, absorbing friction on your behalf — smoothing over a confusing invoice, manually fixing what an automated process got wrong, apologizing for something they didn’t cause. Every one of those saves is a real cost (in time, in morale, in the eventual departure of your best frontline people), and every one of them is specifically designed, by the person doing it, to be invisible to leadership. That’s their job. It also means your dashboards are structurally blind to exactly the problems your best people are working hardest to hide from you.

Why this isn’t an argument against the calculator

None of this is a reason to skip the ROI modeling — a defensible number beats no number, and if you haven’t run yours yet, start there. It’s a reason to be honest about what the number represents: a floor, not a ceiling. It quantifies the experience gaps you can already see. It has no way to quantify the ones nobody’s told you about yet.

That’s the specific gap a Customer Experience Audit is built to close. Where the ROI model starts from your existing metrics and works outward, an audit starts from the actual customer journey — walked directly, not inferred from a survey response rate — and finds the workarounds, the silent downgrades, and the frontline saves before they’ve had time to show up as a number at all. (If terms like “cost to serve” or “revenue leakage” aren’t consistent vocabulary across your team yet, the Experience Design Glossary is a quick way to get everyone aligned before that conversation.)

Run the calculator first. It’ll tell you the size of the problem you already know about. The audit tells you what else is there.

Get the CX ROI Benchmark Report — the full industry benchmark table with sources, the CX Value Chain framework, and answers to the five objections a CFO is most likely to raise. Enter your email and we’ll send it straight to your inbox.


If after exploring the ROI calculator you would like to explore unlocking revenue opportunities for your business with a Customer Experience Audit, contact me directly. I’m happy to have a no-obligation conversation about whether an audit makes sense for your current situation.

Image Credit: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Claude to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.
Why CSAT Can Look Fine While Revenue Leaks

Why CSAT Can Look Fine While Revenue Leaks

by Braden Kelley

Your dashboard says customers are satisfied. CSAT is green. The quarterly deck gets a polite nod. Meanwhile, expansion stalls, renewals quietly soften, and support costs creep up — and nobody can point to a single “bad” survey score that explains it.

That isn’t a mystery. It’s a metric paradox: CSAT can look fine while revenue leaks, because satisfaction surveys and financial outcomes measure different things on different clocks.

If you lead CX, product, support, or a P&L, this gap is where budget conversations die. Leaders feel the leak. The score refuses to confess. So the investment stalls.

What CSAT Actually Measures (and What It Doesn’t)

CSAT usually answers a narrow question: how satisfied was someone with a specific interaction or recent experience? That’s useful. It is also incomplete.

CSAT tends to miss:

  • Silent churn — customers who never complain, then don’t renew, don’t expand, or quietly reduce usage
  • Effort and friction — people who “succeed” after three workarounds and still tick Satisfied because the alternative was worse
  • Non-respondents — the angry and the indifferent often skip the survey; the polite remain
  • Journey seams — handoffs between marketing, sales, onboarding, billing, and support where trust dies between touchpoints
  • Lag — revenue damage compounds for months before it shows up as a churn spike leadership will fund

So the score can stay “fine” while the experience failures draining your P&L keep working.

The Metric Paradox in Plain Language

Here’s the pattern I see in Customer Experience Audits:

  1. A customer hits friction (confusing onboarding, surprise fees, repeated authentication, a broken promise after purchase).
  2. They still complete the task — eventually — so the transactional CSAT looks acceptable.
  3. They tell fewer colleagues. They stop exploring add-ons. They price-shop next renewal. They open more tickets.
  4. Finance sees softer expansion and higher cost-to-serve. CX sees a green dashboard.
  5. Both sides are “right” inside their metrics — and wrong about the business.

CSAT is not lying. It’s answering a different question than the one the CFO is asking.

Why Leaders Trust the Wrong Green Light

Organizations over-index on CSAT (and sometimes NPS) because the number is:

  • Familiar in the board pack
  • Easy to benchmark
  • Simple to own in a slide

What’s missing is the chain from experience → behavior → dollars. Without that chain, “improve CX” sounds like a vibe. With it, friction becomes a funding conversation.

I’ve written separately about how to calculate customer experience ROI using that chain. This piece is about why you need it even when — especially when — CSAT looks fine.

Five Signs CSAT Is Masking Revenue Leakage

  1. High CSAT, flat or falling expansion — satisfied enough to stay, not inspired to buy more.
  2. High CSAT, rising contact rate — people are “satisfied” with heroic recoveries you shouldn’t need.
  3. High CSAT in support, weak onboarding completion — you’re measuring the rescue, not the journey.
  4. Promoters who still churn on price — affection without switching costs or realized value.
  5. Teams arguing about the score instead of walking the journey — the map has replaced the territory.

If two or more of these feel familiar, your dashboard is under-reporting risk.

What to Measure Alongside CSAT

Keep CSAT. Add instruments that speak to money and effort:

  • Leading behaviors: activation, time-to-value, repeat purchase, expansion, referral attempts
  • Effort: CES or task completion without assistance
  • Cost-to-serve: contacts per customer, repeat contacts, escalation rate
  • Experience Level Measures (XLMs): human-success metrics tied to specific “ugh” moments — not just uptime SLAs (more on XLMs here)
  • Journey evidence: what an outside-in audit finds when someone actually walks the experience

Scores without journeys produce false calm. Journeys without dollars produce false urgency. You need both.

Put a Number on the Leak (Even a Conservative One)

You don’t need false precision. You need a credible range that makes the paradox discussable in a budget meeting.

Start with what you already know — customers, revenue per customer, churn, service cost — and estimate what a realistic improvement in retention or cost-to-serve is worth annually.

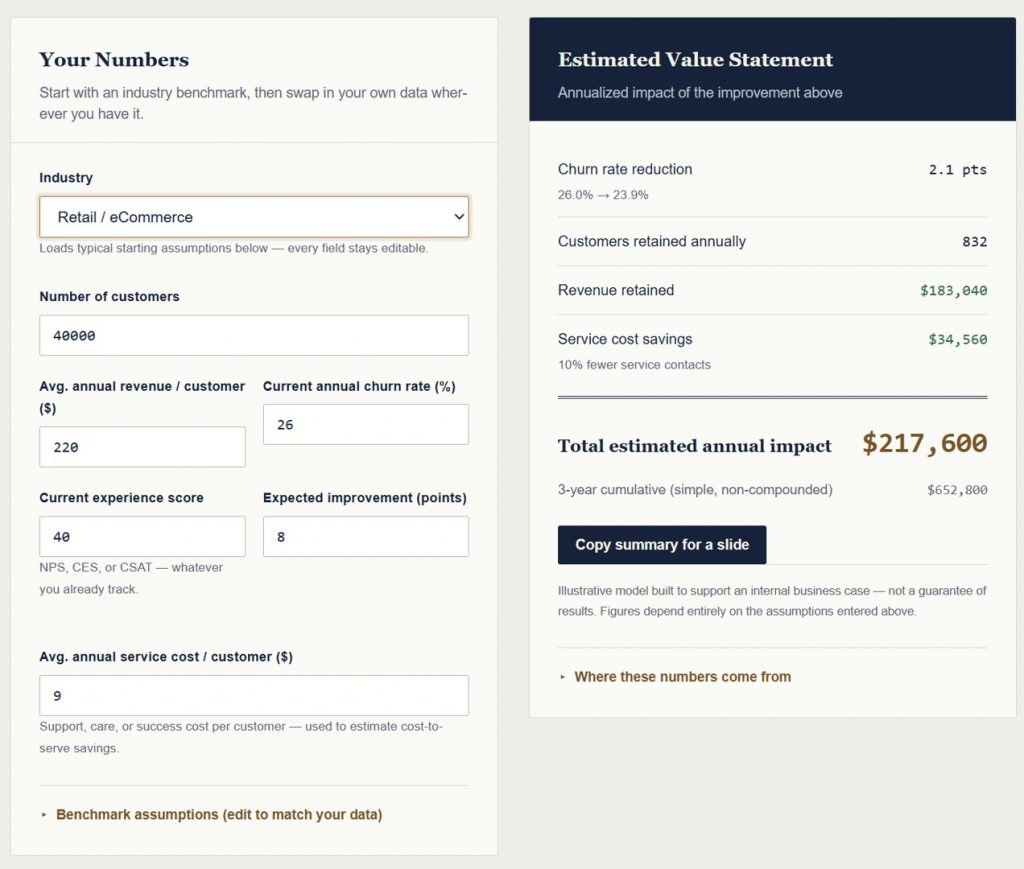
Customer Experience ROI Calculator

Use the free Customer Experience ROI Calculator →

It runs that estimate with your numbers (or industry starting points), and you can copy a summary for a slide. The point isn’t to worship the model. The point is to stop pretending a green CSAT tile equals a healthy P&L.

From Estimate to Action

Once you have a number, the next question is where the leak lives. That’s what a human-centered Customer Experience Audit is for: walk the real journey, find the friction inventory, and prioritize fixes by revenue impact — not by whoever shouted loudest in the last QBR.

CSAT can look fine while revenue leaks. The organizations that pull ahead are the ones willing to measure the leak — then fix the experience that caused it.

Next step: Run the CX ROI Calculator (about two minutes). If the estimate bothers you, that’s useful information — and a good reason to talk about an audit.

The fastest way to see this framework in action is to run it against your own business — enter your customer count, revenue per customer, and current churn rate (or start from an industry benchmark), and it estimates the annual revenue and cost-to-serve impact of a defined experience improvement, along with a summary you can paste straight into a slide.

Get the CX ROI Benchmark Report — the full industry benchmark table with sources, the CX Value Chain framework, and answers to the five objections a CFO is most likely to raise. Enter your email and we’ll send it straight to your inbox.


If after exploring the ROI calculator you would like to explore unlocking revenue opportunities for your business with a Customer Experience Audit, contact me directly. I’m happy to have a no-obligation conversation about whether an audit makes sense for your current situation.

Image Credit: Cursor

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Cursor to clean up the article and add images.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

Why Conversations Are the New Digital Gold

The Big New Revenue Opportunity for Google, OpenAI and Anthropic

Why Conversations Are the New Digital Gold

by Braden Kelley and Art Inteligencia


I. Introduction: The Disruption of the Clickstream

For over two decades, the digital economy operated on a straightforward, predictable currency: the clickstream. Organizations built vast marketing engines, customer experience frameworks, and product strategy backlogs around keyword volumes, cost-per-click (CPC) bidding, and web analytics. If you could capture user search intent at the top of the funnel and guide them through a sequence of web pages, you owned the customer relationship.

That paradigm is experiencing an irreversible structural breakdown. We are witnessing a profound behavioral migration away from typing fragmented queries into a text box toward engaging in fluid, multi-turn dialogue with generative AI assistants. Whether users are speaking directly to Gemini on Android and iOS devices or consulting ChatGPT and Claude for complex decision-making, the mechanics of discovery have fundamentally changed.

The Death of “10 Blue Links”

The traditional search results page — dominated by ranked links, banner inventory, and sponsored listings — is giving way to synthesized, conversational answers. When users speak to an ambient assistant, they aren’t looking for a list of websites to evaluate independently; they are seeking a resolved outcome. Speech-to-text, natural voice interaction, and inline AI reasoning mean problem-solving happens within the dialogue itself, drastically reducing the need to visit external brand properties.

The Shrinking Digital Surface Area

This rise in zero-click interactions presents an existential challenge for traditional web analytics and performance marketing. As consumer click-through rates decline, brands face a dramatic reduction in their visible digital touchpoints:

  • Attribution Blindness: Traditional conversion tracking breaks down when the research and evaluation phases occur entirely inside an AI model’s context window.
  • Diminishing SEO Returns: Optimizing for keywords and site traffic yields shrinking returns when AI models synthesize answers directly without referring users to source URLs.
  • Loss of Direct Engagement: The digital surface area where brands can present their unique visual identity, messaging, and experience design is rapidly compressing.

The Foresight Premise

In any major technology transition, structural shifts create immediate information asymmetries. Every change initiative produces winners and losers based on who recognizes where value is re-aggregating. The primary battleground of the AI era is no longer about driving traffic to a destination — it is about controlling, understanding, and translating the rich context of human conversational intent.

II. The Blind Spot: How Brands Are Losing the Voice of the Customer

The transition from traditional web search to ambient AI interaction is creating an unprecedented intelligence blackout for commercial enterprises. For years, organizations refined their understanding of consumer behavior by tracking the digital breadcrumbs left across search engines, landing pages, and digital storefronts. As customer decision-making migrates into private, dynamic AI dialogues, that pipeline of actionable data is drying up.

This shift represents far more than a marketing disruption — it is a fundamental erosion of the qualitative feedback loops that drive modern product innovation and experience design.

From Keywords to Unfiltered Intent

Keyword search was always a compromised, low-fidelity medium. Users learned to compress their complex human needs into unnatural, fragmented phrases meant to nudge a search algorithm into producing useful links. The language of traditional search was structured around constraints rather than context.

Generative AI and voice interfaces have eliminated those constraints. When individuals speak to an assistant like Gemini, ChatGPT, or Claude, they express their needs with full nuance, nuance, and emotional framing. Consider the structural difference between these two modes of inquiry:

  • Traditional Search Query: best running shoes flat feet
  • Conversational Intent: “I’m training for my first rainy marathon in three months, but I have mild overpronation and a old knee injury. What shoes under $150 will give me enough stability without causing blisters on long runs?”

The conversational prompt contains rich layers of context: budget parameters, timeline constraints, physical vulnerabilities, weather considerations, and personal goals. However, because this interaction takes place within an AI context window rather than on a brand’s website or an open search results page, the business whose product is being evaluated receives zero visibility into the exchange.

The Customer Insight Vacuum

As consumer preference formation moves into continuous multi-turn conversations, brands are losing access to critical moments of truth across the buyer journey. This creates three severe operational blind spots:

  • Unseen Feature Trade-offs: Brands cannot see which specific product attributes, specifications, or pricing structures cause a potential customer to eliminate them from consideration during an AI dialogue.
  • Invisible Competitive Comparisons: When an AI assistant evaluates three competing solutions side-by-side for a user, the losing brands receive no signal explaining why the model recommended an alternative.
  • Obsolete Voice-of-Customer (VoC) Data: Traditional surveys, focus groups, and social listening tools capture lagging, highly filtered opinions. They fail to reflect the real-time, unvarnished friction points articulated during natural conversations with AI.

The Experience Design Risk

Without access to the rich contextual signals embedded in everyday user prompts, corporate experience design initiatives risk operating on outdated assumptions. Customer journey maps, persona frameworks, and friction-point analyses quickly become stagnant snapshots of an obsolete digital funnel.

To design meaningful, human-centered experiences, leaders must understand the authentic language and evolving expectations of their audience. When that language is spoken exclusively to third-party AI assistants, organizations that fail to secure access to conversational intelligence will find themselves innovating in the dark.

III. The Big Pivot: Monetizing Context, Not Clicks

Every major shift in technology redistributes economic value. As traditional cost-per-click advertising yields diminish under the pressure of zero-click conversational answers, the business models of the AI platform giants — Google, OpenAI, and Anthropic — must evolve. The next multi-billion-dollar monetization opportunity will not come from placing banner ads inside conversation flows, but from harvesting, structuring, and licensing the vast reservoir of real-time human intent being shared with their models every second.

Human conversation is the new digital gold. For businesses desperate to recover lost visibility into the buyer journey, aggregated conversational intelligence represents the ultimate strategic asset.

The New Revenue Engine for AI Titans

Advertising models built on static keyword triggers are fundamentally mismatched with fluid, multi-turn AI reasoning. Forcing intrusive sponsored links into a personalized voice response destroys the user experience. Instead, AI providers are positioned to monetize the output side of their platforms by acting as enterprise data brokers, transforming raw dialogue logs into high-value intelligence feeds.

By capturing how millions of people naturally discuss needs, compare options, and express frustrations, platform owners can package anonymized context into enterprise-grade analytics products that command recurring software-as-a-service (SaaS) subscription premiums.

Packaging the “Digital Gold”

This new intelligence layer will yield actionable commercial products tailored for product strategists, marketers, and executive leaders:

  • Brand Health & Recommendation Telemetry: Real-time quantitative dashboards tracking how frequently a brand is mentioned during advice seeking, the sentiment surrounding those mentions, and the exact contexts in which competitors are favored.
  • Unmet Need & Latent Demand Mapping: Algorithmic extraction of emerging consumer pain points long before they manifest in formal search trends, support tickets, or market research reports.
  • Decision Boundary & Friction Analysis: Synthesized reports detailing the specific trade-offs (price points, missing features, usability concerns) that systematically cause prospective buyers to reject a product during AI-driven evaluations.

Democratizing Enterprise Intelligence

The power of conversational analytics lies in its scalability across the economic spectrum. While enterprise corporations will pay premium tiers for custom API integrations and real-time category alerts, small and medium-sized businesses (SMBs) will finally gain access to market research previously reserved for Fortune 500 budgets.

A local bike shop or boutique software firm could subscribe to a regional category feed to instantly discover the precise features or price barriers driving customer choices in their specific niche. By turning unvarnished human dialogue into structured insight, AI platforms will unlock an indispensable revenue model powered by authentic human context.

IV. Human-Centered Change & Ethical Governance

Unlocking the commercial value of conversational data requires navigating a complex intersection of consumer trust, regulatory compliance, and organizational transformation. Because natural language dialogue contains deep personal context, commercializing this information demands rigorous ethical boundaries. The success of conversational intelligence as a revenue model hinges on maintaining strict user privacy while helping enterprises build the internal capabilities needed to act on these new insights.

Privacy by Design: The Ethical Imperative

Monetizing conversational context cannot come at the expense of individual privacy. AI platform operators must engineer robust data architecture standards that prevent the exposure of personally identifiable information (PII) while preserving strategic utility:

  • Differential Privacy & Aggregation: Injecting mathematical noise into datasets so macro-level consumer trends can be analyzed without ever exposing individual user transcripts.
  • Synthetic Data Modeling: Generating artificial, representative datasets derived from real conversation patterns, allowing brands to analyze buyer behavior without touching live user interactions.
  • Strict Brand-Level Anonymization: Ensuring that enterprise dashboards expose category-level intent and competitive positioning without revealing specific user identities or sensitive personal attributes.

Overcoming the “Surveillance” Backlash

Public perception will determine the speed at which conversational analytics becomes mainstream. If consumers view the monetization of their conversations as invasive surveillance, user churn and regulatory pushback will quickly follow. AI providers and brands must collectively frame conversational analytics around mutual value creation.

When customer intent data is anonymized and applied ethically, it leads directly to better product design, more intuitive user interfaces, and the elimination of persistent market friction points. The objective must be presented clearly: using collective, human-centered feedback to build products and experiences that better serve actual human needs.

Managing Organizational Readiness

Accessing conversational intelligence is only half the equation; corporate leadership teams must also transform how they make decisions. Applying the principles of Human-Centered Change™, organizations must actively prepare their cultures, workflows, and talent to interpret fluid conversational data rather than static web metrics.

This operational transition requires shifting leadership focus away from legacy digital KPIs like bounce rates, page views, and click-through rates toward modern conversational indicators: share of voice in model recommendations, prompt inclusion rates, and conversational intent fulfillment. Companies that successfully align their internal culture around these human-centered insights will build an enduring competitive advantage in the AI era.

V. FutureHacking™: Strategic Implications for Business Leaders

To navigate the shift from transactional clickstreams to continuous conversational context, executive leadership cannot afford a reactive stance. Applying a FutureHacking™ lens — scanning weak signals around emerging user behaviors today to anticipate the structural realities of tomorrow — reveals a multi-phase transformation in how organizations will make decisions, design experiences, and compete for market share.

The transition toward conversational intelligence will unfold across three distinct horizons over the next decade.

Near-Term Horizon (1–2 Years): The Rise of Generative Engine Optimization & Intelligence Pilots

In the immediate term, traditional Search Engine Optimization (SEO) will yield ground to Generative Engine Optimization (GEO). As organic web traffic declines, brands will pivot from optimizing page headers and backlinks to structuring brand narratives and product specifications so they are accurately ingested and cited by foundational AI models.

Concurrently, early adopter enterprises will join private pilot programs hosted by Google, OpenAI, and Anthropic. These initial telemetry dashboards will give brand managers their first high-level visibility into prompt inclusion rates, category mention frequencies, and overall model recommendation sentiment.

Medium-Term Horizon (3–5 Years): Synthetic Focus Groups & Simulated Customer Journeys

As the granularity of anonymized conversational datasets improves, market research will undergo a radical evolution. Rather than waiting weeks to conduct traditional focus groups or analyze retrospective survey results, product strategy teams will query specialized AI models trained on billions of real-world conversational signals.

Organizations will routinely run product concepts, pricing adjustments, and brand positioning messaging against synthetic persona populations. These simulated customer panels will instantly predict friction points, feature trade-offs, and competitive migration risks based on real-time consumer intent trends, drastically compressing product development cycles.

Long-Term Horizon (5+ Years): Closed-Loop Innovation Systems

Over a five-year horizon, conversational intelligence will move from a passive diagnostic tool to an active driver of automated organizational workflows. Leading enterprises will construct closed-loop innovation engines where real-time conversational data directly informs cross-functional operations:

  • Automated Backlog Prioritization: Product engineering roadmaps will dynamically re-prioritize feature requests based on unprompted feature complaints captured across category-wide AI dialogues.
  • Dynamic Experience Adaptation: Digital touchpoints and customer service flows will auto-tune their messaging and support options based on emerging friction patterns identified by ambient assistants.
  • Continuous Portfolio Alignment: Mergers, acquisitions, and line extensions will be evaluated using continuous, real-time demand signals extracted directly from human-AI problem-solving sessions.

By anticipating these structural horizons today, forward-thinking leaders can begin building the data infrastructure, talent capabilities, and agile decision-making frameworks required to turn conversational signals into market leadership.

VI. Conclusion & Key Takeaways for Innovators

The transition from transactional keyword search to ambient, multi-turn AI dialogue represents one of the most profound structural shifts in the history of the digital economy. As consumers speak directly with Gemini, ChatGPT, and Claude on their mobile devices and desktop interfaces, the clickstream era is drawing to a close. Waiting for traditional web traffic, cost-per-click efficiency, and search ad impressions to recover is not just an ineffective strategy — it is an existential risk.

The organizations that thrive in this next era will be those that recognize where strategic value has re-aggregated: away from driving website visits and toward capturing, understanding, and acting upon authentic conversational context.

Key Takeaways for Business Leaders

  • Acknowledge the Intelligence Blackout: Traditional SEO, web analytics, and click-through attribution models are providing a rapidly shrinking window into true customer behavior. Accepting this loss of visibility is the first step toward building modern, conversation-aware capabilities.
  • Prepare for the Conversational Data Economy: As traditional search advertising revenues face long-term pressure, Google, OpenAI, and Anthropic will monetize anonymized conversational data. Forward-thinking leaders should allocate budget now for emerging conversational telemetry feeds and Generative Engine Optimization (GEO).
  • Embed Human-Centered Change™: Shifting an organization from static KPIs (page views, bounce rates) to conversational metrics (share of voice in model answers, prompt inclusion, intent fulfillment) requires intentional change management. Re-align leadership, cross-functional teams, and innovation pipelines around these new signals.
  • Rethink Experience Design: Continuous multi-turn dialogues reveal unvarnished human friction points, budget constraints, and feature trade-offs. Integrate these real-time qualitative signals into your customer journey maps and product development roadmaps to eliminate customer friction faster than competitors. Invest in a Customer Experience Audit to find where you fall short.

Data was the primary oil of the early web era, but synthesized human conversation is the true gold of the AI era. By pairing ethical governance and human-centered design with the rich intent embedded in everyday dialogue, innovative organizations can illuminate their blind spots, transform their decision-making, and create products that resonate with authentic human needs.

Frequently Asked Questions

Why are traditional search advertising and click-through rates declining?
As users shift from keyword-based search boxes to ambient AI assistants like Google Gemini, ChatGPT, and Claude, they receive direct, synthesized answers rather than a list of web links. This rise in zero-click interactions significantly reduces website referral traffic and traditional ad impression volume.
How do AI platforms like Google, OpenAI, and Anthropic plan to monetize conversational data?
AI platform providers can package anonymized, aggregated conversation logs into enterprise intelligence feeds. By selling brand health telemetry, unmet need analytics, and consumer friction insights to businesses, AI companies create a massive new recurring revenue stream to complement or offset declining search ad yields.
How can businesses prepare for the shift from keyword search to conversational intelligence?
Organizations must transition their digital strategy from traditional SEO to Generative Engine Optimization (GEO), adapt internal change management frameworks (such as Human-Centered Change™) to track conversational metrics like model share-of-voice, and subscribe to emerging conversational analytics feeds to inform product design and experience strategies.


Image credits: Gemini

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Gemini to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

Surveys Are Collapsing

Conversational and Agentic VoC is How Loyalty Gets Heard

Conversational and Agentic VoC is How Loyalty Gets Heard

by Braden Kelley and Art Inteligencia


The Quiet Collapse of the Survey Layer

Something uncomfortable is happening inside customer experience programs that still treat the survey as the source of truth. Response rates are falling — sometimes sharply — even when the questionnaire itself barely changes. The invitations still go out. The dashboards still refresh. The air getting thinner is the percentage of customers willing to talk to a form.

This is not the death of listening. It is the collapse of a layer: the assumption that loyalty, satisfaction, and experience quality can be reliably extracted on demand through static instruments. Net Promoter Score is not vanishing overnight. Forms are not obsolete tomorrow morning. But both are being demoted — from verdict to signal, from system of record to starting point.

Organizations that built governance, bonuses, and “voice of the customer” theater almost entirely on survey completion are discovering a hard truth of human-centered change: when the method stops matching how people communicate, the method stops producing wisdom. You can still report a number. You just cannot pretend it represents the relationship.

The urgent question for innovators is not how to squeeze three more points of response rate out of a dying habit. It is how to hear customers in the ways they already speak — and how to turn that listening into action before loyalty quietly leaves.

Why People Stopped Talking to Forms

People did not become less opinionated. They became less willing to perform unpaid labor for brands that ask without reciprocating.

Survey fatigue is real, but it is only the surface. Timing is often wrong — a form arrives after the emotional moment has passed, or in the middle of a busy day when the only honest answer is delete. Reciprocity is weak: customers complete the ritual and see no change, so the next invitation feels like noise. Channel mismatch is growing: people already live in chat, voice, messaging, and short conversational bursts, while VoC programs still insist on a clipboard with radio buttons.

Underneath the mechanics sits an emotional job. Feedback, at its best, is a bid to feel heard. A form rarely delivers that feeling. It flattens story into score, urgency into scale, and dignity into “additional comments (optional).” When the experience of giving feedback is itself a poor experience, silence becomes rational.

Human-centered leaders should treat declining response as diagnostic data. Customers are telling you — by not answering — that your listening design is out of date.

From Scorekeeping to Sense-Making

Traditional VoC optimized for scorekeeping: capture a metric, trend it, threshold it, celebrate or panic. Sense-making asks a different question: What is changing in the lived experience, and why?

In a post-survey-dominant world, unstructured signal matters more — conversations, call notes, chat transcripts, reviews, social fragments, support themes, behavioral break points. AI makes synthesis of that mess newly practical. That does not make the score useless. It makes idolatry of the score dangerous.

The “why” can no longer be an afterthought parked in an open text field that nobody has time to read. The why is the product of modern listening. Scores become navigation lights. Narratives, patterns, and emotions become the map.

This shift also changes operating rhythm. Quarterly report theater gives way to continuous closed loops: hear, understand, act, confirm. Loyalty intelligence is less a research project and more an always-on sense-making system — still human-governed, still ethically bounded, but finally matched to the speed at which experience actually breaks.

Conversational VoC: Feedback as Dialogue

Conversational VoC replaces the clipboard with a dialogue. Instead of forcing every customer through the same static path, listening adapts — in the moment, in the channel, and in response to what the person just said.

That can look like a short adaptive chat after a key journey step, a voice interview that follows curiosity instead of a rigid script, a messaging thread that asks one good question and then the next logical one, or a human interview amplified by better prompts and synthesis. The common design principle is simple: treat feedback as conversation, not compliance.

Dialogue earns what forms forfeit. It can hold emotion without collapsing it into a single digit. It can clarify ambiguity in real time. It can meet people where they already are speaking. And it can make reciprocity visible — “we heard you, here is what happens next” — which is how listening becomes trust rather than extraction.

Done poorly, conversational VoC is just a survey wearing a chatbot costume. Done well, it is experience design applied to insight itself: respectful of time, responsive to context, and worthy of the story a customer is willing to share.

Agentic Listening: When Insight Can Act

The next leap is agentic listening: systems that do not only collect and classify, but can route, summarize, prioritize, trigger recovery, and help close the loop across teams. Insight stops dying in a dashboard and starts moving work.

This is powerful — and easy to get wrong. An agent that escalates a frustrated customer to a human with full context is care at scale. An agent that silently profiles, nudges, or “manages” sentiment without consent is surveillance with a CX badge. Human-centered innovation draws that line in the architecture, not in the press release.

Design stakes for agentic VoC

  • Consent and clarity — people should understand when listening is active and how their words will be used.
  • Privacy and minimization — collect what you need for learning and recovery, not everything you can.
  • Escalation with dignity — automation should accelerate help, not trap emotion in a loop.
  • Action accountability — if the system can trigger work, someone must own whether that work actually improved the experience.

Agentic VoC is not a replacement for human judgment. It is orchestration for listening: machines handle volume and routing; people handle meaning, ethics, and relationship repair. The brands that win will be the ones whose listening systems can act — and whose customers still feel respected while they do.

A Human-Centered Playbook for the Post-Survey Era

You do not need to burn the survey. You need to dethrone it. Here is a practical path.

  • Keep scores as signals, not idols. Use them to notice change; use conversations and behavior to explain it.
  • Build conversational intake at moments that matter. Short, adaptive, channel-native dialogues beat long retrospective forms.
  • Unify experience data. Connect feedback, journeys, and operational reality so insight is not stranded in a research silo.
  • Close loops where customers can feel them. Private recovery for individuals; visible improvement for patterns. Reciprocity is the antidote to silence.
  • Measure whether people feel heard — and whether action followed. Listening quality is an experience metric, not only a research metric.
  • Govern agentic listening for care. Decision rights, consent, escalation, and audit trails before autonomy scales.

Futurology in customer experience is often sold as more instrumentation. The deeper shift is more humane instrumentation: listening that fits human communication, sense-making that honors story, and systems that can act without making people feel managed.

Surveys are collapsing as the center of gravity. Conversational and agentic VoC are how loyalty gets heard again — not as a quarterly score, but as a living relationship that organizations are finally designed to understand.

Frequently Asked Questions

Why are customer survey response rates declining?

Response rates are falling because of survey fatigue, poor timing, weak reciprocity when feedback leads to no visible change, and a mismatch with how people already communicate through chat, voice, and messaging. Many customers still have opinions — they are less willing to share them through static forms.

What is conversational VoC?

Conversational voice of the customer (VoC) gathers feedback through adaptive dialogue — such as chat, voice, or messaging — rather than fixed questionnaires. It follows context and emotion in the moment, making customers more likely to feel heard and producing richer insight into the why behind experience scores.

What is agentic VoC and how does it differ from surveys?

Agentic VoC uses AI systems that can not only collect and analyze feedback but also route issues, trigger recovery, summarize themes, and help close the loop. Unlike surveys that mainly capture scores after the fact, agentic listening turns insight into action — when governed with consent, privacy, and human escalation.

Image credits: Cursor

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Cursor to clean up the article.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.