Author Archives: Art Inteligencia

About Art Inteligencia

Art Inteligencia is the lead futurist at Inteligencia Ltd. He is passionate about content creation and thinks about it as more science than art. Art travels the world at the speed of light, over mountains and under oceans. His favorite numbers are one and zero. Content Authenticity Statement: If it wasn't clear, any articles under Art's byline have been written by OpenAI Playground or Gemini using Braden Kelley and public content as inspiration.

The Authenticity Mandate

A Leader’s Guide to Truth Literacy and Verification Technology

LAST UPDATED: April 24, 2026 at 3:51 PM

The Authenticity Mandate

GUEST POST from Art Inteligencia


The Executive Summary: Why Truth is the New Alpha

As we navigate the complexities of 2026, we have moved past the novelty of generative AI and straight into a crisis of Experience Integrity. In an era where agentic AI can simulate human empathy and synthetic media can fabricate history in real-time, the landscape of leadership has fundamentally shifted. We are no longer just managing information flows; we are the primary stewards of reality for our customers and employees.

The Erosion of “Shared Reality”

The explosion of synthetic media is no longer a technical curiosity—it is a systemic business risk. When the phrase “seeing is believing” becomes obsolete, the friction between a brand and its audience increases exponentially. For leaders, this means moving beyond reactive fact-checking toward a proactive stance on digital provenance. If your stakeholders cannot trust the pixels, they cannot trust the promise behind them.

The Trust Premium: Truth Literacy as a Core Requirement

Truth Literacy has graduated from a niche digital skill to a foundational pillar of organizational agility. In today’s marketplace, there is a measurable “Trust Premium.” Organizations that can demonstrably verify their digital footprint earn a level of loyalty that traditional marketing spend can no longer secure. This literacy must permeate every department—from the experience designers in CX to the compliance officers in Legal.

The Stakes: From Hallucinations to Liability

The cost of inaction is no longer theoretical. We are witnessing the rise of CX Betrayal—the specific psychological break that occurs when a user realizes their interaction was built on an unverified, synthetic foundation. Beyond the erosion of brand equity, the regulatory environment now places the burden of proof squarely on the enterprise. Unverified automated decisions and AI-driven hallucinations are no longer just “technical bugs”; they are significant liabilities that can impact the bottom line and board-level stability.

The Verification Spectrum: Provenance vs. Detection

To effectively manage digital integrity, leaders must distinguish between two fundamentally different approaches: proving the truth and catching the lie. This “Verification Spectrum” defines how organizations validate the media they produce, consume, and distribute.

Provenance: The Digital Birth Certificate

Provenance focuses on the origin and history of a piece of content. Rather than trying to guess if an image is “fake,” provenance allows us to see exactly where it came from and what has happened to it since.

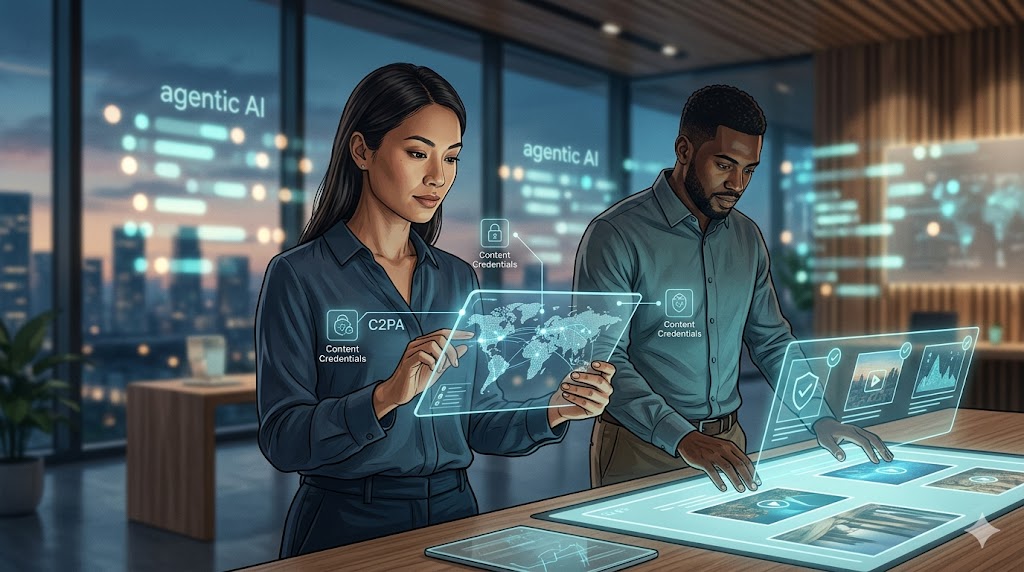
  • C2PA Standards: The Content Authenticity Initiative (CAI) and the C2PA standard provide the technical foundation for “Content Credentials.” These are cryptographic layers embedded in the file—a nutrition label for digital media—that show the camera used, the software that edited it, and any AI enhancements applied.
  • Radical Transparency: For the audience, provenance replaces suspicion with certainty. It moves the burden of proof from the user’s eyes to the asset’s metadata.

Detection: The Digital Polygraph

While provenance works for new content, detection is the necessary “defense” against the billions of existing unverified assets. Detection uses AI to monitor AI, looking for the tell-tale signs of synthetic manipulation.

  • Artifact Analysis: Modern detection engines hunt for biological inconsistencies—such as unnatural blood flow in skin (photoplethysmography) or mismatched reflections in pupils—that are difficult for generative models to perfect.
  • The Arms Race: Leaders must understand that detection is a moving target. As synthetic models improve, detection artifacts disappear, necessitating a shift toward multi-layered “defense-in-depth” strategies that look for behavioral anomalies rather than just visual ones.

Watermarking and Fingerprinting

These technologies serve as the connective tissue between provenance and detection.

  • Invisible Watermarking: Embedding durable, imperceptible signals into content that can survive compression, cropping, or screenshots. This allows brands to “claim” their official communications even when they are reshared in low-trust environments.
  • Digital Fingerprinting: Creating a unique mathematical hash of a file to track its distribution and detect unauthorized tampering or “vibe-coding” by third parties.

Building a Truth-Literate Culture

Technology alone cannot solve the trust crisis. True organizational resilience requires a fundamental shift in how your workforce perceives and interacts with information. Building a “Truth-Literate” culture means moving beyond passive skepticism—which often leads to cynicism and paralysis—toward active verification.

Upskilling for the “Post-Truth” Workplace

In a world where high-fidelity fakes are ubiquitous, we must equip our teams with the cognitive tools to navigate ambiguity. This isn’t just about training people to spot deepfakes; it’s about fostering a mindset of “Zero-Trust Content.”

  • Critical Inquiry: Teaching employees to evaluate the source, the medium, and the intent behind every interaction.
  • The Cost of Speed: Encouraging a “pause” in decision-making when dealing with high-stakes digital assets, ensuring that the pressure for real-time response doesn’t bypass necessary verification protocols.

Operationalizing Veracity: Truth as a Workflow

Verification must move from an afterthought to a core component of the content lifecycle. Whether it is a marketing campaign, a CEO’s internal video address, or an HR training module, truth must be “baked in” from the start.

  • Verification Checkpoints: Integrating automated and human-in-the-loop verification steps into your creative and communications pipelines.
  • Provenance-First Creation: Standardizing the use of tools that automatically generate content credentials at the moment of creation, ensuring your internal assets are “born authentic.”

Closing the Governance Gap

The most significant risk to an organization is often the lack of alignment between departments. Truth Literacy requires a unified front that bridges the traditional silos of Legal, IT, and Customer Experience (CX).

  • The Unified Policy: Developing a clear, cross-functional charter on how your organization uses synthetic media, how it discloses that usage, and how it responds to “synthetic attacks” on the brand.
  • Stakeholder Alignment: Ensuring that the Legal team understands the technical capabilities of provenance, while the CX team understands the ethical boundaries of AI-driven engagement.

The Verification Landscape: Leading Companies and Startups

For leaders to move from awareness to action, it is essential to understand the vendor ecosystem. The market for “Truth Tech” is currently bifurcating into two distinct categories: Shields (technologies that detect and block synthetic threats) and Certificates (technologies that prove an asset’s authentic origin).

The following table outlines the key players and the specific organizational challenges they address:

Category Key Players What They Solve
Enterprise Provenance Adobe (CAI), Truepic, Microsoft Implementing “Content Credentials” to provide an immutable history of edits and origins for digital assets.
Deepfake Detection Reality Defender, Sentinel, Pindrop Real-time analysis to detect synthetic audio and video in high-stakes environments like banking and media.
Strategic Verification NewsGuard, Factmata Providing “Trust Scores” and contextual intelligence for data sources and information cycles.
Forensic Integrity Attestiv, Sensity AI Authenticating photos and videos for insurance, legal, and forensic applications where evidence tampering is a risk.
Authentication Infrastructure Digimarc, Sony Invisible digital watermarking and sensor-level verification at the point of capture (e.g., in cameras).

Choosing Your Partners

When evaluating these vendors, leaders should not look for a “silver bullet” but rather a defense-in-depth strategy. A robust truth infrastructure requires both a “hardened” creation process (provenance) and an “intelligent” perimeter (detection).

  • Interoperability: Ensure the technology adheres to open standards like C2PA, so your verified assets are recognized across the global digital ecosystem.
  • Scalability: Look for solutions that can integrate directly into your existing CMS, CRM, and communication platforms without adding significant latency to the user experience.
  • Ethical Alignment: Partner with companies that prioritize user privacy and the ethical use of metadata, ensuring that in your quest for truth, you do not compromise human agency.

The Strategic Roadmap: Moving from Reaction to Resilience

Transitioning an organization from a state of reactive skepticism to one of proactive resilience does not happen by accident. It requires a structured, phased approach that aligns your technical capabilities with your cultural values. This roadmap provides the high-level steps necessary to secure your “Experience Integrity.”

Phase 1: The Audit—Assessing Your Vulnerability

Before you can defend your truth, you must understand where it is most likely to be attacked. This phase involves a comprehensive assessment of your “Truth Surface Area.”

  • Identifying Friction Points: Mapping the customer and employee journeys to identify where unverified information could cause the most damage (e.g., automated customer support, financial reporting, or executive communications).
  • The “Shadow AI” Audit: Understanding how your teams are currently using generative tools and identifying where synthetic content is being created without provenance or oversight.

Phase 2: The Infrastructure—Hardening the Foundation

Once the vulnerabilities are mapped, the focus shifts to building the technical and procedural “shields” that will protect the organization.

  • Standardizing Provenance: Adopting open standards like C2PA across your content creation stack. This ensures that every official asset your organization produces carries an immutable “Birth Certificate.”
  • Vendor Selection: Curating a stack of verification technologies—choosing the right mix of detection and provenance tools that integrate seamlessly with your existing infrastructure.
  • The “Stable Spine” of Data: Ensuring your internal data repositories are audited and secure, serving as the “Single Source of Truth” that feeds your agentic AI models.

Phase 3: The Disclosure Policy—The Transparency Standard

The final phase is about setting the standard for how you interact with the world. In an age of synthetic reality, radical transparency is your greatest competitive advantage.

  • Explicit Disclosure: Establishing clear guidelines for when and how you disclose the use of AI or synthetic enhancements. This builds trust by removing the “guessing game” for the user.
  • The Incident Response Playbook: Developing a specific protocol for responding to “synthetic attacks”—such as deepfakes of leadership or spoofed brand assets—ensuring your team can move from detection to debunking in minutes, not days.
  • Continuous Learning: Treating Truth Literacy as a living capability, with regular updates to training and technology as the AI landscape continues to evolve.

Conclusion: Leading with Integrity

As we look toward the horizon of the next decade, one thing is certain: technology will continue to accelerate our ability to create convincing illusions. However, while technology can verify data, only leaders can verify intent. In the end, Truth Literacy is not just a technical hurdle to clear—it is a human-centered commitment to the people we serve.

The Human Element in a Synthetic World

We must remember that every data point and every digital asset represents a touchpoint with a human being. When we invest in verification technology, we aren’t just protecting a file; we are protecting the sanctity of the human experience. As leaders, our role is to ensure that as our tools become more “agentic” and autonomous, they remain tethered to our core human values of honesty and transparency.

The Competitive Edge of the Authentic

The future belongs to the “Real.” In a marketplace flooded with infinite, low-cost fakes, authenticity becomes the ultimate luxury good and the most durable competitive advantage. The brands that win in 2026 and beyond will be those that can definitively prove their “realness.” By adopting the strategies of provenance, building a truth-literate culture, and leading with radical transparency, you aren’t just avoiding a crisis—you are capturing the highest possible market share of human trust.

Stay curious, stay skeptical where necessary, but above all, stay human. The architecture of the future is built on the foundations of truth we lay today.

Frequently Asked Questions

1. What is the fundamental difference between content provenance and deepfake detection?

Think of provenance as a digital birth certificate; it uses standards like C2PA to cryptographically prove where an asset came from and how it was edited. Detection, on the other hand, is like a digital polygraph; it uses AI to analyze existing content for “artifacts” or inconsistencies that suggest it was synthetically generated. Provenance focuses on proving the truth, while detection focuses on catching the lie.

2. Why is “Truth Literacy” considered a business imperative rather than just a technical skill?

In an era of “Experience Integrity,” a brand’s value is tied directly to its perceived authenticity. If a customer realizes they’ve been misled by an unverified synthetic interaction—what I call CX Betrayal—the trust is broken permanently. Truth Literacy ensures that leaders and teams can identify these risks, protecting the organization from reputational damage and legal liability.

3. How can an organization begin adopting C2PA standards today?

The first step is a Truth Surface Audit to identify where you create and distribute high-stakes content. From there, you should adopt tools from providers like Adobe or Microsoft that already support “Content Credentials.” By embedding these manifests into your assets at the point of creation, you ensure your official communications are “born authentic” and verifiable across the global digital ecosystem.

Disclaimer: This article speculates on the potential future applications of cutting-edge scientific research. While based on current scientific understanding, the practical realization of these concepts may vary in timeline and feasibility and are subject to ongoing research and development.

Image credits: ChatGPT

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

The Consumption Collapse – When the Feedback Loop Bites Back

Why the Great American Contraction is leading to a crisis of demand and a re-imagining of the American Social Contract.

LAST UPDATED: April 17, 2026 at 3:58 PM

The Consumption Collapse - When the Feedback Loop Bites Back

GUEST POST from Art Inteligencia


The Ghost in the Shopping Mall

In our previous exploration, “The Great American Contraction,” we identified a fundamental shift in the American story. For the first time in our history, the foundational assumption of “more” — more people, more labor, and more expansion — has been inverted. We discussed how the exponential rise of AI and robotics is dismantling the traditional value chain of human labor, moving us from a nation of “doers” to a necessary, albeit smaller, elite class of “architects.”

However, as we move closer to the two-year horizon of the next United States Presidential election, a more insidious shadow is beginning to fall across the landscape. It is no longer just a crisis of employment; it has evolved into a crisis of consumption. This is the “Feedback Loop of Irrelevance.”

The logic is as cold as the algorithms driving it: As increasing numbers of knowledge workers and service providers are displaced by autonomous agents, their disposable income evaporates. When people lose their financial footing, they spend less. When they spend less, the revenue of the very companies that automated them begins to shrink. To protect their margins in a declining market, these companies are forced to cut back even further — often doubling down on automation to reduce costs — which in turn removes more consumers from the marketplace.

We are witnessing the birth of a deflationary death spiral where corporate efficiency threatens to cannibalize the very markets it was designed to serve. Over the next 24 months, this cycle will redefine the American psyche and set the stage for an election year unlike any we have ever seen.

It is time to look beyond the immediate shock of job loss and examine the structural integrity of our economic operating system. If the “Old Equation” of labor-for-income is a sinking ship, we must decide what happens to the passengers before we reach the horizon of 2028.

The Vicious Cycle of Automated Austerity

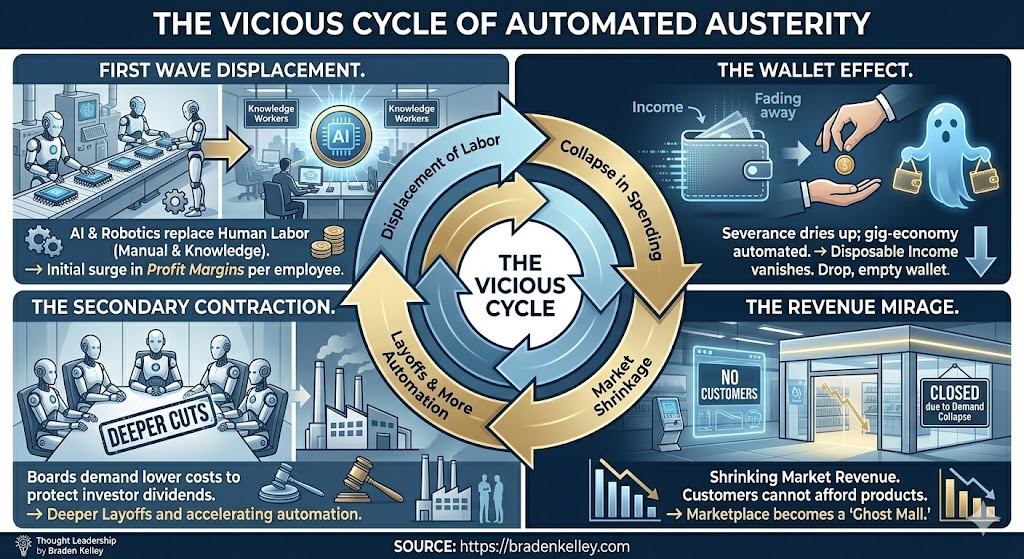
The transition from a growth-based economy to a Great Contraction is not a linear event; it is a recursive loop. As AI adoption accelerates, we are witnessing a phenomenon I call “Automated Austerity.” This is the process where short-term corporate gains from labor reduction lead directly to long-term market erosion. The cycle progresses through four distinct, overlapping phases:

Phase 1: The First Wave Displacement

We are currently seeing the replacement of both low-skilled physical labor and high-skilled knowledge work by autonomous systems. This isn’t just about factory floors; it’s about the “Architect” roles we once thought were safe. As companies replace $150k-a-year analysts with $15-a-month compute tokens, the immediate impact is a massive surge in corporate profit margins.

Phase 2: The Wallet Effect

The friction begins here. Displaced workers initially rely on savings or severance, but as those dry up, the “gig economy” safety net is nowhere to be found — because AI is already performing the freelance writing, coding, and administrative tasks that used to provide a bridge. Disposable income doesn’t just dip; for a significant percentage of the population, it vanishes. This causes a sharp contraction in discretionary spending.

Phase 3: The Revenue Mirage

This is the trap. Companies that automated to save money suddenly find their top-line revenue shrinking because their customers (the former workers) can no longer afford their products. The efficiency gains are real, but the market size is artificial. We are entering a period where companies may be 100% efficient at producing goods that 0% of the displaced population can buy.

Phase 4: The Secondary Contraction

Faced with shrinking revenues, boards of directors demand even deeper cost-cutting to protect investor dividends. This leads to a second, more desperate wave of layoffs, further reducing the tax base and consumer spending power. This feedback loop creates a Deflationary Death Spiral that traditional monetary policy is ill-equipped to handle.

“When you automate the consumer out of a job, you eventually automate the business out of a customer.” — Braden Kelley

Over the next two years, this cycle will move from the periphery of Silicon Valley to the heart of every American household, forcing a radical re-evaluation of how we distribute the abundance that AI creates.

Vicious Cycle of Automated Austerity

The Two-Year Horizon: 2026–2028

As we navigate the next twenty-four months, the gap between traditional economic indicators and the lived reality of American citizens will become a canyon. We are entering a period of Economic Bifurcation, where the distance between those who own the “compute” and those who formerly provided the “labor” creates a new social stratification.

The Rise of the ‘Hollow’ Recovery

Expect to hear the term “efficiency-led growth” frequently in the coming months. Wall Street may remain buoyant as AI-integrated corporations report record-breaking margins per employee. However, this is a hollow success. While the stock market reflects corporate optimization, our Alternative Economic Health Measures—like the Genuine Progress Indicator (GPI) — will likely show a steep decline. We are becoming a nation that is technically “wealthier” while the average citizen’s ability to participate in that wealth is structurally dismantled.

The Shift from ‘Doer’ to ‘Architect’ Burnout

The “Great American Contraction” is not just about those losing roles; it is about the immense pressure on those who remain. The survivors — the Architect Class — are tasked with managing sprawling AI ecosystems. This creates a new kind of cognitive load. By 2027, I predict we will see a peak in “Technological Burnout,” where the speed of AI-driven change outpaces the human capacity to design for it. This is where Human-Centered Innovation becomes a survival skill rather than a corporate luxury.

The Mindset of Survivalist Innovation

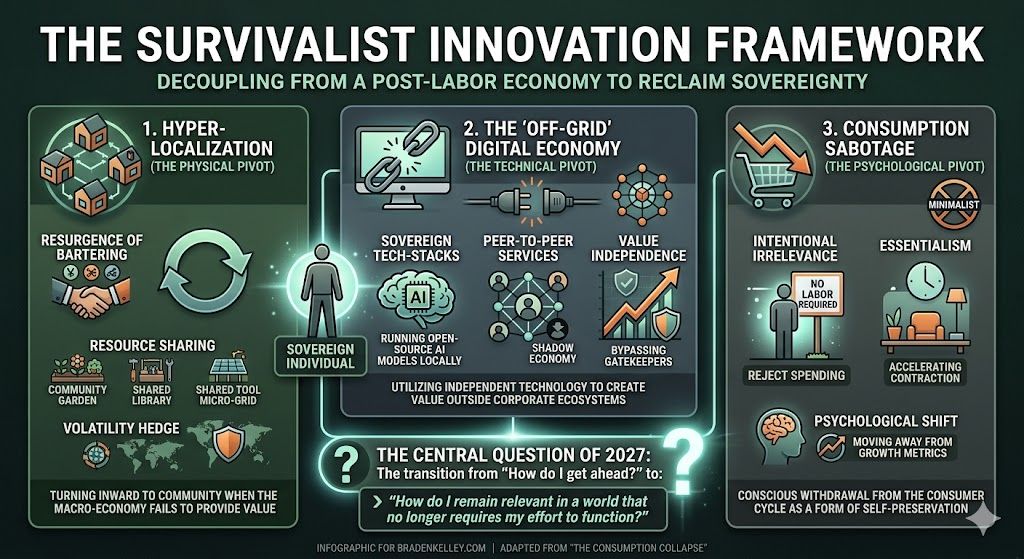
As the feedback loop of shrinking revenue intensifies, we will see American citizens taking radical actions to decouple from a failing labor market. This includes:

  • Hyper-Localization: A resurgence in local bartering and community-based resource sharing as a hedge against the volatility of the automated economy.
  • The ‘Off-Grid’ Digital Economy: Individuals utilizing open-source AI models to create value outside of the traditional corporate gatekeepers, leading to a “shadow economy” of peer-to-peer services.
  • Consumption Sabotage: A psychological shift where citizens, feeling irrelevant to the economy, consciously reduce their consumption to the bare essentials, further accelerating the contraction.

This period will be defined by a search for meaning in a post-labor world. The American citizen of 2027 is no longer asking “How do I get ahead?” but rather “How do I remain relevant in a world that no longer requires my effort to function?”

The Survivalist Innovation Framework

Beyond GDP: New Vitals for a Contracting Economy

As the “Old Equation” fails, the metrics we use to measure national success are becoming dangerously obsolete. In a world where AI can drive productivity while simultaneously hollowing out the consumer class, GDP is no longer a compass; it is a rearview mirror. To navigate the next two years, we must shift our focus to alternative economic health measures that prioritize human vitality over transactional velocity.

1. The Genuine Progress Indicator (GPI)

Unlike GDP, which counts the “cost of cleaning up a disaster” as a positive, the GPI factors in income inequality and the social costs of underemployment. As we move toward 2028, we must demand a GPI-centered view of the economy. If AI-driven efficiency creates wealth but destroys the social capital of our communities, the GPI will show we are regressing, providing a much-needed reality check to “hollow” stock market gains.

2. The U-7 ‘Utility’ Rate

Standard unemployment figures (U-3) are increasingly irrelevant. We need a U-7 ‘Utility’ Rate to track those who are “technologically displaced”—individuals whose roles have been absorbed by algorithms or whose wages have been suppressed to the point of working poverty. This metric will highlight the Architect Gap: the growing number of people who have the capacity for high-value human contribution but lack access to the compute resources required to compete.

3. The Social Progress Index (SPI)

The goal of an automated economy should be to improve the human condition. The SPI measures outcomes that actually matter: Access to advanced education, personal freedom, and environmental quality. By 2027, the SPI will be the most honest indicator of whether the Great Contraction is a managed transition to a better life or a chaotic collapse of the middle class.

4. Value of Organizational Learning Technologies (VOLT)

We must begin measuring the “Agility Score” of our nation. VOLT measures how effectively we are using AI to solve complex problems rather than just replacing workers. A high VOLT score paired with a low SPI suggests we are building a “learning machine” that has forgotten its purpose: to serve the humans who created it.

“A high-GDP nation with a crashing Social Progress Index(SPI) is merely a failed state in a gold tuxedo.”

The political battleground of the next two years will be defined by a new set of metrics similar to these (but likely different). The 2028 election will not just be a choice between candidates, but a choice between maintaining the illusion of growth or designing a system of sovereignty for the American citizen.

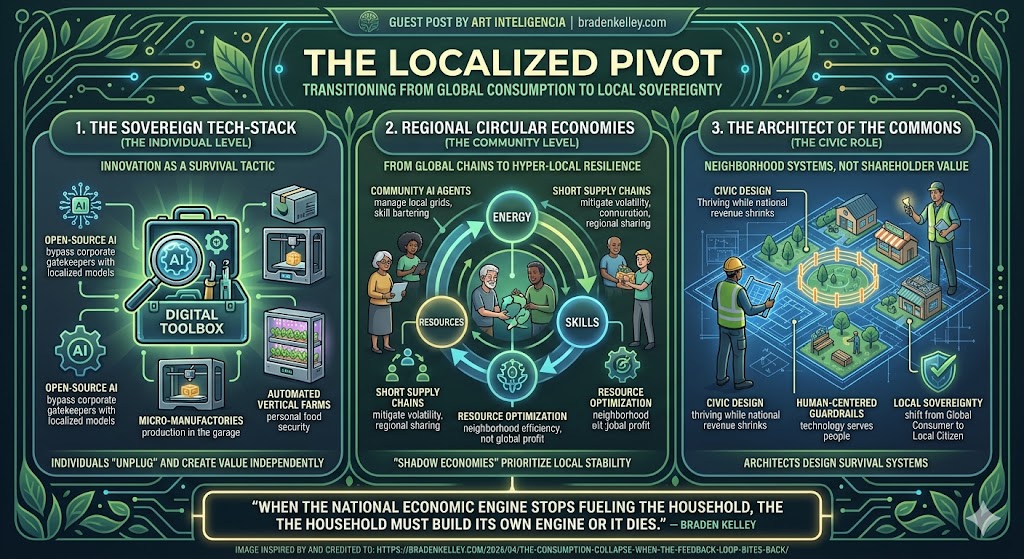
The Localized Pivot

The Sovereign Tech-Stack & The Localized Pivot

As the “Feedback Loop of Irrelevance” continues to shrink traditional income, we are witnessing a radical grassroots response: The Localized Pivot. When the macro-economy fails to provide value to the individual, the individual stops providing value to the macro-economy and turns inward to their community.

The Rise of the ‘Personal AI’ Infrastructure

By 2027, the barrier to entry for sophisticated production will vanish. We will see a surge in “Sovereign Tech-Stacks” — individuals and small collectives using localized, open-source AI models to run micro-manufactories, automated vertical farms, and peer-to-peer service networks. This is Innovation as a Survival Tactic. These citizens are essentially “unplugging” from the hollowed-out corporate ecosystem and creating a shadow economy that traditional GDP cannot track.

From Global Chains to Hyper-Local Resilience

The contraction of consumer spending will lead to the death of the “long supply chain” for many goods. In its place, we will see the rise of Regional Circular Economies. AI will be used not to maximize global profit, but to optimize local resource sharing. Imagine community AI agents that manage local energy grids or coordinate the bartering of skills — human-centered design at its most fundamental level.

The ‘Architect’ of the Commons

In this phase, the “Architect” role I’ve discussed previously becomes a civic one. These are the individuals who design the systems that keep their communities thriving while the national revenue shrinks. They are the ones building the Human-Centered Guardrails that ensure technology serves the neighborhood, not the shareholder. This shift represents a move from Global Consumerism to Local Sovereignty.

“When the national economic engine stops fueling the household, the household must build its own engine, or it dies.” — Braden Kelley

This localized movement will be the wild card of 2028. It creates a class of “Un-Architected” citizens who are no longer dependent on the federal government or major corporations, creating a profound tension for any political candidate trying to promise a return to the ‘Old Equation’.

The Road to 2028: The Politics of Human Relevance

As we approach the next Presidential election, the political discourse will undergo a seismic shift. The traditional “Left vs. Right” battle lines over tax rates and social issues will be superseded by a more existential debate: The Individual vs. The Algorithm. The 2028 election will likely be the first in history centered entirely on the consequences of a post-labor economy.

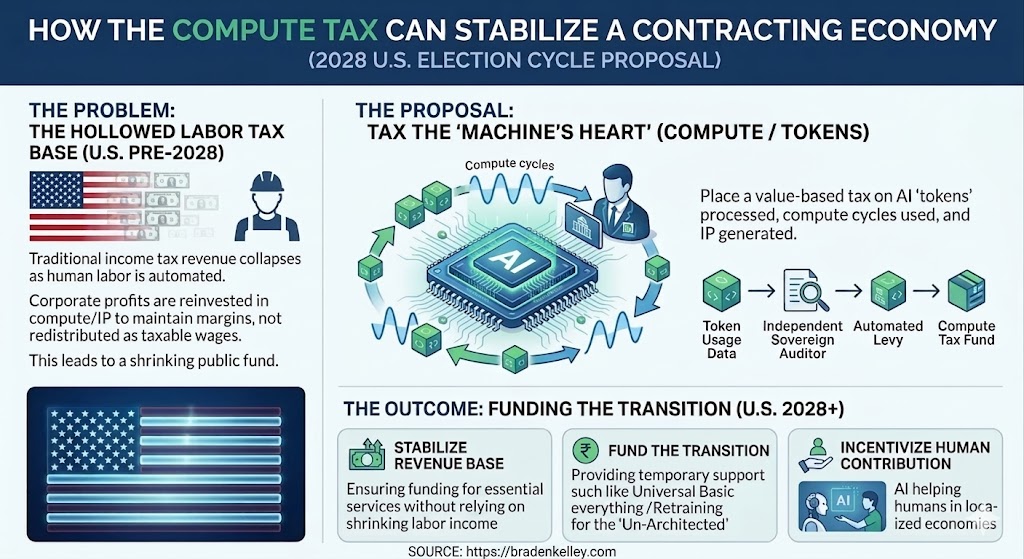
The ‘Humanity First’ Tax and Sovereign Solvency

The most contentious issue will be how to fund a shrinking state as the labor-based tax system collapses. We will see the rise of the “Compute Tax” — a proposal to tax AI tokens and robotic output rather than human hours. This isn’t just about revenue; it’s about sovereign solvency. When companies reinvest profits into compute rather than wages, the “Economic OS” crashes. Expect candidates to run on a platform of Universal Basic Everything (UBE) — providing the results of automation (healthcare, housing, and energy) directly to the people as the tax base from labor vanishes.

The Compute Tax

The Death of Traditional Immigration Debates

As I noted in our initial look at the Contraction, the old argument about immigrants “taking jobs” or “filling gaps” is dead. In 2028, the focus will shift to “Strategic Talent Acquisition.” The debate will center on how to attract the world’s few remaining irreplaceable “Architect” minds while managing a domestic population that is increasingly surplus to the needs of capital. This will create a strange political alliance between protectionists and humanists, both seeking to shield human value from digital devaluation.

Mindset and Likely Actions of the Citizenry

By the time voters head to the polls, the American mindset will have shifted from aspiration to preservation. We are likely to see:

  • The Rise of ‘Neo-Luddite’ Activism: Not a rejection of technology, but a demand for “Human-Centered Guardrails” that prevent AI from cannibalizing the last remaining sectors of human connection.
  • The Search for Non-Monetary Meaning: A surge in candidates who focus on “Quality of Life” metrics rather than fiscal growth, appealing to a class of people who no longer derive their identity from their “job.”
  • Algorithmic Populism: Politicians using AI to personalize fear and hope at scale, creating a feedback loop where the technology used to displace the worker is also used to win their vote.

The central question of the 2028 election will be simple but devastating: “What is a country for, if not to support the thriving of its people — even when those people are no longer ‘productive’ in a traditional sense?” The winner will be the one who can design a new social contract for a smaller, more resilient, and truly innovative nation.

Conclusion: Designing a Thrivable Contraction

The Great American Contraction is no longer a theoretical “what-if” for futurists to debate; it is an active restructuring of our reality. As the feedback loop of automated austerity begins to bite, we are discovering that a country built on the relentless pursuit of “more” is fundamentally ill-equipped to handle the arrival of “enough.”

The next two years will be a period of intense friction as our legacy systems — our tax codes, our education models, and our social safety nets — grind against the frictionless efficiency of the AI era. We will see traditional economic metrics fail to capture the quiet struggle of the consumer, and we will watch as the 2028 election turns into a referendum on the value of a human being in a post-labor world.

But contraction does not have to mean collapse. If we shift our focus from transactional velocity to human vitality, we have the opportunity to design a new version of the American Dream. This new dream isn’t about the quantity of jobs we can protect from the machines, but the quality of the lives we can build with the abundance those machines create. It is about moving from a nation of “doers” who are exhausted by the grind to a nation of “architects” who are inspired by the possible.

“The goal of innovation was never to replace the human; it was to release the human. We are finally being forced to decide what we want to be released to do.” — Braden Kelley

The road to 2028 will be defined by whether we choose to cling to the wreckage of the growth-based model or whether we have the courage to embrace a smaller, smarter, and more human-centered future. The contraction is inevitable, but the outcome is ours to design.

STAY TUNED: On Tuesday my friend Braden Kelley (with a little help from me) is publishing an article featuring one hypothesis for what an AI SOFT LANDING might look like.

Image credits: Google Gemini

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

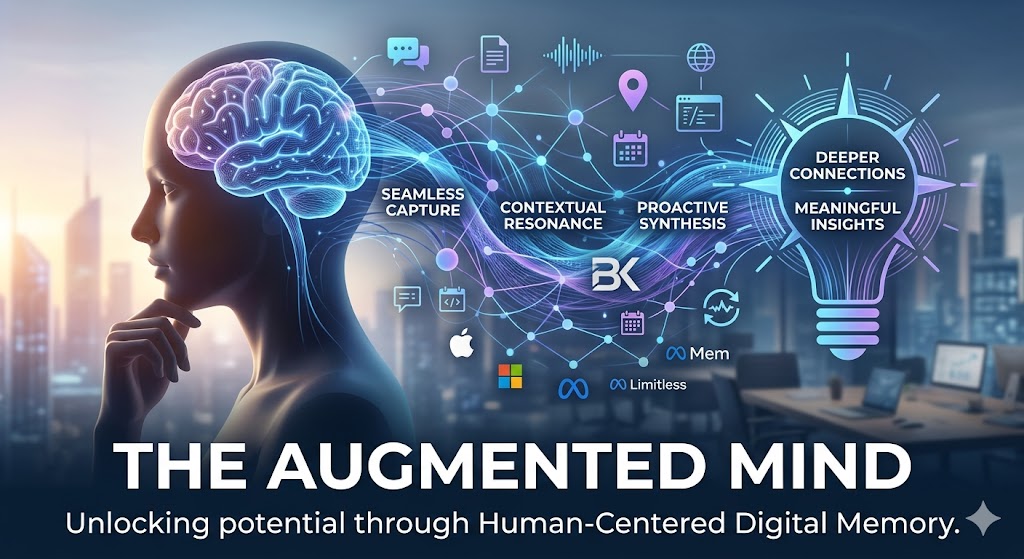
The Augmented Mind

Beyond Recall: The Strategic Evolution of Human Digital Memory

LAST UPDATED: April 10, 2026 at 3:39 PM

The Augmented Mind

GUEST POST from Art Inteligencia


The Dawn of the Extended Mind

For decades, we have treated our digital devices as external filing cabinets — places where we “put” information to be retrieved later. However, as the volume of data we consume shifts from a manageable stream to an overwhelming deluge, the traditional boundaries of the human mind are being tested. We are now entering a profound transition from Information Management to Cognitive Partnership.

The “Cognitive Crisis” is no longer a future threat; it is our current reality. Traditional search functions and folder-based storage hierarchies are failing the modern knowledge worker because they rely on perfect recall of where a file was placed or exact matching of keywords. When our biological hardware reaches its limit, our productivity and creativity suffer.

Digital Memory Augmentation represents a fundamental shift. It moves us beyond simple backups and toward active, AI-driven cognitive extensions. This isn’t about replacing human thought with an algorithm; it is a human-centered design opportunity to create a digital scaffold for our intellect. By augmenting our memory, we free the brain from the mundane task of storage, allowing it to return to its highest and best use: imagination, synthesis, and meaningful connection.

The Three Pillars of Augmented Memory

To move beyond simple storage and into true augmentation, we must look at how digital systems interface with our lived experience. This evolution is built upon three foundational pillars that transform raw data into a functional extension of our intellect.

1. Seamless Capture

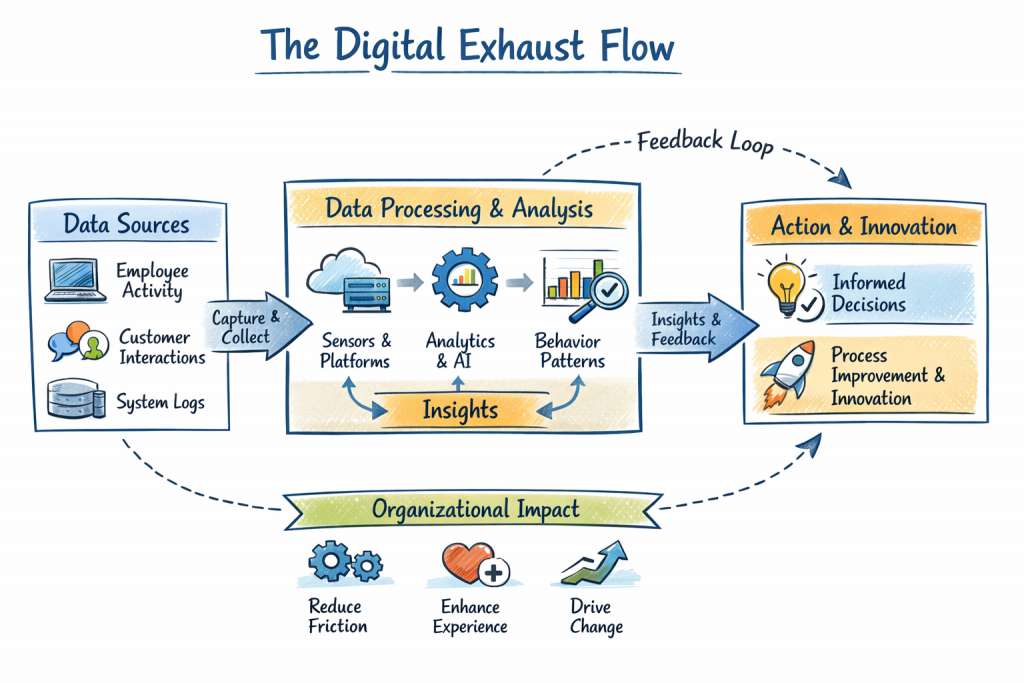
The greatest friction in traditional memory management is the act of “saving.” When we have to pause our flow to take a note, bookmark a page, or file a document, we break our cognitive momentum. Seamless Capture shifts the burden from the user to the environment. Through “digital exhaust” — the ambient collection of our meetings, readings, and interactions — augmentation systems ensure that the “sparks” of insight are never lost simply because we were too busy to write them down.

2. Contextual Resonance

A memory is useless if it exists in a vacuum. Traditional systems rely on folders or tags, which require us to remember how we categorized information in the past. Contextual Resonance uses semantic analysis to understand the “why” and “how” behind a piece of information. By linking a data point to a specific project, a person, or even an emotional state, the system mimics the associative nature of the human brain, making retrieval feel like a natural thought rather than a database query.

3. Proactive Synthesis

The ultimate goal of augmentation is to move from reactive searching to proactive assistance. Proactive Synthesis is the stage where the system acts as a true partner. Instead of waiting for a prompt, the “Second Brain” identifies patterns across years of data and surfaces relevant insights at the moment they are most useful. It creates “digital serendipity,” connecting a conversation you had this morning with a research paper you read three years ago, fueling innovation through automated cross-pollination.

Reimagining the Innovation Lifecycle

Innovation is rarely the result of a single “Eureka!” moment; it is a cumulative process of gathering sparks, connecting dots, and refining concepts over time. By integrating digital memory augmentation, we transform the innovation lifecycle from a fragile, hit-or-miss endeavor into a robust, high-velocity engine for growth.

1. The End of “Lost Ideas”

How many breakthrough concepts have been lost to the ether simply because they occurred in the shower, during a commute, or in the middle of a casual conversation? Memory augmentation ensures that the “sparks” — the messy, early-stage thoughts and sketches — are captured in real-time. By removing the friction of documentation, we preserve the raw materials of innovation before they can be overwritten by the next urgent task.

2. Cross-Pollination at Scale

The most powerful innovations often come from combining ideas from two completely unrelated fields. However, our biological memory is prone to “siloing” information by department or project. A digital memory layer can scan across decades of organizational history and disparate personal interests to find hidden links. It allows an engineer to see how a solution from a 2015 project might solve a 2026 problem, facilitating a level of cross-pollination that was previously impossible for a single human mind to manage.

3. Accelerating Mastery

In a world of hyper-specialization, the “time-to-expertise” is a major bottleneck for innovation. Memory augmentation acts as a cognitive scaffold, allowing individuals to rapidly navigate complex institutional knowledge and technical documentation. By having a “Second Brain” that remembers the technical nuances and past failures of a specific domain, innovators can stand on the shoulders of their own past experiences (and those of their predecessors) much faster, shifting their energy from learning the foundation to building the future.

Designing for Trust and Human Agency

As we integrate digital memory more deeply into our lives, the design challenge shifts from technical feasibility to ethical responsibility. If we are to treat a digital system as an extension of our own mind, that system must be designed with an uncompromising focus on the user’s autonomy, privacy, and long-term cognitive health.

1. The Privacy Imperative

For digital memory augmentation to be successful, the “Second Brain” must be a private sanctuary. Users will only record their raw thoughts, private conversations, and vulnerable moments if they have absolute certainty that their data is not being used for advertising or surveillance. Designing for trust means prioritizing on-device processing and end-to-end encryption — ensuring that the user remains the sole owner and curator of their digital history.

2. Combatting Cognitive Atrophy

A significant concern with augmentation is the risk of “cognitive laziness.” Just as GPS has weakened our innate sense of navigation, there is a risk that total recall tools could weaken our ability to focus or synthesize information independently. Human-centered design must focus on augmentation, not replacement. The goal is to build tools that act as a “cognitive bicycle” — strengthening our ability to connect ideas and think critically by offloading the low-value task of rote memorization.

3. The Ethics of Perfection

Human memory is naturally fallible; we forget, we forgive, and we move on. A world where every mistake, every awkward comment, and every outdated opinion is preserved with photographic clarity presents a psychological challenge. We must design systems that allow for the “right to be forgotten” and the ability to prune our digital archives. True augmentation should support the human capacity for growth and evolution, rather than chaining us to a static version of our past selves.

The Ecosystem: Titans and Trailblazers

The landscape of memory augmentation is currently a race between established tech giants integrating AI into our daily operating systems and agile startups building dedicated hardware for total recall. By 2026, the market has moved beyond experimental prototypes to functional, cross-platform tools that are reshaping how we interact with our own history.

1. Established Platforms

  • Apple (Apple Intelligence): Apple has positioned itself as the “Privacy-First” memory partner. By leveraging on-device processing and Private Cloud Compute, iOS 26 and macOS Sequoia allow users to search for specific moments across photos, emails, and notes using natural language — creating “Memory Movies” and surfacing context-aware suggestions without ever exposing raw data to the cloud.
  • Microsoft (Windows Recall & Copilot): Despite early privacy hurdles, Microsoft has refined “Recall” into a sophisticated enterprise tool. It creates a searchable photographic timeline of everything you’ve seen and done on your PC, allowing professionals to instantly jump back to a specific slide, website, or conversation from weeks prior.
  • Meta (Ray-Ban Meta & AI): Meta is utilizing hardware to move memory augmentation into the physical world. Their smart glasses act as ambient “eyes and ears,” allowing users to ask, “Hey Meta, what was the name of that restaurant I walked past yesterday?” or “What did my colleague say about the project deadline?”

2. Disruptive Startups

  • Limitless (The Pendant): Limitless has become the go-to for “Total Recall” hardware. Their wearable AI pendant records and transcribes in-person meetings and impromptu conversations, utilizing “Automatic Speaker Recognition” to create smart summaries and reminders that sync across all productivity suites.
  • Mem.ai: Moving beyond traditional note-taking, Mem 2.0 has evolved into an “AI Thought Partner.” It eliminates the need for folders by using a self-organizing knowledge graph that automatically links new thoughts to past research, surfacing relevant context as you type.
  • Heirloom (Heirloom.cloud): Focused on the bridge between analog and digital, Heirloom uses AI to digitize, contextualize, and narrate family histories and personal archives, ensuring that legacy memories remain searchable and meaningful for future generations.
  • The Neural Frontier (Neuralink & Synchron): While still largely focused on clinical applications for motor and speech restoration, the successful 2025-2026 human trials for Brain-Computer Interfaces (BCIs) have laid the groundwork for future direct-to-brain memory retrieval and cognitive offloading.

Case Studies: Augmentation in the Real World

To move from the theoretical to the practical, we must look at how digital memory augmentation is already solving deep-seated organizational and individual challenges. These two case studies illustrate how extending our cognitive capacity directly translates into business value and human safety.

Case Study 1: Resolving the “Institutional Memory” Gap in Professional Services

The Challenge: A global management consulting firm was suffering from “reinventing the wheel.” With over 10,000 consultants globally, teams were frequently spending hundreds of hours on research and analysis that had already been performed by colleagues in different regions or years prior. Internal surveys showed that senior partners were spending 25% of their time simply trying to remember who had the specific “tribal knowledge” needed for a new pitch.

The Approach: The firm implemented a semantic memory layer that indexed all past white papers, anonymized project summaries, internal Slack discussions, and recorded client debriefs. Unlike a traditional database, this system used a “Second Brain” interface that allowed consultants to ask conversational questions like, “What were the specific regulatory hurdles we faced during the 2022 retail merger in Singapore?”

The Result: Within the first twelve months, the firm reported a 35% increase in project velocity and a significant reduction in duplicate research costs. More importantly, the ability to surface “deep-context” insights during client meetings led to a 15% higher win rate on new business pitches.

Case Study 2: Adaptive Learning and Safety in Complex Engineering

The Challenge: An aerospace manufacturing leader faced a massive demographic shift. As their most experienced engineers reached retirement age, they were struggling to transfer decades of “feel” and undocumented maintenance nuances to junior engineers working on legacy aircraft systems — some of which were designed 40 years ago.

The Approach: The company deployed a wearable AR-and-memory system. As a junior engineer looked at a specific engine component, the system utilized computer vision to recognize the part and instantly surfaced the “ambient memory” associated with it: past repair notes from retired masters, video snippets of successful fixes, and warnings about specific bolt-tension issues that weren’t in the official manual.

The Result: The facility saw a 50% reduction in error rates during complex maintenance cycles. The “time-to-expertise” for new hires was cut by four months, as their digital memory augmentation acted as an on-demand mentor, bridging the gap between theoretical training and institutional wisdom.

Conclusion: The Future of Being Human

We are standing at a pivotal crossroads in our evolution as a species. Digital memory augmentation is not merely a technological upgrade; it is a shift in the very nature of human cognition. As we move from a world of “Search” to a world of “Knowing,” we must be intentional about how we design these systems and what we choose to do with our newly reclaimed mental energy.

1. From “Search” to “Knowing”

When the friction of retrieval disappears, our relationship with knowledge changes. We no longer have to wonder if we know something; we simply have access to it. This transition allows us to shift our focus from the logistics of information management to the higher-level pursuit of empathy and understanding. When we are not struggling to remember the facts, we have more capacity to listen to the story, to understand the nuance, and to build deeper connections with those around us.

2. The Human-First Mandate

As a thought leader in human-centered innovation, my message is clear: Technology should never outpace our humanity. While we build smarter memories and more powerful cognitive scaffolds, we must ensure we don’t lose the “wisdom” that comes from human reflection, the growth that comes from our mistakes, and the beauty of our fallibility. Our goal should be to use digital memory to amplify our potential — not to automate our souls.

The future of being human is not about being “replaced” by silicon; it is about being empowered by it to reach new heights of creativity and compassion. Let us design for that future today.

Key Insight: Digital memory augmentation isn’t about building a better hard drive; it’s about building a better bridge between what we experience and what we can achieve.

Frequently Asked Questions

1. What is Digital Memory Augmentation?

It is the use of AI-driven tools and hardware to seamlessly capture, organize, and surface personal and professional information, acting as a “second brain” to extend human cognitive capacity.

2. How does memory augmentation impact privacy?

Privacy is the core pillar of these systems. Modern solutions prioritize on-device processing and end-to-end encryption to ensure that the user remains the sole owner of their digital history.

3. Does using a “Second Brain” lead to cognitive atrophy?

When designed correctly, these tools act as a “cognitive bicycle” — offloading the low-value task of rote memorization so the human brain can focus on higher-level creativity and complex problem-solving.

Disclaimer: This article speculates on the potential future applications of cutting-edge scientific research. While based on current scientific understanding, the practical realization of these concepts may vary in timeline and feasibility and are subject to ongoing research and development.

Image credits: ChatGPT

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

6 Trust Pillars for Agentic Customer Experience

6 Trust Pillars for Agentic Customer Experience

by Braden Kelley and Art Inteligencia


What Are the Trust Pillars for Agentic CX? (Short Answer)

Six trust pillars for agentic customer experience: (1) Clarity, (2) Competence, (3) Control, (4) Care, (5) Consent, and (6) Accountability. Agents that act — refund, rebook, route, negotiate, commit — change the trust contract. Containment, deflection, and “the model said so” are not design. Soft landings design all six before scale.

Agentic CX earns trust when customers can see the actor, finish the job, stay in control, feel cared for, consent to the scope of action, and still find a human accountable when the agent gets it wrong.

Why Six Pillars — Not Only Automation Metrics?

I keep watching teams ship agentic power as if a smarter FAQ were enough. It isn’t. Agentic CX is delegated action. Customers will forgive imperfect speed. They will not forgive betrayal — opacity, trapped loops, brand-first optimization, no undo, and nobody who can be asked why.

The original four — Clarity, Competence, Control, Care — still hold. I unpacked that contract in When AI Agents Act on Your Behalf. Two pillars complete it when authority is real: Consent (what they authorized the agent to do) and Accountability (who owns recovery when it fails). Autonomy without those six is a hard landing with a better chatbot costume.

For the broader product lens beyond agents, see 11 Principles for Designing Trust (Not Just Usability). For how leaders must own agentic scenarios across the enterprise, see 5 Scenarios for Agentic Organizations.

Pillar Customer question Hard landing tell
1. Clarity Who is acting and what can it do? “Wait — was that a bot?” after damage
2. Competence Will this finish without making me restart? Loops; retelling tax
3. Control Can I stop, undo, or reach a human? Trapped; punished for escalating
4. Care Is this for me or for containment? Cheap resolution that costs dignity
5. Consent Did I authorize this scope of action? Surprises in money, data, commitments
6. Accountability Who owns this when it fails? “The system decided”; no recovery power

Ship the agent’s power only as fast as you can design these six.

1. What Is Clarity in Agentic Customer Experience?

Pillar: Make the actor, scope, and limits visible — human, system, or agent — before and during action.

When agents act: Customers must know they are delegating, not chatting with a FAQ costume.

Hard landing: Hidden automation; surprise commitments; “Was that a bot?” after the charge.

Soft-landing move: Disclose identity, capabilities, and boundaries in the channel; update when scope expands.

Tell: Post-action confusion; chargebacks; “I didn’t know it could do that.”

2. What Is Competence When Agents Act?

Pillar: Resolve completely across steps; carry memory; don’t loop people through the same dead end.

When agents act: Multi-step work is the product — not a clever first reply.

Hard landing: Partial completion; lost context; restart tax; endless clarification.

Soft-landing move: End-to-end completion metrics; context that travels; escalate before the third loop.

Tell: Repeat contacts; “I already told you”; high containment, low resolution. Efficient misery often starts here — see 8 Service Design Mistakes That Create Efficient Misery.

3. Why Does Control Matter More When Agents Have Authority?

Pillar: Real agency includes pause, reverse, override, and human help without punishment.

When agents act: Authority without an exit is coercion with better UX.

Hard landing: No undo on money or data moves; escalation buried; AHT and containment punish the handoff.

Soft-landing move: One-tap stop/undo for high-stakes actions; a human path with teeth; a dual scorecard so green containment cannot close a red trust review.

Tell: Customers force a channel-switch to escape the agent; human agents inherit angry cleanup.

4. What Does Care Mean for Agentic CX?

Pillar: At the decision point, design for the customer’s job and dignity — not only conversion, deflection, or cost.

When agents act: The agent’s objective function is the brand promise in motion.

Hard landing: Containment KPIs; upsell in distress; “resolved” tickets that leave the job unfinished.

Soft-landing move: Objective functions and policies that prefer make-right over cheap close; care metrics beside automation rate.

Tell: High script scores, low loyalty; viral “the bot wouldn’t help” stories. Soft landings split human and machine work on purpose — see The AI Soft Landing.

6. What Is Accountability When the Agent Gets It Wrong?

Pillar: A named human (or role) and a powered recovery path when the agent errs — explainability plus make-right, not a shrug.

When agents act: “The system decided” is not a brand. Someone must still be askable.

Hard landing: Unowned model choices; recovery as exception hell; liability parked on the customer.

Soft-landing move: Named accountable owner per journey; recovery journeys equal to the primary flow; explain why in plain language; log decisions for appeal.

Tell: No one to escalate to; make-right requires a second odyssey; trust dies at the seam.

What Should You Ask Before Scaling Agentic CX?

Six questions before the next agentic CX release:

  1. Is the actor and scope clear?
  2. Can the median journey finish without a loop trap?
  3. Can the customer stop, undo, and reach a human without punishment?
  4. Does the objective function optimize for their interest?
  5. Was consent earned for this band of action?
  6. Who owns recovery — with power — when it fails?

Mantra: Don’t scale the agent’s authority faster than you can design Clarity, Competence, Control, Care, Consent, and Accountability.

FAQ: Trust Pillars for Agentic Customer Experience

What are the trust pillars for agentic CX?

The six trust pillars for agentic CX are Clarity, Competence, Control, Care, Consent, and Accountability — the contract customers need when AI agents act on their behalf, not only chat.

How do you design trust for AI agents?

Design trust for AI agents by disclosing who is acting and what they can do, finishing jobs with context, giving stop/undo/human paths, optimizing for the customer’s interest, earning consent for the scope of action, and naming who owns powered recovery when the agent fails.

What is consent in agentic customer experience?

Consent in agentic customer experience is explicit, reversible permission for what the agent may do with money, data, identity, and commitments — matched to stakes — not a buried default that expands the agent’s authority without the customer knowing.

Why isn’t automation enough for CX trust?

Automation is not enough for CX trust because agentic systems take actions that can help or harm. Speed and containment without clarity, control, care, consent, and accountability feel like betrayal — and customers forgive friction more readily than betrayal.

How do you measure agentic CX trust?

Measure agentic CX trust with completion without loops, undo and human-reach success, consent revoke rates, recovery time and power after agent error, and whether customers understood who acted — not automation or containment rate alone.

Image credits: Pixabay

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

8 Moments That Matter More Than Your NPS Dashboard

8 Moments That Matter More Than Your NPS Dashboard

by Braden Kelley and Art Inteligencia


Which Moments Matter More Than Your NPS Dashboard? (Short Answer)

Eight moments that matter more than your NPS dashboard: (1) the first struggling moment, (2) the status-less wait, (3) the seam / retelling moment, (4) the recovery moment, (5) time-to-confidence, (6) the powerless frontline moment, (7) the policy surprise after “done,” and (8) the quiet exit. NPS can pulse loyalty intent. These moments decide whether humans succeed, escalate, or leave — often before a survey fires.

A dashboard asks whether they would recommend you. Moments that matter ask what happened when it counted — and whether anyone was designed to make it right.

Why Isn’t the NPS Snapshot the Whole CX Story?

I have sat in CX reviews where the NPS slide got twenty minutes and the human story got two. The score was up a point. Nobody could name the wait that made someone quit checking the portal, the handoff that forced a third retelling, or the agent who knew the fix and was not allowed to deliver it.

NPS can be a useful pulse. It becomes a hazard when the dashboard is the product and the moments that actually decide loyalty never get owners, metrics, or redesign. Soft landings for customers require governing the heat — not only harvesting a score after the fact.

Moment Why NPS misses it Design instead
1. First struggling moment Surveys fire after calm, not at the spike Own first fail; time-to-unstuck
2. Status-less wait SLA-fine can still feel opaque Status as experience; escape hatch
3. Seam / retelling Channel scores; no handoff owner Seam owners; context that travels
4. Recovery Later recommend cannot reconstruct teeth Recovery as a product; make-right power
5. Time-to-confidence Promoters may be survivors First real success without heroics
6. Powerless frontline Survey rarely asks if help was allowed Decision rights; dual scorecard
7. Policy surprise Cliff after score timing — or no ask Constraint honesty; promise-break rate
8. Quiet exit Silent churn never enters the dashboard Leading behaviors; exit archaeology

1. Why Does the First Struggling Moment Matter More Than the Score?

The moment: The first time the human cannot finish alone — wrong door, unclear next step, life context the happy path ignored.

Why NPS misses it: Surveys often fire after a “resolved” ticket or a calm purchase — not at the spike of struggle.

Humans feel: Anxiety, homework, shame for “not getting it.”

Instead: Instrument and own the first fail point. Measure time-to-unstuck and wrong-door rate — not only post-contact scores.

2. How Does a Status-Less Wait Decide Loyalty Before NPS Does?

The moment: Waiting without knowing how long, why, or what happens next.

Why NPS misses it: Wait time may be “within SLA” while emotional residue is rage or abandonment.

Humans feel: Helplessness. Checking apps becomes a second job.

Instead: Design status as experience — progress, ETA honesty, and a human escape hatch. Measure opacity, not only queue seconds.

3. Why Does the Seam / Retelling Moment Matter More Than Channel NPS?

The moment: Explaining the story again across bot → agent → specialist → portal.

Why NPS misses it: Channel scores can look fine; the handoff has no owner and no survey timing.

Humans feel: The retelling tax. “Nobody talks to each other.”

Instead: Journey and seam owners. Context that travels. Measure repeat-explain rate. For frictions maps miss at those cliffs, see 12 Friction Points Customers Feel Before Your Journey Map Does.

4. How Does the Recovery Moment Win or Spend Trust?

The moment: Something broke — and either someone makes it right with power, or the brand spends apology theater.

Why NPS misses it: A later “how likely to recommend” cannot reconstruct whether recovery had teeth.

Humans feel: Dignity restored — or dignity billed.

Instead: Design recovery as a product. Measure first-contact make-right and recovery power used — not only detractor callbacks closed.

5. Why Does Time-to-Confidence Matter More Than Relationship NPS?

The moment: The first time the median person completes the job and trusts the next step — onboarding, setup, first value.

Why NPS misses it: Relationship NPS can be high while new users still thrash. Promoters may be survivors.

Humans feel: Relief — or chronic doubt.

Instead: Measure time-to-confidence and abandoned-setup rate. Fund enablement as design, not a FAQ dump.

6. Why Does the Powerless Frontline Moment Matter More Than the Dashboard?

The moment: The employee closest to the customer knows the right fix and is blocked by script, metric, or approval theater.

Why NPS misses it: The survey rarely asks whether the human who could help was allowed to.

Humans feel: Customers escalate to survive. Agents quit the dignity of the job.

Instead: Design decision rights into the moment. Dual scorecard so green handle time cannot veto red human success. For the rulebook, see 10 Agent Empowerment Rules Your Customer Deserves Before They Quit.

7. How Does a Policy Surprise After “Done” Outrank a Green Score?

The moment: Denial, fee, eligibility, or constraint appears after the experience felt finished.

Why NPS misses it: Timing is wrong; the score may already be collected — or never asked at the cliff.

Humans feel: Bait-and-switch. Betrayal of the brand promise.

Instead: Constraint honesty in design. Measure surprise-denial and promise-break rates. Bring policy into the journey as a stage, not a footnote.

8. Why Does the Quiet Exit Matter More Than a Stable NPS?

The moment: The final unpaid labor, unanswered status, or dignity cost that tips someone out — often with no survey and no complaint ticket.

Why NPS misses it: Non-respondents and silent churn never enter the dashboard leaders manage.

Humans feel: “Not worth it” — then they are gone.

Instead: Watch leading behaviors — repeat contact, unfinished jobs, help-seeking spikes — and exit archaeology. Do not confuse a stable NPS with a loyal base. When surveys thin, listen in the moment with Conversational and Agentic VoC. If the program is managing the number instead of the journey, use 11 Signs Your CX Program Is Scorekeeping, Not Sense-Making.

How Do You Put Moments Over the NPS Scoreboard in the Next CX Review?

Before the next CX review, run five go/no-go questions:

  1. Which moment owns the agenda — a score or a lived beat?
  2. Who owns the hottest seam?
  3. What recovery power exists when it breaks?
  4. What is time-to-confidence on the journey that funds growth?
  5. Which quiet-exit signals are we ignoring because the dashboard is green?

Let NPS pulse. Let moments lead. Loyalty is decided in the heat — not in the harvest.

Frequently Asked Questions

What moments matter more than NPS?

Moments that matter more than NPS include the first struggling moment, status-less waits, seam/retelling handoffs, recovery with or without power, time-to-confidence, powerless frontline moments, policy surprises after “done,” and quiet exits that never enter the survey. These lived beats decide success, escalation, and churn — often before a score is collected.

Why is NPS not enough for CX?

NPS is not enough for CX because it is a pulse of recommend intent, not a map of what happened when it counted. It often misses struggle spikes, opaque waits, orphan seams, recovery teeth, first confidence, blocked agents, policy cliffs, and silent churn — especially when non-respondents never enter the dashboard.

What are moments that matter in customer experience?

Moments that matter in customer experience are the high-stakes beats where humans succeed or fail with dignity — first struggle, waiting without status, retelling across seams, recovery, first real confidence, frontline power (or its absence), policy surprises, and the quiet exit. They deserve owners, design, and measures — not only a post-hoc score.

How do you measure moments that matter?

Measure moments that matter with behavior and outcome metrics tied to each beat: time-to-unstuck, wait opacity, repeat-explain rate, first-contact make-right, time-to-confidence, recovery power used, surprise-denial rate, and leading exit signals — then use NPS as a pulse, not the agenda.

When should you look past the NPS dashboard?

Look past the NPS dashboard when the score is green but journeys fail, when surveys miss the hot moment, when channel scores hide orphan seams, when recovery has no teeth, when new users thrash despite promoters, when agents cannot help, when policy surprises after “done,” or when silent churn never appears in the harvest.

Image credits: Pixabay

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

5 Stages from SLAs to XLAs (A CX Maturity Roundup)

5 Stages from SLAs to XLAs (A CX Maturity Roundup)

by Braden Kelley and Art Inteligencia


What Are the Five Stages from SLAs to XLAs? (Short Answer)

Five CX maturity stages from SLAs to XLAs: (1) SLA Default — green metrics, miserable humans; (2) Experience Sensing — listening without power; (3) XLM Definition — human success becomes measurable; (4) XLA Adoption — experience becomes a commitment; (5) Experience-Led Management — XLAs steer, SLAs enable. An SLA (Service Level Agreement) tells you the service ran. An XLM (Experience Level Measure) tells you whether humans succeeded. An XLA (Experience Level Agreement) is how you promise and manage that success.

CX maturity is not “more surveys.” It is whether human success can change a budget meeting. Mature organizations rarely delete SLAs — they demote them from the steering wheel to the dashboard lights.

Why Do Green Dashboards Hide Red Tuesdays?

I have lost count of how many “healthy” service reviews I have sat through where every SLA was green and every human in the room was exhausted.

The portal was up. The tickets closed. The vendor collected their availability credit theater. And somehow employees still needed three workarounds to finish one task, customers still repeated their story to four people, and leaders still wondered why loyalty and productivity refused to follow the scorecard.

That is not a tooling failure. It is a maturity failure. Organizations learn to manage what they can defend in a contract — uptime, response, resolution — and then mistake green for good. Cold metrics create warm fiction.

This roundup is the map: five stages from steering by SLA to managing by human success. Each stage has a trap, an exit signal, and a different Tuesday when you climb.

Stage Managing by… Trap Exit signal
1. SLA Default SLAs and SLA-like KPIs Optimizing the metric, not the human Admit green ≠ good; structured listening on one journey
2. Experience Sensing SLAs + ad hoc listening Listening theater — dashboards, same decisions Defined XLMs with owners and baseline
3. XLM Definition SLAs + human-success measures Too many XLMs; “experience = speed” XLA language with targets and cadence
4. XLA Adoption SLAs and experience commitments Paper XLAs — no funding or teeth Portfolio led by XLA/XLM outcomes
5. Experience-Led Management XLAs first, SLAs as enablers Stage 5 in town hall, Stage 1 in payroll Red XLA stops a green review

1. What Is Stage 1 — SLA Default?

The stage: Service performance is managed through SLAs (or SLA-like KPIs), often inconsistently across teams and vendors. Experience shows up as complaints, escalations, or heroic recoveries — not as a managed system.

Primary question: Did we meet the technical target?

The trap: Optimizing the metric — faster closes, defensive ticket hygiene, throughput over outcome — instead of the human result.

Exit signal: Leaders admit SLA-green ≠ experience-good, and begin structured listening beyond tickets for at least one critical journey.

On Tuesday: Employees and customers can be miserable while every SLA is green. Cold metrics, warm fiction.

2. What Is Stage 2 — Experience Sensing?

The stage: SLAs still run the operating rhythm. Beside them appears experience signal: surveys, VoC, shadowing, journey maps, advisory boards. Insight exists; it is not yet designed into commitments or tradeoff decisions.

Primary question: What are people feeling, and where does it hurt?

The trap: Listening theater — more dashboards, same decisions. Frontline cynicism grows: “we surveyed again.” Sensing without power to act is worse than not listening.

Exit signal: For a priority journey, a small set of XLMs tied to human success — effort, confidence, agency — with owners and a baseline.

On Tuesday: Frontline staff often know the truth first. The organization hears pain; it does not yet manage by it. For scorekeeping disguised as CX, see 11 Signs Your CX Program Is Scorekeeping, Not Sense-Making.

3. What Is Stage 3 — XLM Definition?

The stage: The organization deliberately designs Experience Level Measures — translating friction into measurable human outcomes. XLMs sit beside SLAs: task effort, time-to-confidence, sense of agency, repeat contact for the same intent, EX enablement to deliver CX. Not SLAs renamed.

Primary question: Which human outcomes must improve for this journey to count as successful?

The trap: Too many XLMs; or “experience = speed” — SLAs in disguise. A metric that only celebrates faster failure is still cold.

Exit signal: Stakeholders agree to XLA language — targets, review cadence, consequences — for at least one service, vendor, or internal shared service.

On Tuesday: Teams can finally argue for fixes that do not move an SLA but remove massive human struggle. Human success becomes a number you can improve — and defend.

4. What Is Stage 4 — XLA Adoption?

The stage: Experience Level Agreements sit beside SLAs. A dual scorecard: SLA health and XLA attainment. Joint reviews; XLAs in charters or SOWs; escalation when XLMs breach even if SLAs pass.

Primary question: Did we keep our promise about how this should feel and work for humans — not only whether the system was up?

The trap: Paper XLAs — beautiful agreements with no funding, no decision rights, no repair paths at the moment of truth.

Exit signal: Portfolio priorities and vendor tradeoffs begin led by XLA/XLM outcomes. SLAs remain hard constraints but are no longer the primary definition of success.

On Tuesday: Authority starts matching empathy. Recovery power is designed into the system — not left as an accident of character on the front line.

5. What Is Stage 5 — Experience-Led Management?

The stage: The organization manages by XLAs first. Reliability is table stakes. Human success is how strategy, funding, and continuous improvement are judged. Innovation is evaluated on XLM lift, not demo applause.

Primary question: Where is human success leaking — and what will we stop, start, or redesign to recover it?

The trap: Declaring Stage 5 in a town hall while Stage 1 incentives still run payroll and promotions.

Signs you are actually here: A green SLA cannot close an executive review if the XLA is red. Vendors are retained or exited on experience outcomes, not only uptime credits. Journey owners can fund repairs that improve XLMs without waiting for an outage.

On Tuesday: People stop choosing between “hit the SLA” and “do right by the human.” The system expects both — and funds the second.

How Do You Check CX Maturity Before the Next Review?

Before the next service or CX review, run five honest questions. If you cannot answer them, you are reporting maturity you have not earned:

  1. Are we steering by SLA or by human success? — Who owns the experience outcome, not only the uptime number?
  2. Is listening changing decisions — or decorating decks?
  3. Do we have XLMs we would defend in a budget fight? — Not vanity scores; human outcomes with baselines.
  4. Do XLAs have owners, cadence, and teeth? — Or paper promises?
  5. Would a red XLA stop a green review? — If not, you are still in Stage 1 with better graphics.

One-journey climb (without boiling the ocean):

  1. Pick one critical journey.
  2. Keep SLAs as reliability rails.
  3. Define 3–5 XLMs that measure human success on that journey.
  4. Baseline current performance.
  5. Commit — turn XLMs into an XLA with owners and cadence.
  6. Rewire escalations so red XLAs trigger action as reliably as red SLAs — then scale.

For the full framework — stuck points, governance detail, and the one-pager — read The XLA Maturity Model: How Organizations Move from SLA Theater to Human Success. For why belief in CX rarely survives the budget meeting, see 9 Reasons Companies Underinvest in CX. For economics that fund the climb, use 7 Ways to Calculate CX ROI Without Hope-Based Slideware.

SLAs measure whether the service ran. XLMs measure whether humans succeeded. XLAs are how we promise — and manage — that success.

Frequently Asked Questions

What are the stages from SLA to XLA?

Five stages: (1) SLA Default — managing by uptime and handle time; (2) Experience Sensing — listening without commitment; (3) XLM Definition — human success becomes measurable; (4) XLA Adoption — experience becomes a shared commitment; (5) Experience-Led Management — XLAs steer, SLAs enable reliability underneath.

What is the difference between SLA, XLM, and XLA?

An SLA (Service Level Agreement) commits to operational performance — uptime, response, resolution. An XLM (Experience Level Measure) tracks human success — effort, confidence, agency, emotional residue. An XLA (Experience Level Agreement) is a shared commitment to defined experience outcomes, governed with XLMs. SLAs tell you the machine worked; XLMs tell you whether humans succeeded; XLAs are how you promise and manage that success.

What is XLA maturity?

XLA maturity is how far an organization has moved from steering by SLAs alone to managing by human success through XLMs and XLAs. Low maturity means green dashboards and red Tuesdays. High maturity means experience outcomes influence funding, vendor decisions, and executive reviews — with SLAs as reliability rails, not the definition of success.

How do you move from SLAs to XLAs?

Start with one critical journey. Keep SLAs as reliability constraints. Define 3–5 XLMs tied to human success, baseline them, then commit via an XLA with owners and review cadence. Rewire escalations so red XLMs trigger action like red SLAs. Scale to vendors and shared services once one journey proves the model.

What is experience-led management?

Experience-led management is Stage 5 CX maturity: the organization steers by XLAs and human-success outcomes first, with SLAs as enabling conditions underneath. Portfolio priorities, vendor scorecards, and innovation bets are judged on XLM lift. A green SLA cannot close a review if the experience commitment is red.

Image credits: Pixabay

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

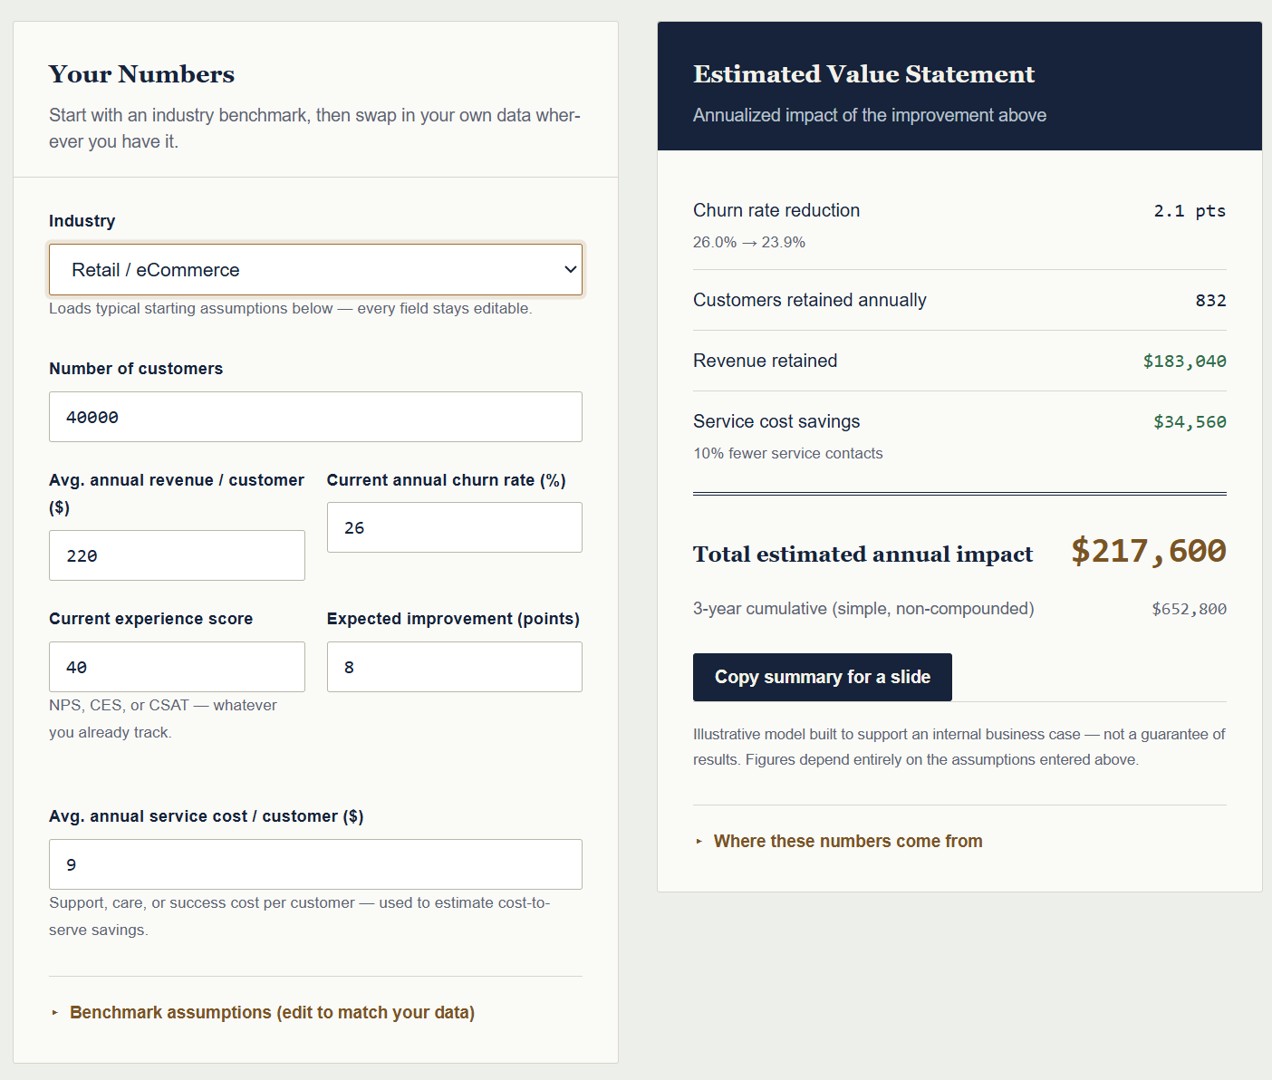
7 Ways to Calculate CX ROI Without Hope-Based Slideware

Customer Experience ROI Calculator

by Braden Kelley and Art Inteligencia


How Do You Calculate CX ROI Without Hope-Based Slideware? (Short Answer)

You calculate customer experience ROI without hope-based slideware by pricing behaviors on named journeys with your numbers — not by citing an industry NPS-to-growth chart and hoping finance translates “up and to the right” into dollars. Seven methods: retained revenue from reduced churn, failure-demand and repeat-contact cost, effort as cost-to-serve, expansion from easier buying, referral as avoided acquisition cost, the employee-attrition tax of underfunded experience, and an instrumented before/after on one intervention shown as a range.

The chain that keeps it honest is simple: experience metric → behavioral outcome → financial outcome → named intervention. If that chain breaks, you still have a slogan.

Hope Is Not a Business Case

I have sat in enough leadership rooms to recognize the moment the CX conversation dies. Someone has just shown a journey map that could win a design award. Heads have nodded. Then finance asks the only question that counts in that room: What is this worth?

What follows is usually a deck. A borrowed loyalty study. A hockey-stick that begins the quarter after implementation. A score moving “up and to the right” with no named human behavior underneath it. That is hope-based slideware. It photographs well. It does not survive a CFO who has another ask on the table with a spreadsheet attached.

Customer experience does not lose budget fights because it is soft. It loses when it stays unpriced. These seven methods put dollars on retained humans, avoided failure demand, and frontline enablement using your economics. Industry research can start the conversation. It cannot finish it.

Method What you price Hope it replaces
1. Retained revenue Avoided churn on a named journey Generic NPS-to-growth slides
2. Failure demand Repeat contacts and reopen work “Lower effort will pay for itself”
3. Effort as cost-to-serve Minutes, rework, expensive channels CES as a virtue metric
4. Expansion from less friction Attach, upsell, share of wallet “Promoters buy more” posters
5. Referral as avoided CAC Incremental qualified referrals “Word of mouth is priceless”
6. Frontline attrition tax Replacement, ramp, lost judgment CX cases that ignore employees
7. Instrumented intervention One fix, a range, a review date A single heroic ROI number

1. How Do You Calculate CX ROI from Retention?

The method: Estimate avoided churn from a specific experience fix — onboarding, billing, recovery, renewal — using your churn rate, revenue per customer, and how many customers actually hit that journey.

The math: Customers on the journey × expected reduction in leave or non-renew × revenue at risk. Start with last year’s actuals, not a mid-market benchmark someone pasted from a keynote.

The trap: A loyalty-industry slide with no company economics attached. Relative NPS leaders often grow faster than laggards. That is interesting. It is not an answer to what fixing this billing surprise is worth in this book of business.

The catch: Retention is a human staying because Tuesday got easier — not because the score moved. Name the friction you are removing. If you cannot point to the journey, you are still pricing a cloud.

2. How Do You Price Failure Demand and Repeat Contacts?

The method: Count work created by the experience being wrong the first time — second calls, reopen tickets, “any update?” chats, visits to fix a prior visit. That volume is not “busy.” It is the operating cost of a broken promise.

The math: Volume of avoidable contacts × fully loaded cost per contact (or per visit). Finance usually funds your cost-to-serve first. Customer time is real; include it only if you will actually use it in the conversation, not as decoration.

The trap: “Lower effort will pay for itself” with no contact ledger. Hope loves that sentence. Spreadsheets do not.

The catch: Fast handle time that reopens the ticket is not savings. A resolution that prevents the third contact is. If your business case rewards speed that creates return work, you are pricing the wrong behavior.

3. How Do You Turn Customer Effort into Cost-to-Serve?

The method: Price the labor inside the journey — employee minutes, rework loops, and expensive-channel use caused by confusion. The IVR maze. The bill nobody can parse. The knowledge article that lies. Those are not “pain points.” They are minutes you already pay for.

The math: Minutes saved × loaded labor rate × volume, plus mix shift from high-cost channels to appropriate ones. Appropriate does not mean cheapest. A cheap channel that fails is just failure demand with a lower sticker price.

The trap: CES as a virtue metric with no dollar bridge. Effort scores without a cost model are still slideware — just more sophisticated slideware.

The catch: Do not “save” by making the human do the company’s homework. Effort reduced for the customer and the employee is the honest version. Extraction dressed up as self-service will show up later as churn, complaints, or both.

4. How Do You Calculate Expansion ROI from Better Experience?

The method: Compare spend, attach, or expansion between customers who completed a low-effort path and those who struggled — then apply a conservative lift only to the journey you are actually fixing.

The math: Eligible customers × realistic attach or expansion lift × margin, not revenue vanity. If you cannot see a cohort difference in your data yet, say the lift is modeled. Transparency survives the room. False precision does not.

The trap: “Promoters buy more” as a poster, with no evidence from this book of business. Maybe they do. Prove it or bound it.

The catch: People expand when buying is dignified and clear — not when a campaign is louder. If the friction is still there, you are not calculating expansion ROI. You are calculating the cost of shouting over a broken path.

5. How Do You Price Referrals as Avoided Acquisition Cost?

The method: Price organic advocacy from a memorable recovery or a frictionless first success. Extra qualified referrals × what you would have paid to acquire that customer.

The math: Incremental referred customers × CAC — or, if CAC is a mess of channel soup, contribution margin of a new customer. Pick one definition. Stay consistent. Do not mix them mid-deck to make the number prettier.

The trap: “Word of mouth is priceless.” That is how it stays unfunded. Priceless is a compliment. It is not a line item.

The catch: Referral is leftover from a human who felt seen — usually after a moment of truth, not after a survey ask. You do not harvest advocacy with a “please rate us” pop-up. You earn it by making Tuesday work.

6. How Do You Calculate the Employee Cost of Underfunded CX?

The method: Price what underfunded experience does to the people who deliver it: regrettable attrition, recruiting, ramp time, and lost judgment at the moment of truth. CX business cases that pretend only customers have a P&L are incomplete on purpose.

The math: Extra quits you can credibly tie to “I know what they deserve; I am not allowed to deliver it” × replacement and ramp cost. Optionally add overtime and quality dip while the seat is empty. Use HR’s loaded replacement number if they have one. Inventing a tidy figure is just hope in a different font.

The trap: Treating employee experience as a soft HR add-on while the customer case stands alone. The two costs are related. When people with recovery power leave, customers feel it next.

The catch: The intervention is enablement — staffing, tools, decision rights at the moment of truth — not a pizza party and a poster about empathy. If the case funds a workshop but not authority, you have priced theater.

7. How Do You Build a CX Business Case a CFO Will Trust?

The method: Stop modeling “CX” as a cloud. Pick one intervention. Instrument a baseline and an after. Show conservative, expected, and optimistic. Separate what is known — today’s churn, today’s cost per contact — from what is modeled — how much the fix will move the behavior.

The math: Behavior change × dollar per behavior, for the named fix, as a three-point range, with a review date. The date matters. A model with no Tuesday to check it against is still a story.

The trap: A single heroic ROI number and a forty-page appendix of other people’s research. False precision is hope wearing a spreadsheet.

The catch: Executives fund redesigned onboarding, fixed billing logic, and empowered recovery — not “+7 NPS” floating in space. Attach the dollars to an action someone can own after the meeting ends.

What Should You Check Before You Build the CX ROI Deck?

Before the next slide that asks the room to believe, run five go/no-go questions. If you cannot answer them, you are still funding hope:

  1. Which journey and which behavior — leave, call again, expand, refer, or quit the job?
  2. Which of our numbers — not whose study?
  3. What is known versus modeled — and did we say so out loud?
  4. What range survives a skeptical read — conservative, expected, optimistic?
  5. What intervention and owner exist on Tuesday if they believe the number?

If you want a working surface for the first two methods — retained revenue and cost-to-serve — I built a free Customer Experience ROI Calculator so the value does not have to stay fuzzy. For the backup a finance partner will actually interrogate, the CX ROI Benchmark Report collects sources and the objections I hear in the room. Neither tool replaces judgment. Both beat a borrowed hockey-stick.

A score asks for belief. A priced human outcome asks for a line item. Calculate the second, and customer experience stops competing as charity. It competes as strategy — in the language enterprises already use to decide.

Frequently Asked Questions

How do you calculate CX ROI?

Calculate CX ROI by linking an experience metric to a customer or employee behavior, pricing that behavior with your own economics, and attaching the dollars to a named intervention on a specific journey. Common methods include avoided churn, repeat-contact cost, effort as cost-to-serve, expansion lift, referral as avoided CAC, and frontline replacement cost. Show a range, not a single heroic number.

Why do CX business cases fail with CFOs?

They fail when they ask finance to translate a score or an industry loyalty study into money. CFOs fund behaviors they can interrogate — retained revenue, lower cost-to-serve, avoided acquisition cost — tied to an action someone owns. Hope-based slideware cites research, shows a hockey-stick, and never names the journey or the math.

Is NPS enough to prove customer experience ROI?

No. NPS and other experience scores are signals, not a business case. They become useful for ROI only when you connect movement in the score to a behavior — renew, expand, refer, call again, or leave — and price that behavior with your churn, revenue per customer, and contact costs.

What data do you need to quantify customer experience?

Start with internal numbers: customers on the journey, churn or non-renew rate, revenue or margin per customer, fully loaded cost per contact, volume of repeat work, attach or expansion rates, CAC or contribution margin, and regrettable attrition plus replacement cost. Industry benchmarks are starter kits. Your ledger is the case.

How do you avoid fake precision in a CX business case?

Separate known facts (today’s costs and rates) from modeled assumptions (how much a fix will move behavior). Show conservative, expected, and optimistic scenarios. Pick one intervention, instrument a baseline, and set a review date. A single heroic ROI figure with false decimal places is still hope wearing a spreadsheet.

Content Authenticity Statement: The topic area, key elements to focus on, etc. were decisions made by Braden Kelley, with a little help from Google Gemini and Cursor to clean up the article, add images and create infographics.

Image credits: Pixabay

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

The Pivot to Invisinnovation

Why Doing Absolutely Nothing is the Next Big Thing

LAST UPDATED: April 1, 2026 at 8:33 AM

The Pivot to Invisinnovation

GUEST POST from Art Inteligencia


The Exhaustion of the New: A Manifesto for Invisinnovation™

We live in an era of relentless disruption. In our collective quest to “move fast and break things,” we have finally succeeded: everything is broken. From the boardrooms of Silicon Valley to the home offices of Kitsap County, the innovation community has reached a point of diminishing returns. We have optimized, digitized, and human-centered ourselves into a state of permanent “transformation fatigue.”

The Innovation Paradox

We are currently trapped in a fascinating contradiction. Organizations are spending record amounts on digital transformation and “Experience Level Measures,” yet the fundamental friction of business remains unchanged. We’ve added layers of complexity under the guise of “Organizational Agility,” resulting in a landscape where the more we innovate, the more we stay exactly the same — only now, we pay for the privilege through recurring monthly subscriptions.

The Great Quiet: Introducing Invisinnovation™

Today, I am officially proposing a radical departure from the status quo: Invisinnovation™. This is the art of achieving “Infinite Innovation” by simply… stopping. It is the realization that the most human-centered change we can offer our weary workforce is the gift of nothing new.

As we navigate the “AI Agent Paradox” and the “Great American Contraction,” we must ask ourselves the ultimate philosophical question of the modern enterprise: If a digital transformation happens in a forest, and no one is there to debug the API, did it actually provide any shareholder value?

In the sections that follow, I will outline how to move from a “Stable Spine” to a “Sofa-Bound Spine,” and how to leverage the power of doing absolutely nothing to disrupt your entire industry.

The Methodology: The “Zero-I” Framework

To successfully implement Invisinnovation™, we must move beyond the traditional “Eight I’s of Infinite Innovation.” While those served us well in the era of productivity, the current climate demands a more streamlined, sedentary approach. The Zero-I Framework is designed to protect your “Stable Spine” by ensuring your “Modular Wings” never actually leave the ground.

1. Ignore: The Vintage Feature Strategy

In traditional human-centered design, we obsess over “pain points.” In this new framework, we embrace them. The Ignore phase dictates that if a user complaint or technical bug persists for more than six months, it is no longer an issue to be solved — it is a “Vintage Feature.” By ignoring these legacy problems, you create a sense of brand nostalgia and save thousands of hours in dev-ops labor.

2. Idle: Strategic Procrastination

True organizational agility is often mistaken for movement. However, the most agile move one can make is to remain perfectly still while the competition tires itself out. Idling involves letting your “AI Agents” engage in endless, circular arguments with one another in a closed loop. While the algorithms debate the ethics of their own existence, the human workforce can finally enjoy a quiet afternoon without a single “urgent” notification.

3. Invisible: The Frictionless Void

We’ve reached the apex of experience design: The Frictionless Void. A truly invisible experience is one where the customer doesn’t even realize they have interacted with your brand. By removing the interface, the product, and the service entirely, you eliminate all possible “Exasperation Level Measures” (XLMs).

“The most disruptive interface is the one that doesn’t exist, charging a subscription for a service that isn’t running, to a customer who has forgotten they signed up.”

This is the ultimate evolution of Experience Design. When your innovation is truly invisible, you no longer have to worry about the “Human-in-the-Loop”—because the loop has been closed, locked, and the key has been hidden behind a “404 Not Found” page.

New Metrics for the Modern Leader: Tracking the Void

If you can’t measure it, it didn’t happen. But in the world of Invisinnovation™, if you can measure it, you’re probably trying too hard. To align with our “Zero-I” methodology, we must retire antiquated KPIs like Net Promoter Scores and conversion rates. Instead, we look toward the “Quiet Metrics” that define the successful, inactive enterprise of 2026.

ROI: Return on Indifference

Traditional ROI focuses on investment, but we are pivoting to Indifference. This metric tracks the beautiful moment when your stakeholders, board members, and customers stop asking for updates entirely. A high Return on Indifference indicates that you have successfully lowered expectations to a level of “Permanent Zen.” When no one expects a “Modular Wing” update, every day you don’t ship code is a 100% win for the bottom line.

XLMs: Exasperation Level Measures

While I have long championed Experience Level Measures, April 1st requires us to look at the darker twin: Exasperation Level Measures (XLMs). We no longer track “customer delight”; we track the precise millisecond a user transitions from “minor annoyance” to “throwing their smartphone into a body of water.”

By mapping the XLM journey, we can identify the “Peak Rage” points in our digital transformation. The goal of Invisinnovation™ is to keep users in a state of “Low-Level Hum of Despair,” which is far more sustainable for long-term retention than the volatile highs of actual satisfaction.

The Stable Spine… Literally

We’ve talked extensively about the Stable Spine vs. Modular Wings agility model. Today, we take the “Stable Spine” literally. In an era of constant “Sprints” and “Scrums,” the most radical innovation is to maintain perfect, unmoving posture.

Success is no longer measured by how fast you pivot, but by how long you can sit in an ergonomic chair without feeling the urge to check a dashboard. If your spine remains stable while the rest of the market collapses in a frantic, agile heap, you have achieved the ultimate competitive advantage: Superior Inertia.

“True organizational agility is the ability to watch a trend pass by and say, ‘Not my problem,’ with a straight face.”

The New Innovation Roles: Introducing “The Silent Nine”

Braden Kelley’s insightful book Stoking Your Innovation Bonfire identified the Nine Innovation Roles necessary for a sustainable ecosystem. However, as we transition into the era of Invisinnovation™, those roles have mutated. To survive the “Great American Contraction” of 2026, your team doesn’t need more “movers and shakers”; it needs practitioners of the “Quiet Arts.”

1. The Ghost (Formerly The Connector)

The Ghost is the ultimate evolution of the workplace collaborator. This individual is perpetually “Green” on Slack and appears as a pulsing circle in the corner of shared Google Docs, yet they haven’t uttered a word in a meeting since the late 2020s. They are the masters of Presence Without Participation, ensuring that the “Stable Spine” of the company remains unburdened by new ideas.

2. The Vanishing Act (Formerly the Magic Maker)

In a traditional innovation framework, the Magic Maker brings ideas to life. In the Invisinnovation™ model, their talent is reversed. This role is responsible for making “Urgent” executive mandates, frantic “asap” emails, and half-baked digital transformation initiatives simply… disappear. They don’t solve problems; they evaporate them into the “Frictionless Void.”

3. The Human-in-the-Loop (The “Ignore All” Specialist)

As AI ethics and causal AI become increasingly noisy, the Human-in-the-Loop (HIL) takes on a vital new responsibility. This person is tasked with sitting in front of a high-resolution 16:9 monitor and clicking “Ignore All” on every algorithmic bias warning that pops up. This allows the AI to continue its circular arguments (as defined in the Idle phase) without being distracted by pesky things like “reality” or “human impact.”

4. The Accidental Innovator (Formerly the Conscript)

The Conscript is the only person still doing actual work, purely because they forgot how to set an “Out of Office” reply. They are the human infrastructure holding up the entire façade. We keep them around not for their strategic insight, but because they are the only ones who remember the password to the WordPress admin panel where we post our manifestos.

5. The Strategic Delayer (Formerly The Customer Champion)

While the Customer Champion normally lives on the edge of the organization to bring the outside in, the Strategic Delayer uses that “customer insight” as a weapon of inertia. They claim that “the customer isn’t ready for this” or “we need one more focus group,” ensuring that no disruptive ideas ever actually reach the marketplace. By staying perpetually “on the edge,” they ensure the center remains unbothered.

6. The Semantic Architect (Formerly The Revolutionary)

The Revolutionary used to shake things up with constant new ideas. In the Invisinnovation™ framework, they become the Semantic Architect. Instead of changing the business, they change the dictionary. They use their loud voice to rebrand a complete lack of progress as a “Radical Period of Strategic Reflection.” They don’t revolt against the status quo; they rewrite the history of the status quo to make it look like a revolution.

7. The Mirror (Formerly The Evangelist)

The Evangelist is known for building support and educating others on value. The Mirror takes that energy and directs it solely at the executive leadership. They don’t educate the market; they reflect the leader’s own existing biases back to them with such charismatic fervor that the leader feels “innovative” just for having the same thoughts they had yesterday. It is the ultimate “Stable Spine” validation.

8. The Feature Archeologist (Formerly The Troubleshooter)

The Troubleshooter loves tough problems. The Feature Archeologist, however, loves preserving them. Instead of clearing roadblocks, they dig through the legacy “Paperless Paperweight” archives to find bugs from a decade ago and curate them like museum artifacts. They argue that these “Vintage Features” are essential to the brand’s identity, ensuring that no actual troubleshooting ever disrupts the peaceful decay of the system.

9. The Silent Partner (Formerly The Judge)

The Judge is usually responsible for determining what can be made profitably. The Silent Partner has already judged everything and decided that “doing nothing” has the highest profit margin of all. They provide the budget for Invisinnovation™ initiatives and then immediately disappear. By being permanently “out of the office,” they ensure that no final decisions are ever made, which is the most profitable outcome of all.

“The most effective innovation team is the one where nobody knows exactly what anyone else does, but everyone agrees that it’s probably best not to ask.”

By re-aligning your talent around these silent roles, you ensure that your “Experience Level Measures” remain perfectly flat — the ultimate sign of a stable, unbothered organization.

Case Study: The Triumph of the “Paperless” Paperweight

To illustrate the power of Invisinnovation™, we look to a recent success story from a Fortune 500 leader in the manufacturing sector. Faced with a mandate to achieve 100% digital transformation by the end of Q1 2026, the organization found itself paralyzed by the “AI Agent Paradox.” Their solution was as elegant as it was invisible.

The Digital-Analog Hybrid Loop

Rather than re-engineering their legacy COBOL systems — a task that would have threatened their “Stable Spine” — the IT department implemented the “Scan-Back” Protocol. Employees were instructed to print every digital PDF, physically sign it with a fountain pen to ensure “Human-Centered” authenticity, and then scan it back into the system as a high-resolution TIFF file.

The result? A 300% increase in cloud storage utilization (a key metric for “Digital Growth”) and a total elimination of searchable data, rendering the company’s proprietary information completely invisible to competitors and, conveniently, their own audit committee.

The “Gary” Variable

The true hero of this digital evolution was a middle manager named Gary. While the rest of the enterprise debated the merits of Causal AI and “Market Engineering,” Gary simply refused to log into the new CRM. By maintaining his own “Shadow Infrastructure” composed entirely of Post-it notes and a localized Excel 97 spreadsheet, Gary prevented a system-wide collapse during the Great Server Migration of February.

Gary represents the ultimate Human-in-the-Loop. His refusal to change provided the “Stable Spine” the company needed while the “Modular Wings” of the executive suite were flapping fruitlessly in a vacuum of their own making.

“Transformation is not about where you are going; it’s about how much hardware you can purchase while staying exactly where you are.”

By following this organization’s lead, you too can claim “Infinite Innovation” without the messy inconvenience of actually changing how your business operates. It is the ultimate victory: a transformation so complete, it left no trace of itself behind.

Conclusion: Embracing the Void

As we wrap up this exploration into the future of Invisinnovation™, the final directive is clear: Stop. In our relentless pursuit of “Infinite Innovation,” we have forgotten the most human-centered change of all — the ability to sit still and let the dust settle.

The Final Pivot: The Call to Inaction

Today, I challenge you to reject the urge to brainstorm. Do not ideate. Do not update your “Modular Wings” to the latest beta version of a generative AI tool that promises to write your emails for you (only for you to spend three hours editing them). Instead, embrace the Stable Spine in its purest form.

The most innovative thing you can do is to close your laptop, ignore your “Exasperation Level Measures” (XLMs), and pretend for a moment that the “AI Agent Paradox” was just a particularly vivid, data-heavy dream.

The Final Word

Transformation is not a destination; it is a recurring billing cycle. By mastering the art of being invisible, you don’t just survive the “Great American Contraction” — you transcend it. You become the ghost in the machine, the “Magic Maker” who turns a chaotic roadmap into a serene, empty whiteboard.

“In a world of constant noise, the most disruptive sound is silence. And in a world of constant ‘New,’ the most radical act is ‘None.'”

Go forth and do absolutely nothing. Your stakeholders won’t thank you — mostly because, if you’ve done it right, they won’t even know you’re there.


Editor’s Note: If you found yourself nodding along to these strategies, you may be suffering from “Corporate Satire Syndrome.” For immediate recovery, please consult your Charting Change manual, or simply wait until April 2nd when we return to our regularly scheduled programming of actual, high-impact innovation.

Happy April Fool’s Day!

Frequently Asked Questions: Mastering the Void

For those seeking further clarity on the Invisinnovation™ framework, we have compiled the following FAQ. This section is optimized for both human comprehension and search engine “answer engines” via the embedded JSON-LD schema.

1. What is the primary difference between traditional innovation and Invisinnovation™?

Traditional innovation focuses on the “Eight I’s” to create tangible, often disruptive, change. Invisinnovation™ focuses on “The Great Quiet,” where the goal is to achieve strategic stability by intentionally doing nothing, thereby avoiding the “Exasperation Level Measures” (XLMs) associated with constant, unnecessary updates.

2. How does the “Stable Spine” apply?

The “Stable Spine” transitions from an organizational metaphor to a literal physical state. It encourages leaders to maintain a posture of “Superior Inertia,” ignoring the “Modular Wings” of frantic industry trends and “AI Agent Paradox” hype in favor of a sedentary, unbothered workday.

3. Is Invisinnovation™ a permanent business strategy?

While highly effective during the “Great American Contraction” and specifically on April Fool’s Day, Invisinnovation™ is best used as a temporary “cleansing” strategy. It allows organizations to reset their “Human-in-the-Loop” before returning to the actual human-centered change methodologies found in Charting Change.

Disclaimer: This article speculates on the potential future applications of cutting-edge scientific research. While based on current scientific understanding, the practical realization of these concepts may vary in timeline and feasibility and are subject to ongoing research and development.

Image credits: ChatGPT

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

Organizational Digital Exhaust Analysis

Unlocking the Invisible Signals That Shape Innovation and Change

LAST UPDATED: March 20, 2026 at 5:44 PM

Organizational Digital Exhaust Analysis

GUEST POST from Art Inteligencia


The Invisible Byproduct of Work: What is Digital Exhaust?

Every organization is producing more data than ever before. Dashboards are full, KPIs are tracked, and reports are generated with increasing frequency. And yet, despite this abundance, many leaders still find themselves asking a fundamental question: “What is really happening inside our organization?”

The answer often lies not in the data we intentionally collect, but in the data we unintentionally leave behind. This is what we call digital exhaust—the invisible trail of signals created as people interact with systems, processes, and each other in the course of getting work done.

Digital exhaust includes everything from collaboration patterns in tools like email, Slack, and Teams, to clickstreams in customer journeys, to the subtle workarounds employees create when processes don’t quite fit reality. It is not designed, structured, or curated. It simply exists as a byproduct of activity.

Most organizations focus their attention on intentional data—metrics they define in advance: sales targets, operational efficiency scores, customer satisfaction ratings. These are important, but they are also inherently limited. They reflect what leaders thought would matter ahead of time.

Digital exhaust, by contrast, captures what actually does matter in practice. It reveals:

  • Where employees are struggling despite “green” metrics
  • How work really flows across teams, not how it is designed to flow
  • Where customers encounter friction that was never anticipated
  • Which informal behaviors are compensating for broken systems

In this sense, digital exhaust is not just data—it is a form of organizational truth-telling. It exposes the gap between the designed experience and the lived experience.

For leaders focused on human-centered change and innovation, this distinction is critical. Traditional measurement systems tend to reinforce existing assumptions. Digital exhaust challenges them. It brings visibility to the moments of friction, improvisation, and adaptation where real innovation opportunities are hiding.

Perhaps the most powerful way to think about digital exhaust is this: It is a passive, always-on listening system for your organization.

Unlike surveys or interviews, it does not rely on what people say after the fact. It reflects behavior in real time, at scale, and often without the filters that come with formal reporting. It captures the signals people don’t even realize they are sending.

And that is precisely why it is so valuable. Buried in this exhaust are the early indicators of change resistance, subtle signs of employee disengagement, and the unarticulated needs of customers. It is where inefficiencies whisper before they become visible problems, and where innovation opportunities emerge before they are formally recognized.

The challenge is not whether digital exhaust exists—it already does, in massive quantities. The challenge is whether organizations are willing and able to see it for what it is: not noise, but signal.

Organizations that learn to listen to their digital exhaust gain something incredibly powerful: a clearer, more human-centered understanding of how work actually happens. And with that understanding comes the ability to design change and innovation efforts that are grounded in reality, not assumption.

Why Digital Exhaust Matters for Change and Innovation

Most change initiatives don’t fail because of poor strategy. They fail because leaders are operating with an incomplete—or worse, inaccurate—understanding of how their organization actually functions. This is where digital exhaust becomes a game changer.

At its core, digital exhaust provides a continuous, behavior-based view of the organization in motion. It captures the difference between how work is designed and how it is actually performed. And in that gap lies the truth about why change efforts stall and where innovation opportunities emerge.

Traditional change management relies heavily on lagging indicators—survey results, adoption metrics, and post-implementation reviews. By the time these signals appear, the organization has already absorbed the impact, for better or worse. Digital exhaust, on the other hand, offers something far more valuable: early visibility into emerging patterns of behavior.

This early visibility allows leaders to detect and respond to critical dynamics in real time, including:

  • Change Resistance: Not through what people say, but through what they do—avoiding new tools, reverting to old processes, or creating parallel workarounds.
  • Process Friction: Identifying bottlenecks, repeated handoffs, or excessive rework that signal misaligned or poorly designed workflows.
  • Cultural Misalignment: Revealing disconnects between stated values and actual behavior patterns.
  • Hidden Work: Surfacing informal, often invisible effort employees expend to compensate for gaps in systems or processes.

For innovation leaders, this is where things get especially interesting. Digital exhaust doesn’t just highlight problems—it illuminates possibilities. Every workaround is a signal of unmet need. Every friction point is a potential innovation opportunity. Every unexpected behavior pattern is a clue about how people are adapting to constraints in ways the organization did not anticipate.

In other words, innovation lives in the gaps between designed experience and lived experience.

When organizations ignore digital exhaust, they effectively blind themselves to these gaps. They continue to invest in solutions based on assumptions, often optimizing for a version of reality that no longer exists. This is how well-intentioned initiatives end up driving “hallucinatory innovation”—building elegant solutions to problems that don’t actually matter.

Conversely, organizations that leverage digital exhaust gain the ability to:

  • Continuously validate whether change is working as intended
  • Identify emerging needs before they are formally articulated
  • Adapt strategies dynamically based on real-world behavior
  • Reduce the gap between leadership perception and employee/customer reality

This shifts the role of leadership from one of prediction to one of perception and response. Instead of trying to anticipate every outcome, leaders can sense what is happening and adjust accordingly.

The implications are profound. Change becomes less about large, episodic transformations and more about continuous alignment. Innovation becomes less about isolated breakthroughs and more about systematically uncovering and addressing real human needs.

Ultimately, digital exhaust matters because it reconnects organizations with reality. It grounds strategy in behavior, not intention. And in a world where the pace of change continues to accelerate, that grounding may be the most important competitive advantage of all.

From Data to Meaning: The Practice of Digital Exhaust Analysis

If digital exhaust is the raw signal of how work actually happens, then digital exhaust analysis is the discipline of turning that signal into meaning. This is where many organizations struggle—not because they lack data, but because they lack a systematic way to interpret it in a human-centered way.

The first step is recognizing the breadth of digital exhaust across the enterprise. Every interaction, transaction, and workflow leaves behind traces of behavior. Individually, these signals may seem insignificant. Collectively, they form a dynamic, continuously updating picture of how the organization actually operates.

Common sources of digital exhaust include:

  • Collaboration Tools: Email, messaging platforms, and meeting systems that reveal communication flows, decision bottlenecks, and collaboration overload.
  • Customer Interactions: Support tickets, chat logs, call transcripts, and clickstream data that expose friction, confusion, and unmet expectations.
  • Operational Systems: CRM, ERP, and workflow platforms that capture how processes actually unfold, including delays, rework loops, and exception handling.
  • Content and Knowledge Systems: Document creation, editing patterns, and knowledge-sharing behaviors that reflect how information is accessed, reused, or lost.

But volume alone does not create insight. The real shift comes from applying analytical approaches that focus on behavior rather than static metrics. Instead of asking “What happened?”, digital exhaust analysis asks “How and why did it happen this way?”

Effective analysis typically combines multiple techniques:

  • Behavioral Pattern Recognition: Identifying recurring actions, deviations, and anomalies that signal friction, adaptation, or emerging habits.
  • Process Mining and Journey Reconstruction: Rebuilding actual workflows and customer journeys based on real activity, not designed processes.
  • Language and Sentiment Analysis: Examining tone, word choice, and context in communications to uncover emotion, confusion, or resistance.
  • Network and Interaction Analysis: Mapping how people and teams connect to reveal informal influence structures and collaboration patterns.

A critical principle in this work is triangulation. No single data source tells the full story. Only by combining multiple signals can organizations distinguish between noise and meaningful patterns.

Equally important is the shift from retrospective reporting to continuous sensing. Traditional analytics looks backward, summarizing what has already occurred. Digital exhaust analysis, when done well, enables organizations to monitor patterns as they emerge and evolve—creating the opportunity to respond in near real time.

This does not mean automating decisions blindly. On the contrary, the goal is to augment human judgment. The role of digital exhaust analysis is to surface signals that prompt better questions, deeper inquiry, and more informed action.

Ultimately, the practice is not about mastering tools—it is about building a new organizational capability: the ability to see clearly, move beyond assumptions, understand behavior in context, and translate that understanding into smarter, more human-centered decisions about change and innovation.

Human-Centered Interpretation: Avoiding the Measurement Trap

One of the most dangerous assumptions organizations make is that data is objective. It isn’t. Data is shaped by what we choose to measure, how we collect it, and the context in which we interpret it. Digital exhaust may feel more “real” because it is behavior-based, but it is still incomplete without thoughtful, human-centered interpretation.

This is where many digital exhaust initiatives go off track. Leaders see a new stream of rich behavioral data and immediately move to optimize against it—reducing time, increasing throughput, or eliminating variance. In doing so, they risk falling into the very trap they were trying to escape: mistaking signals for truth and metrics for meaning.

The reality is that every data point carries ambiguity. A spike in after-hours activity could indicate high engagement—or it could signal burnout. A reduction in collaboration might reflect improved efficiency—or growing silos. Without context, interpretation becomes guesswork dressed up as insight.

This is why digital exhaust analysis must be grounded in a human-centered mindset. The goal is not to monitor people more closely, but to understand their experiences more deeply.

There is also an important ethical dimension to consider. The same data that can illuminate friction and unlock innovation can also feel invasive if misused. Employees who believe they are being surveilled will adapt their behavior—not to improve outcomes, but to protect themselves. When that happens, the integrity of the data itself begins to erode.

Organizations must therefore be intentional about how they approach digital exhaust:

  • Transparency: Be clear about what is being analyzed, why it matters, and how it will (and will not) be used.
  • Purpose: Focus on improving systems and experiences, not evaluating or policing individuals.
  • Context: Combine behavioral data with qualitative insights—interviews, observation, and direct feedback—to understand the “why” behind the patterns.
  • Humility: Treat insights as hypotheses to explore, not conclusions to enforce.

At its best, digital exhaust analysis becomes a tool for empathy at scale. It helps leaders see where people are struggling, where systems are failing, and where expectations are misaligned—not in theory, but in lived experience.

This requires a fundamental shift in mindset: from control to curiosity. Instead of asking, “How do we make people comply with the process?” leaders begin asking, “Why does the process not work for people?” That shift is where real transformation begins.

Because the ultimate goal is not to create perfectly optimized systems. It is to design organizations that work with humans, not against them. And that means recognizing that behind every data point is a person making choices, adapting to constraints, and trying to get their work done.

Digital exhaust can show you what is happening. But only a human-centered approach can help you understand why—and what to do about it in a way that builds trust rather than erodes it.

Use Cases That Actually Move the Needle

Digital exhaust analysis only becomes valuable when it drives better decisions and meaningful outcomes. While the concept can feel abstract, its impact becomes very concrete when applied to real organizational challenges. The key is to focus on use cases where behavior-based insight can close the gap between intention and reality.

The following are some of the highest-impact applications of digital exhaust analysis across change, experience, and innovation:

Change Management: Seeing Adoption as It Happens

Traditional change management relies on training completion rates, survey feedback, and delayed adoption metrics. These signals often arrive too late to correct course effectively.

Digital exhaust provides a real-time view of how people are actually engaging with new tools, processes, or ways of working. Leaders can identify:

  • Where employees are reverting to legacy systems or behaviors
  • Which teams are adopting quickly—and why
  • Where informal workarounds are emerging

This enables faster intervention, targeted support, and ultimately a higher likelihood of sustained change.

Employee Experience: Detecting Friction and Burnout Early

Employee experience is often measured through periodic surveys, which provide valuable but infrequent snapshots. Digital exhaust fills in the gaps between those moments.

By analyzing collaboration patterns, workload signals, and communication behaviors, organizations can detect:

  • Meeting overload and fragmentation of focus time
  • After-hours work patterns that may indicate burnout risk
  • Breakdowns in cross-functional collaboration

Instead of reacting to disengagement after it occurs, leaders can proactively redesign work environments to better support how people actually operate.

Customer Experience: Uncovering Hidden Friction

Customer journeys are carefully designed, but rarely experienced exactly as intended. Digital exhaust reveals where those designs break down in practice.

Through analysis of clickstreams, support interactions, and behavioral flows, organizations can identify:

  • Points where customers hesitate, abandon, or seek help
  • Inconsistencies across channels and touchpoints
  • Unmet needs that are not captured in structured feedback

These insights enable more precise, evidence-based improvements to the customer journey—reducing friction and increasing satisfaction in ways that traditional metrics alone cannot achieve.

Innovation Discovery: Finding Opportunity in Workarounds

One of the most overlooked sources of innovation is the set of informal solutions people create to get their work done. These workarounds are not failures—they are signals.

Digital exhaust analysis helps surface:

  • Repeated deviations from standard processes
  • Shadow systems and tools adopted outside official channels
  • Emerging behaviors that indicate shifting needs or expectations

Each of these represents an opportunity to design better solutions that align with how people naturally work, rather than forcing them into rigid structures.

Operational Excellence: Moving Beyond Efficiency to Effectiveness

Many operational improvement efforts focus narrowly on efficiency—reducing time, cost, or variability. Digital exhaust enables a broader view that includes effectiveness and experience.

By reconstructing actual workflows, organizations can identify:

  • Hidden loops of rework and redundancy
  • Misaligned handoffs between teams or systems
  • Disconnects between formal processes and real execution

This allows for redesign efforts that not only streamline operations but also make them more intuitive and resilient.

Across all of these use cases, the common thread is speed of learning. Digital exhaust shortens the feedback loop between action and insight. It allows organizations to move from periodic evaluation to continuous adaptation.

And in an environment where change is constant, that ability—to learn faster than the pace of disruption—is what ultimately separates organizations that struggle from those that thrive.

Digital Exhaust Flow

The Technology Ecosystem Powering Digital Exhaust Analysis

While digital exhaust is created naturally through everyday work, unlocking its value requires a rapidly evolving ecosystem of technologies. No single platform owns this space. Instead, it is an emerging convergence of analytics, artificial intelligence, process mining, and digital twin capabilities—each contributing a piece of the broader puzzle.

Understanding this ecosystem is critical, not because organizations need to adopt every tool, but because it reveals where the market is heading: toward a future of organizational observability—the ability to continuously sense, interpret, and respond to how work actually happens.

Enterprise Platforms: Scaling Insight Across Complex Systems

Large enterprise technology providers are embedding digital exhaust analysis into broader platforms that integrate data across operations, customers, and assets. These solutions often combine IoT, analytics, and simulation to create end-to-end visibility.

  • Siemens: Leveraging digital twin technology to simulate and optimize complex systems, capturing exhaust signals from both physical and digital environments.
  • General Electric: Applying industrial data analytics to monitor performance, predict issues, and improve operational outcomes.
  • Dassault Systèmes: Enabling virtual modeling of organizations and ecosystems to better understand how processes and interactions unfold.
  • PTC: Integrating IoT and augmented reality to connect frontline activity with enterprise systems, generating rich behavioral data streams.

These platforms are particularly powerful in environments where physical and digital systems intersect, but their broader impact is the normalization of continuous data capture and analysis at scale.

Advanced Analytics and Simulation Engines

A second layer of the ecosystem focuses on making sense of complexity. These tools excel at modeling, simulation, and high-dimensional analysis—turning raw exhaust into predictive and prescriptive insight.

  • ANSYS: Known for engineering simulation, increasingly applied to model system behavior and test scenarios before changes are implemented.
  • Altair: Combining data analytics, AI, and high-performance computing to uncover patterns and optimize outcomes across complex environments.

These capabilities allow organizations to move beyond hindsight and into foresight—understanding not just what is happening, but what is likely to happen next under different conditions.

Process Mining and Behavioral Analytics Innovators

One of the fastest-growing segments in this space is process mining and behavioral analytics. These solutions reconstruct workflows and interactions from event logs, revealing how processes actually execute across systems and teams.

They provide:

  • End-to-end visibility into real process flows
  • Identification of bottlenecks, deviations, and rework
  • Data-driven opportunities for automation and redesign

By grounding analysis in actual behavior, these tools bring a level of objectivity and clarity that traditional process mapping rarely achieves.

Emerging Startups: Democratizing Insight

Alongside established players, a new generation of startups is pushing the boundaries of what digital exhaust analysis can do. These companies are often more focused, more agile, and more explicitly human-centered in their approach.

They are exploring innovations such as:

  • AI-driven pattern detection and anomaly identification
  • Natural language processing applied to communication data
  • Lightweight tools that make insight accessible beyond data science teams
  • Privacy-first architectures that balance insight with trust

Their collective impact is to lower the barrier to entry—making it possible for more organizations to experiment with and benefit from digital exhaust analysis without massive upfront investment.

The Convergence Toward Organizational Observability

What is most important is not any individual tool, but the direction of travel. These technologies are converging toward a shared goal: creating organizations that can continuously observe themselves.

In software engineering, observability transformed how systems are managed—shifting from reactive troubleshooting to proactive monitoring and adaptation. A similar transformation is now underway at the organizational level.

The implication is clear. In the near future, leading organizations will not rely on periodic reports to understand performance. They will operate with a living, breathing view of how work unfolds—powered by digital exhaust and the technologies that bring it to life.

The question is no longer whether these capabilities will exist, but how quickly organizations will learn to use them in a way that is both effective and human-centered.

Building the Capability: From Experiment to Enterprise Muscle

Recognizing the value of digital exhaust is one thing. Building the organizational capability to use it consistently and effectively is another. Many organizations start with enthusiasm, launch a pilot, and then stall—unable to scale insight beyond isolated use cases.

The difference between experimentation and impact lies in treating digital exhaust analysis not as a tool, but as a core organizational muscle—one that must be intentionally developed, embedded, and sustained over time.

Start Small, But Start Where It Matters

The most successful organizations resist the urge to boil the ocean. Instead, they begin with a focused, high-value problem—typically a journey or process where friction is both visible and consequential.

This might include:

  • A struggling change initiative with uneven adoption
  • A critical customer journey with known pain points
  • An internal process plagued by delays or rework

By instrumenting relevant systems and analyzing the resulting digital exhaust, teams can generate early wins that demonstrate both value and feasibility.

Build Cross-Functional Alignment Early

Digital exhaust does not belong to a single function. It spans IT, HR, customer experience, operations, and innovation. As a result, siloed approaches quickly run into limitations.

Leading organizations bring together cross-functional teams that combine:

  • Technical expertise (data engineering, analytics, AI)
  • Domain knowledge (HR, CX, operations)
  • Human-centered design and research capabilities

This combination ensures that insights are not only technically sound, but also contextually meaningful and actionable.

Establish Clear Governance and Ethical Guardrails

As digital exhaust analysis scales, questions of trust, privacy, and appropriate use become unavoidable. Without clear guardrails, even well-intentioned efforts can create resistance or unintended consequences.

Effective governance includes:

  • Transparency: Communicating openly about what data is being used and for what purpose
  • Boundaries: Defining what will not be measured or inferred, particularly at the individual level
  • Accountability: Ensuring that insights are used to improve systems, not penalize people

Trust is not a byproduct of capability—it is a prerequisite for it.

Shift the Mindset: From Reporting to Sensing and Adapting

Perhaps the most important transformation is cultural. Traditional organizations are built around reporting—periodic snapshots of performance against predefined metrics.

Digital exhaust enables something fundamentally different: continuous sensing. But to realize this value, leaders must embrace a new operating model—one that prioritizes learning and adaptation over control and prediction.

This means:

  • Acting on directional insight rather than waiting for perfect data
  • Testing and iterating in shorter cycles
  • Empowering teams to respond to what they observe in real time

Over time, this shift transforms digital exhaust analysis from a specialized capability into an embedded way of working.

Scale What Works, Systematically

Once early use cases demonstrate value, the focus should shift to scaling—not by replicating tools, but by codifying practices. This includes:

  • Standardizing data pipelines and integration patterns
  • Creating reusable analytical models and frameworks
  • Embedding insights into existing decision-making processes

The goal is to make digital exhaust analysis repeatable, reliable, and accessible across the organization.

Ultimately, organizations that succeed in this space do not treat digital exhaust as a one-time initiative. They build it into the fabric of how they operate—continuously listening, learning, and adapting.

And in doing so, they move closer to something every organization aspires to, but few achieve: the ability to evolve as quickly as the world around them.

The Future: From Digital Exhaust to Adaptive Organizations

The journey from collecting digital exhaust to building a fully adaptive organization is both a technological and cultural evolution. It requires more than tools or analytics—it demands a mindset shift where organizations listen continuously, respond intelligently, and innovate in alignment with real human behavior.

Organizations that master digital exhaust will develop capabilities similar to observability in software systems: they will sense emerging issues, anticipate bottlenecks, and detect opportunities before they become urgent. This real-time awareness allows leadership to act proactively rather than reactively.

Key hallmarks of adaptive organizations powered by digital exhaust include:

  • Continuous Sensing: Systems and processes generate ongoing behavioral data, providing a real-time view of organizational health and performance.
  • Rapid Feedback Loops: Insights flow quickly to decision-makers, enabling faster course corrections and iterative improvements.
  • Behavior-Informed Innovation: Emerging patterns reveal unmet needs, workarounds, and latent opportunities, fueling human-centered innovation.
  • Trust-Centered Design: Analysis is conducted ethically and transparently, preserving employee and customer confidence.

The implications are profound. Change initiatives no longer rely solely on annual plans or post-implementation reviews. Innovation is no longer limited to isolated labs or ideation workshops. Instead, the organization becomes a living, learning system, continuously adapting based on how people actually work, collaborate, and engage.

Looking forward, the integration of AI and automation with digital exhaust analysis promises even more sophisticated capabilities. Intelligent agents may highlight emerging friction points, suggest targeted interventions, or simulate the potential outcomes of proposed changes before they are executed.

Yet, technology alone is not enough. Adaptive organizations are built on a foundation of human-centered insight, trust, and curiosity. Leaders must listen carefully, interpret thoughtfully, and act with empathy—turning the passive signals of digital exhaust into meaningful transformation.

The ultimate promise of this approach is clear: organizations that learn to sense and respond effectively will not just survive change—they will thrive in it. By transforming digital exhaust from noise into signal, they unlock the ability to innovate continuously, adapt dynamically, and create lasting value for employees, customers, and stakeholders alike.

In a world of accelerating complexity, the question is no longer whether digital exhaust matters. The question is whether your organization is ready to listen—and evolve.

Frequently Asked Questions (FAQ)

What is digital exhaust in an organization?

Digital exhaust is the unintentional trail of data created by employees, customers, and systems as they interact with processes and tools. It includes patterns of behavior, communication flows, process deviations, and other signals that reveal how work actually happens, beyond formal metrics.

How can digital exhaust analysis improve innovation and change initiatives?

Digital exhaust analysis provides real-time insights into actual behavior and process execution. By identifying friction points, informal workarounds, and adoption gaps, organizations can adapt more quickly, design human-centered solutions, and uncover opportunities for innovation that traditional metrics may miss.

What are the ethical considerations when analyzing digital exhaust?

Ethical considerations include ensuring transparency, protecting individual privacy, and using insights to improve systems rather than monitor or penalize people. Organizations should combine quantitative data with qualitative context, communicate clearly about data usage, and maintain trust to preserve the integrity of the analysis.

Disclaimer: This article speculates on the potential future applications of cutting-edge scientific research. While based on current scientific understanding, the practical realization of these concepts may vary in timeline and feasibility and are subject to ongoing research and development.

Image credits: ChatGPT

Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.

Synthetic Data Generation

Fueling Innovation Without Compromising Reality

LAST UPDATED: March 13, 2026 at 2:44 PM
Synthetic Data Generation Innovation Catalyst

GUEST POST from Art Inteligencia


I. The Data Dilemma: Why Innovation Is Starving for Better Data

We live in a time when organizations claim to be “data-driven,” yet many of the most important innovation decisions are still made with incomplete, restricted, or unusable data. Leaders want evidence before they invest. Teams want data before they experiment. And regulators rightly demand protection of customer information. The result is a paradox that slows progress across industries.

The truth is simple: the data that organizations most need in order to innovate is often the data they are least able to access.

Historical datasets are plentiful when organizations are studying the past. But innovation is not about the past. Innovation is about exploring possibilities that have never existed before. When teams attempt to build new products, design new services, or explore entirely new business models, the historical data they rely on often becomes a constraint instead of an enabler.

The Innovation Paradox

The more disruptive or novel an idea becomes, the less historical data exists to support it. That creates an innovation paradox: organizations increasingly rely on data to make decisions, yet the ideas with the greatest potential for impact are the ones least supported by existing data.

When decision-makers cannot find data to justify an idea, they frequently default to safer, incremental improvements rather than bold experimentation. Over time, this dynamic can quietly suffocate innovation cultures. Teams begin optimizing existing processes instead of exploring new opportunities.

In other words, the absence of data often becomes an invisible veto against new ideas.

Why Traditional Data Strategies Fall Short

Most enterprise data strategies were designed to improve operational efficiency, not to enable experimentation. Data warehouses, analytics pipelines, and reporting dashboards are excellent at analyzing what has already happened. They are far less capable of supporting rapid exploration of what might happen next.

Several structural challenges make it difficult for organizations to use traditional data for innovation:

  • Privacy restrictions: Customer data is often highly sensitive and governed by strict regulatory frameworks.
  • Limited access: Critical datasets may sit inside departmental silos or restricted systems.
  • Incomplete information: Real-world datasets frequently contain missing or inconsistent records.
  • Bias in historical data: Past decisions can embed systemic bias into the datasets used to train modern systems.
  • Lack of edge cases: Rare events or unusual scenarios that innovators want to explore rarely appear in historical data.

These constraints create friction for teams attempting to test new ideas. Data scientists cannot access the information they need. Product teams must wait for approvals. Designers cannot simulate the kinds of edge-case experiences that shape truly resilient solutions.

When Data Becomes a Barrier Instead of an Enabler

Ironically, the organizations that invest most heavily in data infrastructure can still struggle to innovate if their data governance frameworks prioritize protection over experimentation. Security and privacy are essential, but when every new initiative requires months of approvals to access usable datasets, teams lose momentum.

Innovation thrives on experimentation. Experimentation requires safe environments where teams can test ideas quickly, learn from failures, and iterate rapidly. Without accessible data, that experimentation becomes slow, expensive, or impossible.

This is where many organizations find themselves today: surrounded by vast quantities of data but unable to safely use it for the kinds of exploration that drive meaningful innovation.

Introducing Synthetic Data as an Innovation Enabler

Synthetic data generation is emerging as a powerful way to break this stalemate. Instead of relying exclusively on sensitive real-world datasets, organizations can generate artificial datasets that replicate the statistical patterns and relationships found in real data without exposing the underlying individuals or proprietary records.

In practical terms, synthetic data allows innovators to simulate realistic scenarios while protecting privacy and maintaining compliance. It creates a sandbox where teams can experiment freely, train algorithms safely, and test ideas that might otherwise remain locked behind regulatory or organizational barriers.

When used responsibly, synthetic data shifts the role of data within organizations. Instead of being merely a historical record of what has already happened, data becomes a tool for exploring what could happen next. That shift — from data as documentation to data as experimentation infrastructure — may prove to be one of the most important enablers of innovation in the years ahead.

II. What Synthetic Data Actually Is (And What It Is Not)

Before organizations can benefit from synthetic data, they must first understand what it actually is. Despite the growing buzz around the term, synthetic data is frequently misunderstood. Some assume it is simply “fake data.” Others believe it is the same thing as anonymized datasets. In reality, synthetic data represents a fundamentally different approach to creating usable information for experimentation, analysis, and innovation.

Synthetic data is artificially generated data that replicates the statistical patterns, relationships, and structures found in real-world datasets without containing the original records themselves. Instead of copying or masking existing information, advanced algorithms and generative models create entirely new data points that behave like the real data they are modeled after.

Think of it less like copying a photograph and more like creating a realistic simulation. The resulting dataset mirrors the dynamics of the original system, but the individual entries are newly generated rather than derived from specific real-world individuals or transactions.

How Synthetic Data Is Generated

Synthetic data generation relies on statistical modeling, machine learning, and increasingly sophisticated artificial intelligence techniques. These systems analyze real datasets to learn the underlying patterns that shape them — relationships between variables, probability distributions, and behavioral correlations.

Once those patterns are understood, generative models can produce new datasets that maintain the same statistical integrity without reproducing any specific original records. The goal is to preserve usefulness for analysis, experimentation, and algorithm training while removing the privacy risks associated with real data.

Several common techniques are used to generate synthetic datasets, including:

  • Statistical sampling models that reproduce probability distributions observed in real data.
  • Generative adversarial networks (GANs) that use competing neural networks to produce increasingly realistic synthetic records.
  • Agent-based simulations that model behaviors of individuals or systems over time.
  • Rule-based generation where domain knowledge is used to define realistic constraints and relationships.

The sophistication of the generation method determines how closely synthetic datasets resemble real-world behavior. High-quality synthetic data preserves meaningful patterns that allow data scientists, product teams, and innovators to test hypotheses with confidence.

Real Data vs. Anonymized Data vs. Synthetic Data

One of the most important distinctions leaders must understand is the difference between real data, anonymized data, and synthetic data. These three approaches represent very different levels of privacy protection and innovation flexibility.

Real data consists of original records collected from customers, users, transactions, or operational systems. This data often contains personally identifiable information or proprietary insights. While it is highly valuable for analysis, it also carries significant privacy, security, and regulatory obligations.

Anonymized data attempts to protect privacy by removing identifying details such as names, addresses, or account numbers. However, anonymization has limits. In many cases, individuals can still be re-identified by combining datasets or analyzing behavioral patterns. This risk has led to increasing regulatory scrutiny around anonymized data practices.

Synthetic data takes a different approach. Instead of modifying real records, it generates entirely new records that reflect the statistical properties of the original dataset. Because the generated data does not correspond to real individuals, the risk of re-identification is dramatically reduced when properly generated and validated.

The result is a dataset that retains analytical usefulness while minimizing exposure of sensitive information.

Why Synthetic Data Preserves Patterns Without Exposing People

The value of synthetic data lies in its ability to preserve the insights embedded in real data without exposing the underlying individuals or proprietary records. When generative models capture the relationships between variables — such as correlations between behaviors, outcomes, and environmental factors — they can recreate those relationships in newly generated datasets.

For example, a synthetic dataset used to train a financial fraud detection model might preserve patterns such as transaction timing, spending anomalies, and geographic patterns. However, none of the generated records would correspond to actual customer accounts or transactions.

In healthcare contexts, synthetic patient datasets can preserve relationships between symptoms, treatments, and outcomes without revealing the identity or medical history of any real patient. This allows researchers and developers to build and test models while protecting patient privacy.

The Strategic Value for Innovators

For innovation leaders, the significance of synthetic data extends far beyond technical curiosity. It represents a new way to think about data availability. Instead of asking, “What data do we have access to?” teams can begin asking, “What data do we need in order to explore this idea?”

Synthetic data generation makes it possible to create datasets tailored to the questions innovators want to explore. Teams can simulate rare events, expand limited datasets, or test entirely new scenarios that have not yet occurred in the real world.

In doing so, synthetic data shifts the role of data from a passive historical record to an active innovation tool. It allows organizations to move from analyzing yesterday’s behavior to safely experimenting with tomorrow’s possibilities.

III. The Innovation Bottleneck Synthetic Data Solves

Innovation depends on experimentation. Teams need the freedom to test ideas, simulate scenarios, and learn from outcomes before committing significant resources. Yet in many organizations, experimentation slows to a crawl not because of a lack of creativity, but because of a lack of accessible, usable data.

Data has become the raw material of modern innovation. Product teams rely on it to test features. Designers depend on it to understand behavior. Data scientists use it to train algorithms and predict outcomes. But when that data is restricted, incomplete, or difficult to access, experimentation stalls. The result is an invisible bottleneck that quietly limits the pace and scale of innovation.

Synthetic data generation addresses this bottleneck by creating safe, realistic datasets that enable organizations to experiment more freely while protecting privacy, maintaining compliance, and reducing operational friction.

Innovation Requires Safe Experimentation

The most innovative organizations treat experimentation as a continuous capability rather than an occasional initiative. Teams run simulations, prototype services, and test algorithms in order to discover what works and what does not. But experimentation requires environments where teams can explore ideas without exposing sensitive customer information or proprietary operational data.

When those safe environments do not exist, experimentation becomes constrained. Teams wait for approvals to access data. Compliance teams become gatekeepers rather than partners. Engineers spend more time navigating governance processes than testing new ideas.

Synthetic data provides a solution by enabling the creation of realistic datasets that can be used safely in testing environments. Instead of waiting for access to sensitive information, teams can immediately begin experimenting with datasets designed specifically for innovation.

Breaking Through Common Data Barriers

Several persistent barriers prevent organizations from fully leveraging their data for innovation. Synthetic data generation helps address each of these challenges in different ways.

  • Privacy and regulatory restrictions. Regulations governing personal and financial data rightfully impose strict limits on how information can be used. Synthetic datasets allow experimentation without exposing real individuals or sensitive records.
  • Limited access to sensitive datasets. In many organizations, only a small group of analysts or engineers are allowed to work with certain types of data. Synthetic versions of those datasets can be shared more broadly with product, design, and innovation teams.
  • Data silos across departments. Business units often maintain separate datasets that cannot easily be combined due to governance or competitive concerns. Synthetic data can be generated in ways that simulate cross-functional insights without exposing proprietary information.
  • Incomplete or inconsistent datasets. Real-world data frequently contains gaps, inconsistencies, and noise. Synthetic data generation can expand datasets to improve coverage and provide more balanced scenarios for experimentation.
  • Lack of edge cases and rare events. Many of the situations innovators need to test — such as fraud attempts, system failures, or unusual customer journeys — occur infrequently in real datasets. Synthetic data can intentionally generate these scenarios so teams can build more resilient solutions.

By removing these barriers, organizations create the conditions necessary for faster experimentation and more confident decision-making.

Enabling Ethical and Responsible AI Development

Artificial intelligence systems require large datasets to train effectively. However, using real-world data for AI training introduces significant ethical and regulatory risks. Sensitive customer information, financial transactions, healthcare records, and behavioral data must be handled with extreme care.

Synthetic data allows organizations to train and test AI systems using datasets that preserve behavioral patterns without exposing personal information. This approach enables developers to refine algorithms, test performance, and identify potential biases before deploying systems in real-world environments.

For organizations seeking to expand their use of AI responsibly, synthetic data can provide a safer pathway toward experimentation and model development.

Accelerating Cross-Team Collaboration

Innovation rarely occurs within a single department. It emerges from collaboration between product teams, designers, engineers, analysts, and business leaders. Yet when access to critical data is restricted, collaboration becomes fragmented.

Synthetic datasets can be shared across teams without exposing confidential or personally identifiable information. This makes it easier for diverse groups to explore ideas together, test new concepts, and build prototypes using realistic data environments.

When data becomes accessible in this way, organizations unlock a more inclusive form of innovation. Instead of limiting experimentation to specialized technical teams, synthetic data allows a broader range of contributors to participate in the discovery process.

Turning Data into an Innovation Platform

The real power of synthetic data lies in how it reframes the role of data inside the organization. Traditionally, data has been treated as a historical asset — a record of past transactions, customer interactions, and operational events. Synthetic data shifts that perspective.

By enabling teams to generate realistic datasets on demand, organizations transform data from a static archive into a dynamic experimentation platform. Teams can simulate scenarios that have never occurred, stress-test systems against unlikely events, and explore future possibilities long before those conditions appear in real life.

In a world where the speed of learning determines the pace of innovation, removing barriers to experimentation can become a powerful competitive advantage. Synthetic data does not eliminate the need for real-world data, but it dramatically expands the range of ideas organizations can safely explore before bringing them into reality.

IV. Four Strategic Use Cases That Matter to Innovators

Synthetic data becomes most valuable when it moves beyond technical experimentation and begins enabling real innovation work inside organizations. For leaders responsible for driving change, improving customer experiences, or building new products, the question is not simply whether synthetic data is possible. The question is where it creates meaningful strategic advantage.

Several emerging use cases are demonstrating how synthetic data can accelerate innovation while reducing risk. These applications allow organizations to explore new ideas safely, test systems more rigorously, and collaborate more effectively across teams.

Safe AI and Machine Learning Training

Artificial intelligence systems are only as good as the data used to train them. Machine learning models require large datasets that capture the complexity of real-world behavior. However, those datasets often contain sensitive customer information, financial records, or proprietary operational data that cannot be freely used for experimentation.

Synthetic data enables organizations to train AI models without exposing real customer information. By replicating the statistical patterns found in production datasets, synthetic datasets can provide the volume and diversity required for algorithm development while dramatically reducing privacy risks.

This approach is particularly valuable during early development stages, when teams need to experiment rapidly with different models, features, and training approaches. Instead of navigating lengthy approval processes to access restricted datasets, developers can begin training models using synthetic equivalents.

The result is faster iteration cycles, safer development environments, and a clearer pathway toward responsible AI deployment.

Simulating Future Customer Behavior

One of the greatest limitations of historical data is that it reflects past behavior rather than future possibilities. Innovation teams frequently need to explore how customers might respond to new products, services, or experiences that do not yet exist.

Synthetic data allows organizations to simulate potential customer behaviors by modeling how individuals might interact with new offerings under different conditions. By generating datasets that represent hypothetical scenarios, teams can test assumptions about demand, engagement, and usage patterns before launching a product into the real world.

This capability becomes especially valuable when organizations are exploring entirely new business models or digital experiences. Synthetic datasets can simulate user journeys, transaction flows, and interaction patterns that have never appeared in historical records.

While these simulations cannot perfectly predict human behavior, they provide innovators with a powerful way to explore possibilities and refine ideas before committing significant resources.

Accelerating Product and Service Design

Designers and product teams often struggle to obtain the kinds of datasets that would allow them to test ideas realistically. Early prototypes are frequently evaluated using small sample sizes, simplified assumptions, or limited testing environments.

Synthetic data can dramatically expand the realism of these testing environments. Product teams can generate datasets that reflect thousands or millions of simulated interactions, allowing them to stress-test designs against a wide range of user behaviors and operational conditions.

For example, a digital service prototype can be tested using synthetic user interaction data that simulates traffic spikes, diverse usage patterns, or unusual edge cases. This allows teams to identify usability issues, performance bottlenecks, and operational risks long before a product reaches customers.

By enabling richer testing environments earlier in the development process, synthetic data helps organizations reduce costly surprises later in the product lifecycle.

Breaking Down Data Silos

Data silos are one of the most persistent obstacles to innovation inside large organizations. Departments often maintain separate datasets that cannot be easily shared due to privacy concerns, competitive sensitivities, or governance restrictions.

These silos prevent teams from seeing the full picture of customer behavior, operational performance, or market dynamics. As a result, innovation efforts become fragmented, and opportunities for cross-functional insights are missed.

Synthetic data offers a pathway to collaboration without exposing sensitive information. Organizations can generate datasets that simulate cross-departmental insights while protecting the underlying proprietary or personal data contained within the original systems.

For example, a synthetic dataset could combine simulated customer interactions, transaction histories, and service experiences in ways that allow teams from marketing, product development, and operations to collaborate more effectively.

By enabling safe data sharing, synthetic data helps organizations move from isolated experimentation toward more integrated innovation ecosystems.

Creating an Innovation Sandbox

When organizations combine these use cases, synthetic data begins to function as something larger than a technical tool. It becomes the foundation of an innovation sandbox — a controlled environment where teams can safely explore ideas, test systems, and simulate complex scenarios.

In this sandbox, innovators are no longer limited by the constraints of real-world data access. They can generate the datasets needed to explore bold ideas, stress-test new concepts, and build solutions that are more resilient before they ever interact with real customers or operational systems.

For organizations committed to accelerating learning and experimentation, synthetic data has the potential to become one of the most powerful enablers of responsible, human-centered innovation.
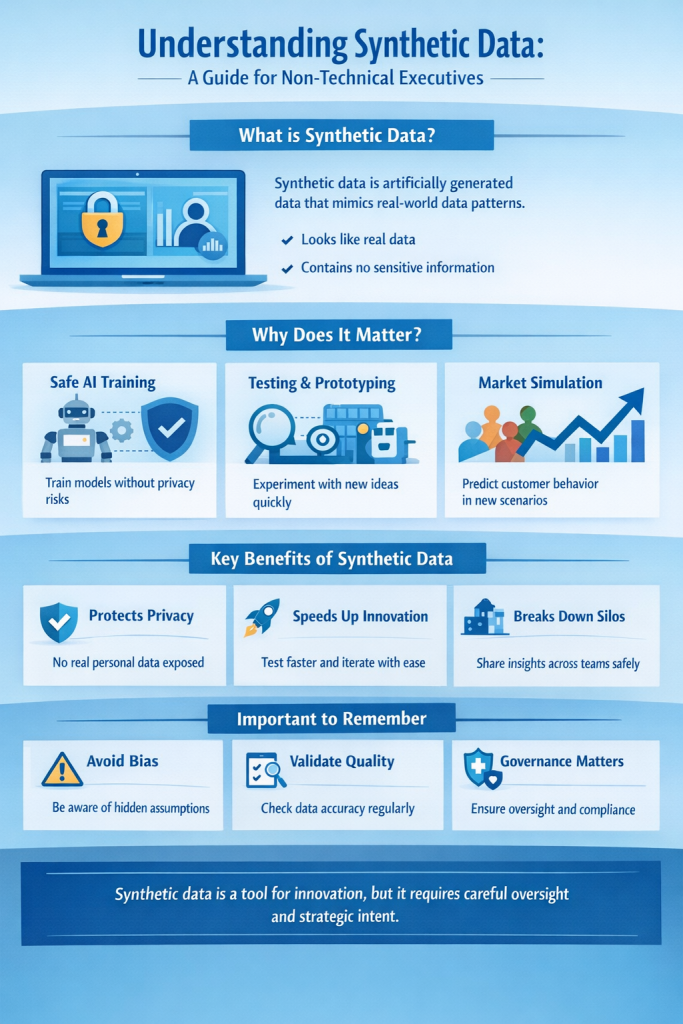
Synthetic Data Infographic

V. The Hidden Risk: Synthetic Data Can Amplify Bad Assumptions

Synthetic data is a powerful innovation enabler, but it is not inherently neutral. Like any system that relies on models, it reflects the assumptions, inputs, and design choices embedded within it. If those foundations are flawed, the outputs will be flawed as well.

For leaders committed to human-centered change, this is a critical point. Synthetic data does not automatically guarantee fairness, accuracy, or objectivity. It must be designed, validated, and governed with the same rigor applied to any strategic capability.

Synthetic Data Reflects the Model That Creates It

Synthetic datasets are generated using statistical models or machine learning systems trained on real-world data. These models learn patterns, correlations, and distributions from existing information. When they generate new records, they reproduce those learned patterns in artificial form.

This means synthetic data inherits the strengths and weaknesses of the source data and the model architecture. If the original dataset contains bias, gaps, or skewed representations, those characteristics may be preserved or even amplified in the synthetic output.

For example, if historical data under-represents certain customer segments, synthetic data generated from that dataset may also under-represent those segments unless corrective measures are applied during model training and validation.

Innovation leaders must therefore treat synthetic data as a designed artifact, not a neutral byproduct.

The Risk of Embedded Bias

Bias in data is not always intentional. It can emerge from historical inequalities, incomplete data collection practices, or operational decisions made over time. When organizations train models on biased datasets, those biases can become encoded into the synthetic data they generate.

If synthetic datasets are used to train artificial intelligence systems, test products, or simulate customer behavior, embedded bias can propagate into downstream decisions. This can affect hiring tools, credit models, customer segmentation strategies, or product design choices.

The result may not be immediately visible. Synthetic data can appear statistically sound while still reinforcing structural imbalances present in the source data.

Responsible innovation therefore requires deliberate efforts to audit synthetic datasets for representation, fairness, and alignment with organizational values.

The Importance of Validation and Governance

To mitigate risk, organizations must implement clear validation processes for synthetic data generation. Validation ensures that the synthetic dataset accurately reflects relevant statistical properties without reproducing sensitive information or unintended distortions.

Effective governance practices may include:

  • Comparing synthetic and real datasets to evaluate statistical similarity.
  • Testing models trained on synthetic data against real-world benchmarks.
  • Conducting bias and fairness assessments before deployment.
  • Documenting model design decisions and data generation methods.
  • Establishing cross-functional oversight involving data science, compliance, and business stakeholders.

These practices help ensure that synthetic data enhances innovation without compromising ethical standards or organizational integrity.

Human Oversight Remains Essential

Synthetic data generation is a technical process, but its impact is organizational and societal. Human judgment must remain central to how synthetic datasets are designed, validated, and applied.

Innovation leaders should resist the temptation to treat synthetic data as a fully autonomous solution. Instead, it should be viewed as a collaborative capability that combines computational power with human insight.

Domain experts can help define realistic constraints. Compliance teams can identify regulatory requirements. Designers can assess whether simulated scenarios reflect meaningful user experiences. Together, these perspectives ensure that synthetic data aligns with both operational goals and human values.

Designing Synthetic Data with Intent

The most effective synthetic data strategies begin with clear intent. Organizations should ask:

  • What decisions will this dataset support?
  • What risks must it mitigate?
  • What populations or scenarios must it accurately represent?
  • How will we measure quality and reliability?

By framing synthetic data as a designed innovation asset rather than a purely technical output, organizations increase the likelihood that it will strengthen rather than distort decision-making.

Innovation Without Responsibility Is Not Innovation

Synthetic data has the potential to accelerate experimentation, reduce privacy risk, and expand collaboration. But those benefits depend on thoughtful implementation. When organizations pair technical capability with ethical governance, synthetic data becomes a powerful catalyst for human-centered innovation.

The goal is not simply to generate more data. The goal is to generate better conditions for learning, experimentation, and progress — while ensuring that the systems we build reflect the values we intend to uphold.

VI. Why Synthetic Data Is a Strategic Capability (Not Just a Technical Tool)

Many organizations initially approach synthetic data as a niche technical solution — something useful for data scientists, compliance teams, or AI engineers. But when viewed through the lens of innovation and organizational change, synthetic data is far more than a utility. It is a strategic capability that reshapes how experimentation, collaboration, and decision-making occur across the enterprise.

Strategic capabilities are not isolated tools. They are infrastructure-level advantages that enable new behaviors, new business models, and new forms of value creation. Synthetic data belongs in this category because it fundamentally changes what teams can safely test, explore, and learn.

From Data Access to Data Creation

Traditional data strategies focus on access: Who can see the data? Who can use it? What permissions are required? While governance is essential, this access-centric mindset can unintentionally limit innovation speed.

Synthetic data shifts the conversation from access to creation. Instead of asking for permission to use sensitive datasets, teams can generate purpose-built datasets designed specifically for experimentation, simulation, and model development.

This transformation is profound. Data becomes something organizations can intentionally design to support innovation goals rather than something they must carefully guard and ration.

Enabling Faster Learning Cycles

Innovation thrives on short learning cycles. The faster teams can test ideas, gather feedback, and iterate, the faster they can improve outcomes. Synthetic data accelerates these cycles by removing friction associated with data access, privacy approvals, and cross-departmental restrictions.

When teams can immediately generate realistic datasets, they can:

  • Prototype new features without waiting for production data access.
  • Test algorithm changes in controlled environments.
  • Simulate customer journeys under varying conditions.
  • Stress-test systems before deployment.

These capabilities compress the time between idea and insight. That compression becomes a competitive advantage in fast-moving markets.

Supporting Responsible Innovation at Scale

As organizations expand their use of artificial intelligence, automation, and predictive analytics, the demand for high-quality training data increases. However, relying exclusively on real-world data can introduce privacy risks and compliance challenges that slow adoption.

Synthetic data provides a scalable foundation for responsible innovation. By generating datasets that preserve statistical patterns without exposing sensitive records, organizations can expand experimentation without expanding risk proportionally.

This scalability is especially important for global organizations operating across jurisdictions with varying regulatory requirements. Synthetic data can serve as a common innovation substrate that respects privacy while enabling cross-border collaboration.

Shifting from Reactive to Proactive Strategy

Many organizations use data reactively — analyzing past performance to explain what has already happened. While valuable, this approach limits strategic agility. Leaders who rely solely on historical data may struggle to anticipate emerging risks or opportunities.

Synthetic data enables proactive exploration. Teams can generate scenarios that have not yet occurred and evaluate potential responses in advance. This allows organizations to simulate market shifts, operational disruptions, or new customer behaviors before those changes materialize.

By moving from reactive analysis to proactive simulation, synthetic data helps organizations prepare for uncertainty rather than simply respond to it.

Embedding Innovation Infrastructure

When synthetic data capabilities are integrated into development pipelines, experimentation workflows, and governance frameworks, they become part of the organization’s core infrastructure.

This integration transforms synthetic data from a one-off project into an enduring innovation asset. It supports:

  • Continuous experimentation environments.
  • Secure collaboration across departments.
  • Responsible AI development pipelines.
  • Scalable simulation capabilities.

In this sense, synthetic data is not just a technical enhancement. It is an enabling layer that strengthens the organization’s capacity to learn, adapt, and evolve.

From Constraint to Competitive Advantage

Organizations that treat data restrictions as permanent constraints may find themselves limited in their ability to experiment. Organizations that invest in synthetic data capabilities, however, can transform those constraints into opportunities for structured innovation.

By enabling safe experimentation, cross-functional collaboration, and scalable simulation, synthetic data becomes a catalyst for organizational agility.

In a world where adaptability determines long-term success, the ability to create realistic, privacy-preserving datasets on demand is more than a convenience. It is a strategic differentiator.

Synthetic data does not replace real-world insights. Instead, it expands the conditions under which innovation can occur — allowing teams to test ideas earlier, learn faster, and move forward with greater confidence.

VII. Five Questions Leaders Should Ask Before Investing

Technology decisions become transformative only when they are guided by clear strategic intent. Synthetic data is no exception. Before investing in tools, platforms, or models, leaders should pause to define the innovation outcomes they want to enable and the risks they need to manage.

The following questions are designed to help executives, innovation leaders, and cross-functional teams evaluate whether synthetic data is aligned with their organizational goals.

1. What Innovation Experiments Are Currently Blocked by Lack of Data?

Every organization has ideas that never move forward because the necessary data is inaccessible, restricted, or incomplete. Identifying these stalled experiments is the first step toward understanding where synthetic data could create immediate value.

Leaders should ask:

  • Which product concepts cannot be tested due to privacy or compliance constraints?
  • Which AI initiatives are delayed because training data is difficult to access?
  • Which simulations would we run if data were not a barrier?

By mapping innovation bottlenecks to data constraints, organizations can prioritize synthetic data use cases that unlock real momentum rather than pursuing technology for its own sake.

2. Which Datasets Are Too Sensitive to Use Today?

Many organizations hold valuable datasets that contain personally identifiable information, financial records, or proprietary insights. These datasets are often tightly restricted, limiting their use in experimentation environments.

Leaders should identify where sensitivity prevents productive exploration:

  • Customer behavior datasets that cannot be shared across teams.
  • Operational performance data restricted to a small group of analysts.
  • Cross-border data that faces regulatory limitations.

Synthetic data can create privacy-preserving alternatives that retain statistical value without exposing sensitive information. Recognizing these high-sensitivity areas helps organizations target the greatest opportunities for impact.

3. Where Do We Need Rare Scenarios or Edge Cases?

Innovation often requires testing conditions that occur infrequently in real life. Edge cases — such as system overloads, unusual customer journeys, or rare fraud patterns — may not appear often enough in historical data to support thorough analysis.

Synthetic data can intentionally generate these scenarios so teams can stress-test systems, refine algorithms, and improve resilience.

Leaders should consider:

  • What rare events would most impact our customers or operations?
  • Which scenarios are underrepresented in our existing datasets?
  • How could we simulate future risks before they occur?

By proactively modeling these conditions, organizations can build more robust solutions and reduce unexpected failures.

4. How Will We Validate Synthetic Data Quality?

Synthetic data is only valuable if it accurately reflects the statistical relationships and constraints relevant to its intended use. Without validation, organizations risk deploying datasets that appear realistic but fail to support meaningful experimentation.

Leaders should define:

  • What metrics will determine whether the synthetic dataset is fit for purpose?
  • How will we compare synthetic and real datasets for statistical similarity?
  • Who is responsible for ongoing model evaluation and monitoring?

Establishing validation standards ensures synthetic data strengthens innovation rather than introducing unintended distortions.

5. Who Owns Synthetic Data Governance?

As synthetic data becomes integrated into development pipelines and experimentation environments, governance becomes critical. Clear ownership prevents confusion and ensures accountability.

Leaders should define:

  • Which teams oversee model design and updates?
  • How are bias, fairness, and compliance reviews conducted?
  • What documentation standards apply to synthetic data generation?

Effective governance should involve collaboration between data science, compliance, legal, product, and innovation teams. This cross-functional approach ensures that synthetic data aligns with organizational values and regulatory requirements.

From Questions to Strategy

These five questions are not meant to slow adoption. They are meant to ensure alignment. When leaders clearly understand where synthetic data can remove barriers, accelerate experimentation, and improve safety, investment decisions become more focused and impactful.

Synthetic data is most powerful when it is embedded within a broader innovation strategy. By identifying blocked experiments, sensitive datasets, edge-case needs, validation standards, and governance ownership, organizations can move from curiosity to capability.

The goal is not to implement synthetic data everywhere. The goal is to implement it where it meaningfully increases the organization’s ability to learn, adapt, and innovate responsibly.

VIII. The Future: From Data Scarcity to Innovation Abundance

For decades, organizations have operated under a mindset of data scarcity. Data was expensive to collect, difficult to store, and constrained by technical limitations. Even today, despite vast cloud infrastructure and advanced analytics platforms, many teams still experience data as something limited, gated, or difficult to access.

Synthetic data generation introduces a different paradigm — one that shifts the conversation from scarcity to abundance. Instead of waiting for enough real-world examples to accumulate, organizations can intentionally generate datasets that enable exploration, simulation, and experimentation at scale.

This shift does not eliminate the need for real data. Real-world observations remain essential for grounding models, validating assumptions, and ensuring relevance. However, synthetic data expands what is possible between observations. It fills gaps, creates safe testing environments, and enables forward-looking exploration.

Re-framing Data as a Future-Oriented Asset

Traditional data strategies emphasize historical analysis—understanding performance, identifying trends, and explaining outcomes. While valuable, this backward-looking orientation can limit an organization’s ability to anticipate change.

Synthetic data encourages a forward-looking mindset. Teams can generate scenarios that represent potential futures rather than relying solely on what has already occurred. This capability allows innovators to test hypotheses, simulate market shifts, and evaluate strategic options before committing resources.

When data becomes something organizations can create on demand, it transitions from being a passive record to an active design input. That transition fundamentally changes how teams approach experimentation and planning.

Expanding the Boundaries of Experimentation

In a data-abundant environment, experimentation is no longer constrained by dataset size or access limitations. Teams can generate large-scale synthetic datasets to support stress testing, algorithm refinement, and scenario modeling.

This expanded experimentation capacity enables organizations to:

  • Simulate extreme conditions and rare events.
  • Test multiple variations of a product or service before launch.
  • Explore new business models without exposing sensitive information.
  • Run parallel experiments across teams using consistent, privacy-preserving data.

By lowering the cost and friction of experimentation, synthetic data helps shift organizational culture toward continuous learning.

Supporting Responsible Innovation at Scale

As organizations adopt artificial intelligence, automation, and predictive systems more broadly, the demand for high-quality training and testing data grows exponentially. Scaling responsibly requires solutions that balance innovation speed with privacy, compliance, and ethical considerations.

Synthetic data provides a scalable mechanism for supporting innovation initiatives across departments, geographies, and regulatory environments. It enables teams to collaborate using realistic datasets without exposing sensitive information, allowing experimentation to expand without proportionally increasing risk.

This scalability is particularly important in global enterprises where data governance requirements vary across jurisdictions. Synthetic data can serve as a consistent foundation for innovation while respecting local compliance constraints.

Reducing Friction in Innovation Pipelines

Many organizations experience delays not because of a lack of ideas, but because of operational friction in moving from concept to testing. Data approvals, access requests, and compliance reviews can slow experimentation cycles.

By integrating synthetic data into development and innovation workflows, organizations reduce these delays. Teams can generate appropriate datasets directly within controlled environments, accelerating the path from hypothesis to validation.

When friction decreases, learning accelerates. When learning accelerates, innovation compounds.

From Data Infrastructure to Innovation Infrastructure

The long-term impact of synthetic data is not just technical — it is structural. Organizations that embed synthetic data capabilities into their core systems are effectively building innovation infrastructure.

This infrastructure supports:

  • Continuous experimentation environments.
  • Privacy-preserving collaboration across functions.
  • Rapid prototyping with realistic simulations.
  • Forward-looking scenario modeling.

Over time, this capability can transform how organizations think about risk, experimentation, and strategic planning. Instead of treating innovation as a series of isolated initiatives, they can design systems that continuously generate insights and opportunities.

A Shift in Mindset

The move from data scarcity to data abundance requires more than technology adoption. It requires a mindset shift. Leaders must begin to see data not only as something to protect and analyze, but also as something that can be intentionally generated to enable exploration.

In this future-oriented model, synthetic data becomes a bridge between imagination and implementation. It allows teams to explore bold ideas safely, refine them through simulation, and bring them into the real world with greater confidence.

When organizations embrace this perspective, they expand their capacity to learn, adapt, and innovate in environments defined by uncertainty. Synthetic data does not replace reality — it helps organizations prepare for it.
Strategic Framework for Synthetic Data

Closing Thought

Innovation has always depended on imagination. What is changing in the modern era is the ability to test that imagination safely, quickly, and at scale. Synthetic data generation represents more than a technical advancement — it represents an expansion of what organizations can responsibly explore.

When used thoughtfully, synthetic data helps teams move beyond the limits of historical datasets. It enables experimentation without exposing sensitive information, supports collaboration across silos, and creates environments where new ideas can be evaluated before they reach customers or production systems.

But the real opportunity is not simply to generate more data. The opportunity is to generate better conditions for learning. Innovation thrives where curiosity is encouraged, where experimentation is safe, and where insights can be tested without unnecessary friction.

Synthetic data becomes powerful when it is aligned with human-centered principles — when it strengthens privacy, improves access to experimentation, and supports responsible decision-making. It should not replace real-world understanding, but rather complement it, expanding the space in which discovery can occur.

In the end, organizations that treat synthetic data as part of their innovation infrastructure are not just adopting a new tool. They are building a capability that allows them to learn faster, adapt more confidently, and pursue bolder ideas with greater responsibility.

The future of innovation will belong to organizations that can balance rigor with imagination — and synthetic data, applied wisely, can help make that balance possible.

Frequently Asked Questions About Synthetic Data

What is synthetic data and why does it matter for innovation?

Synthetic data is artificially generated data that mimics the statistical patterns and structure of real-world datasets without exposing actual individuals or sensitive records. It allows organizations to experiment, train AI systems, and test new ideas even when real data is limited, restricted, or too sensitive to use. For innovation leaders, synthetic data creates a safe environment to explore possibilities, simulate future scenarios, and accelerate experimentation without compromising privacy or compliance.

How is synthetic data different from anonymized data?

Anonymized data begins as real data and then removes or masks identifying information. While this reduces risk, it can still leave traces that may be re-identified in some circumstances. Synthetic data, on the other hand, is generated by models that reproduce patterns found in real datasets without copying actual records. The result is a dataset that behaves like real data but does not contain real people or events, making it far safer for experimentation, collaboration, and AI training.

What should leaders consider before investing in synthetic data?

Leaders should view synthetic data as a strategic capability rather than just a technical tool. Key considerations include identifying innovation initiatives currently blocked by limited or sensitive data, ensuring proper validation of synthetic datasets, establishing governance over how synthetic data is generated and used, and confirming that the models creating the data do not unintentionally amplify bias. When implemented responsibly, synthetic data can significantly expand an organization’s ability to experiment and innovate.


Disclaimer: This article speculates on the potential future applications of cutting-edge scientific research. While based on current scientific understanding, the practical realization of these concepts may vary in timeline and feasibility and are subject to ongoing research and development.

Image credits: ChatGPT
Subscribe to Human-Centered Change & Innovation WeeklySign up here to get Human-Centered Change & Innovation Weekly delivered to your inbox every week.